Share & Export
Exports: dashboards and reports
Dashboard exports
Section titled “Dashboard exports”In the editor, Share’s arrow (More sharing actions) offers three formats; in the viewer, Export in the dashboard’s header offers them too:
| Format | What you get |
|---|---|
| Image (PNG) | the live grid rasterized to one image |
| uniform A4 landscape pages; every dashboard page included | |
| PowerPoint (PPTX) | a title slide (name, date, link back to the live dashboard), then 16:9 slides per page |
Two behaviors make these presentable rather than screenshot-grade:
- Card-boundary pagination — when a page is taller than one sheet/slide, it’s sliced between cards, never through the middle of a chart (only a card taller than a whole page ever spans one).
- Render gate — the export waits until every card has finished loading and chart animations have settled, so you never export a skeleton.
Files are named after the dashboard and dated.
A dashboard sent on a schedule or by subscription is drawn on the server instead. In the PDF, PowerPoint and Excel files, an image card with picture options comes out with them, in its fit and with its border in the dashboard’s colours; an image card without them shows its whole picture, whatever its fit. PowerPoint and Excel name each picture by its alt text, or by the card’s title when it has none.
Drawn on the server, a card that reads a saved query comes out in the PDF and PowerPoint files as its chart, as it does on screen, never as a table of the query’s rows: a chart in the card’s own colours, or a KPI’s value and the line it compares with (a scheduled Excel file holds a picture of the chart). The page’s filters, and the ones the file was made with, reach it as they do on screen. A Table card, and a card that maps no value yet, are its rows. When the file’s read of the query stops at the row limit, the chart or the KPI says so beneath it in every file, as a table does: Showing first N rows — more rows exist, N the rows it was drawn from. A chart’s own Limit (its top N) is the rows you asked for, and says nothing.
Arabic and Hebrew in a dashboard’s or a report’s PDF are set in Noto Sans Arabic and Noto Sans Hebrew and ordered as a deck’s PDF orders them. A paragraph whose first letter is Arabic or Hebrew is set right to left and lined up at the right, as an Arabic or Hebrew reader reads it, with its numbers and Latin words where that order puts them, and a list item’s bullet at its right. The app lays the same paragraph out left to right, so a line that mixes Arabic or Hebrew with numbers or Latin words can stand in another order there than in the PDF. Searching or copying the PDF gives its words. A chart’s Arabic or Hebrew labels are drawn as outlines, which the PDF can’t search.
In Word, PowerPoint and Excel files, a link opens only a web page (http,
https) or an email (mailto); any other link keeps its words without the link.
A control character pasted into a title, a label or a value is written as a
space, so the file opens.
Export from the viewer
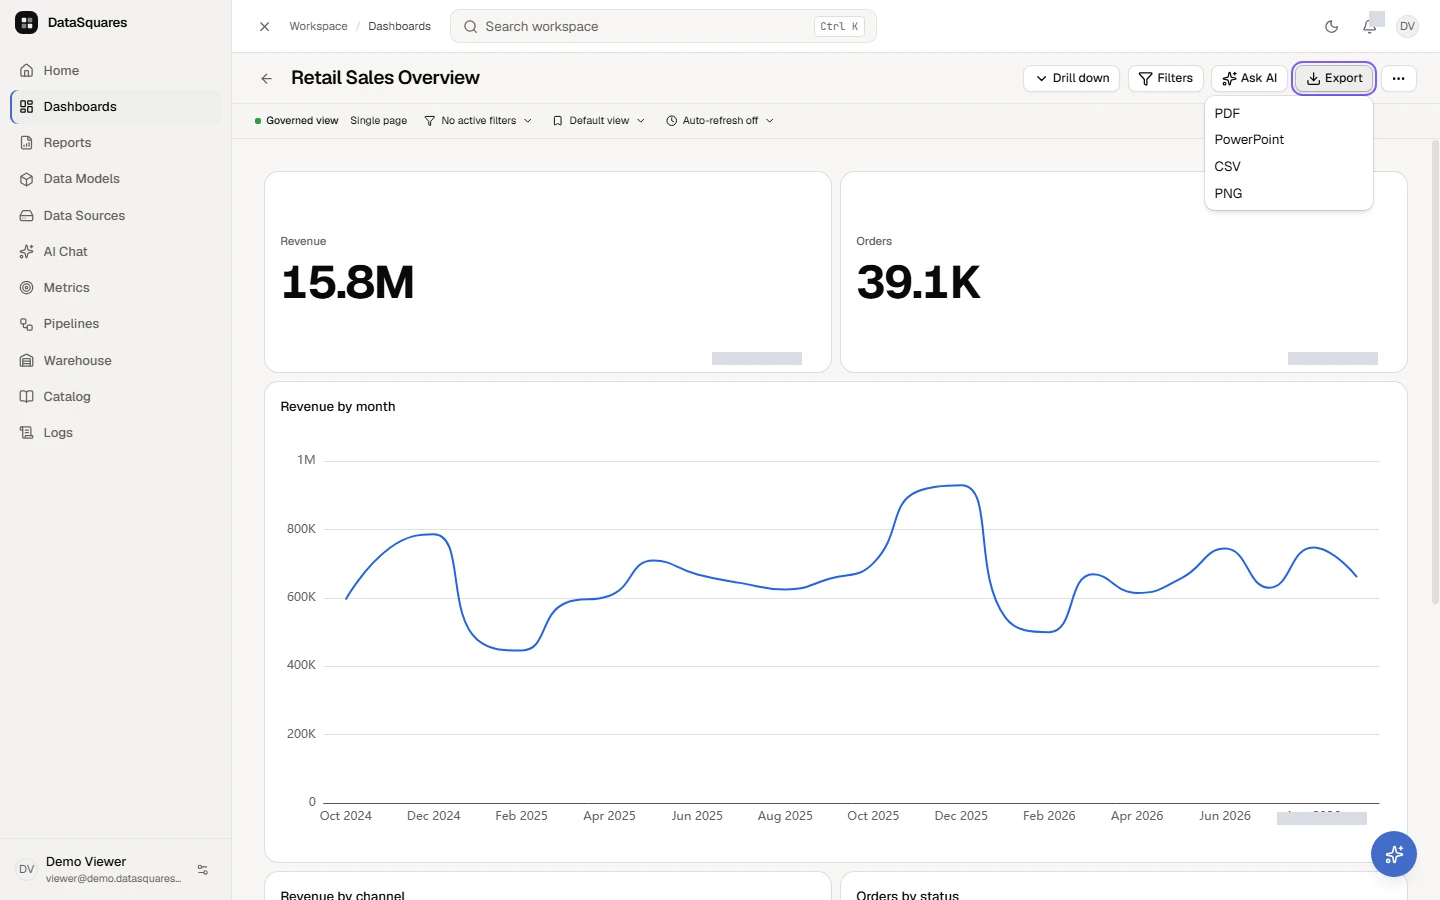
Section titled “Export from the viewer”Anyone who can open a dashboard can export it from the Export menu in the header. The viewer’s menu offers PDF, PowerPoint, CSV and PNG. There is no Excel option there: Excel is available for reports and as a format for scheduled and subscribed deliveries.
Choose Export in the header. The menu offers PDF, PowerPoint, CSV and PNG.
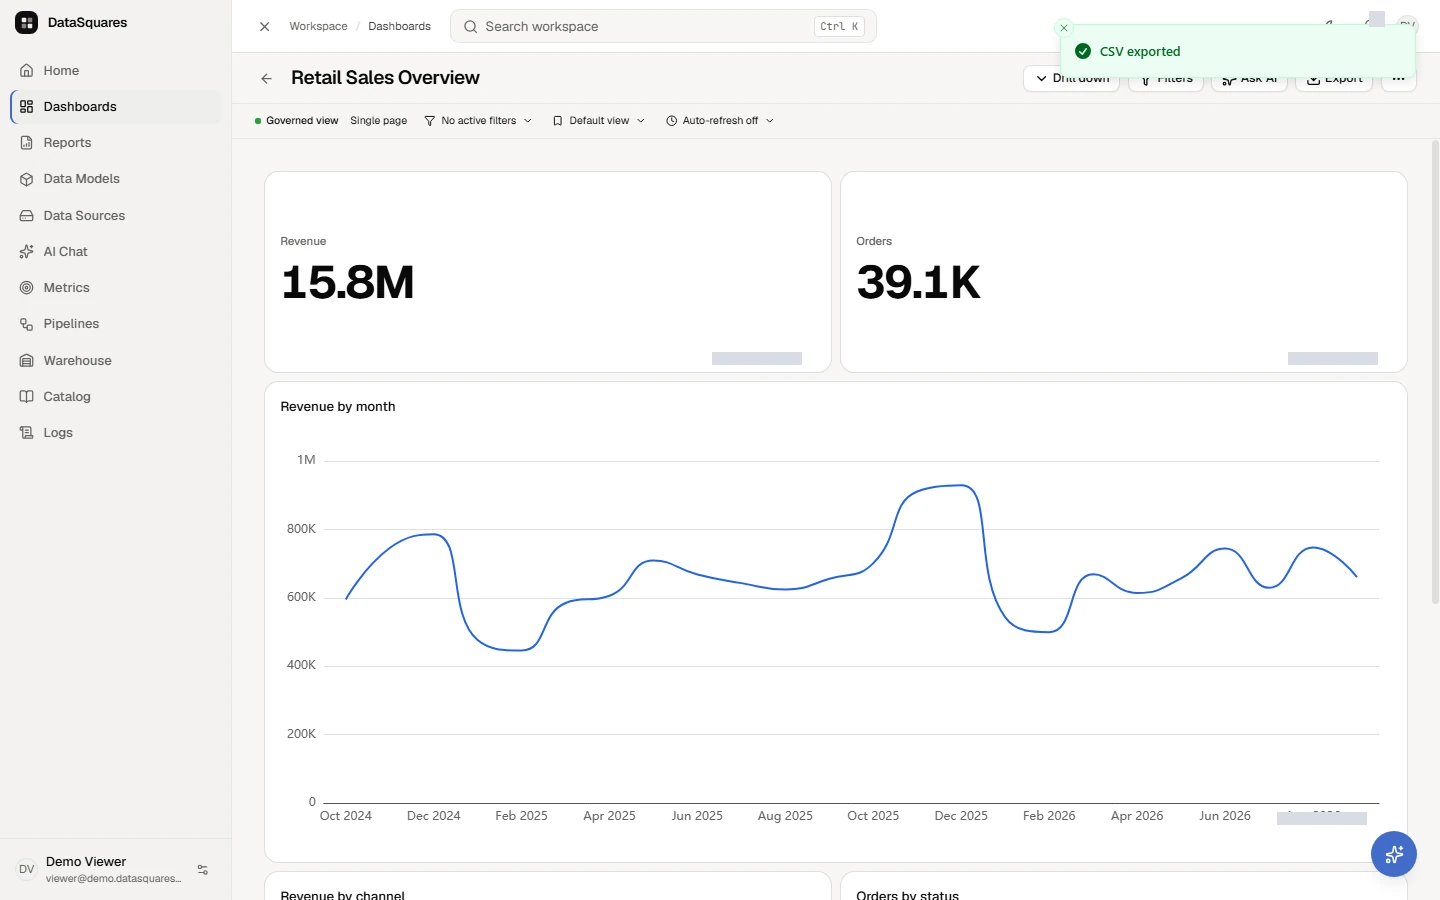
Choose a format, for example CSV. DataSquares confirms with CSV exported and your browser downloads the file. The export respects any filters you have set.
Walkthrough: email a dashboard on a schedule
Section titled “Walkthrough: email a dashboard on a schedule”The local test install has no mail server, so the pictures show the schedule being set up; the delivery history stays empty.
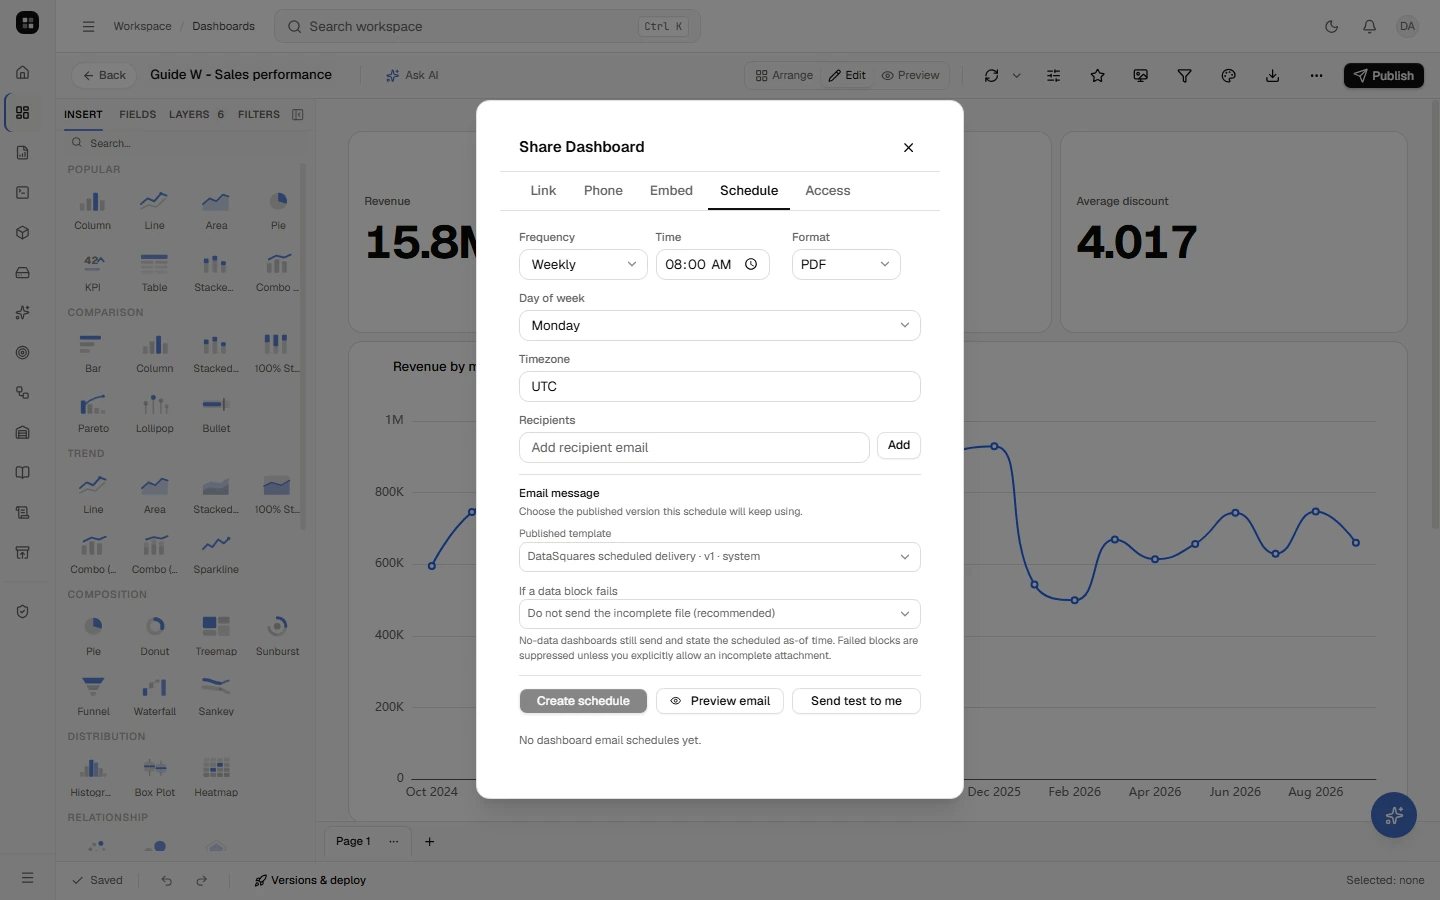
Choose Share, then the Schedule tab. This is where the dashboard is set up to be emailed on a repeating cadence.
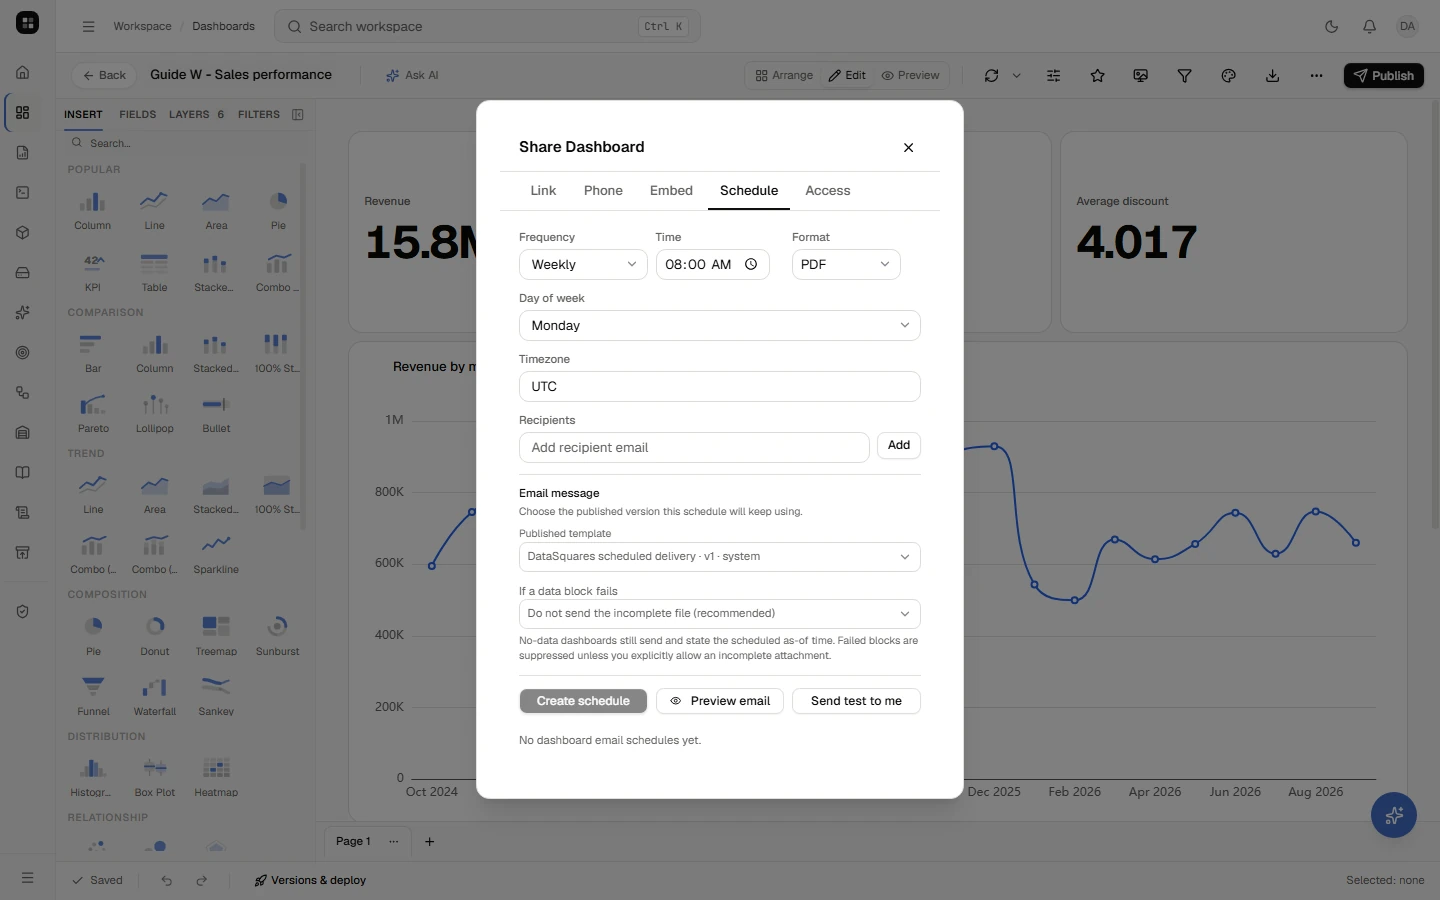
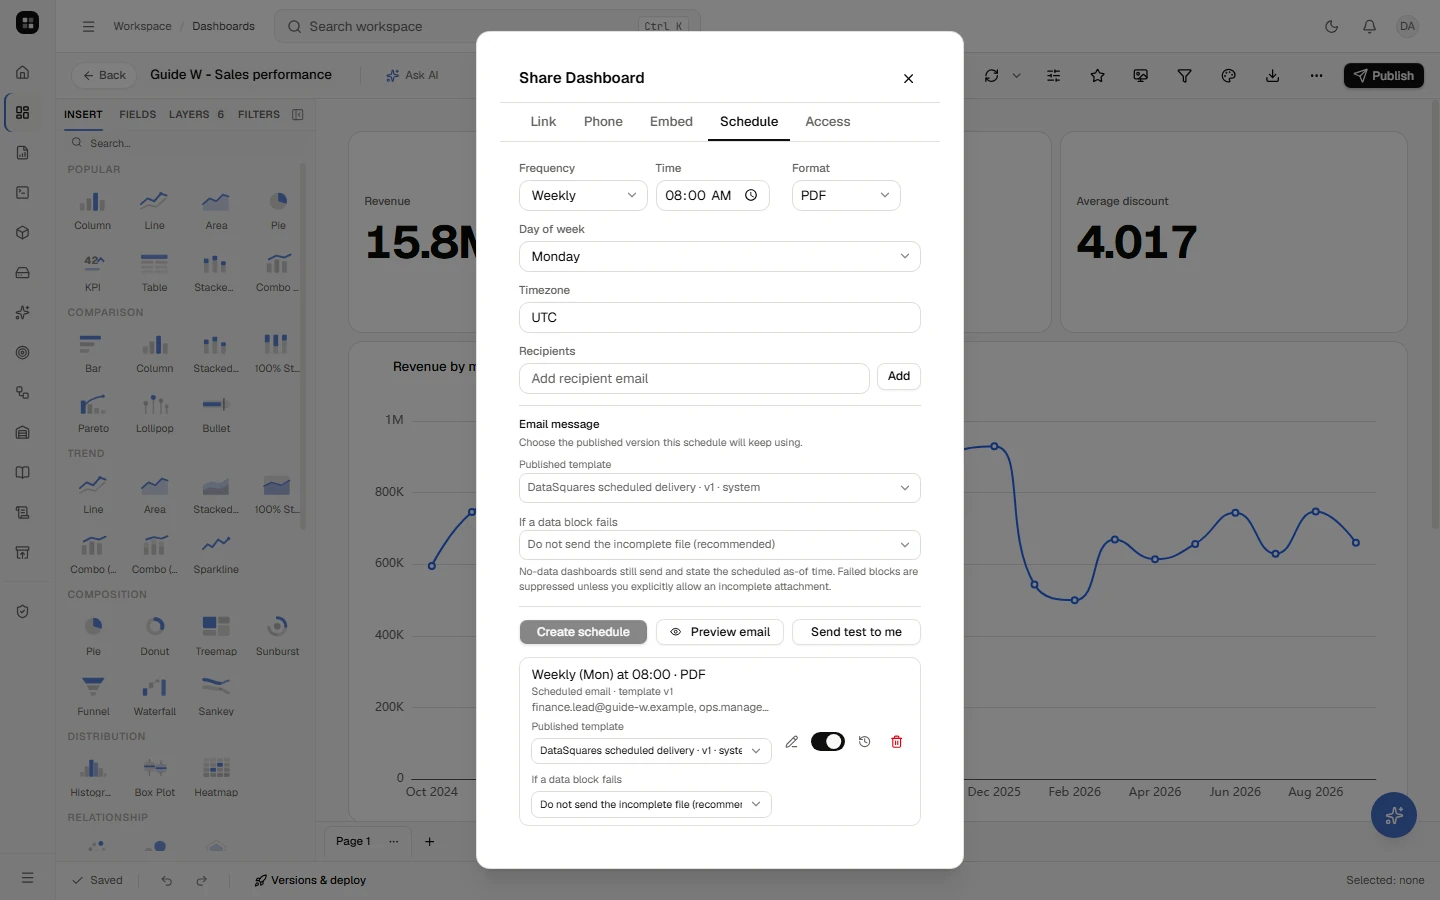
Choose how often (Daily, Weekly or Monthly), the time, the time zone and the file format (PDF, Excel, CSV, PowerPoint or Word). Add each recipient's email address with Add.
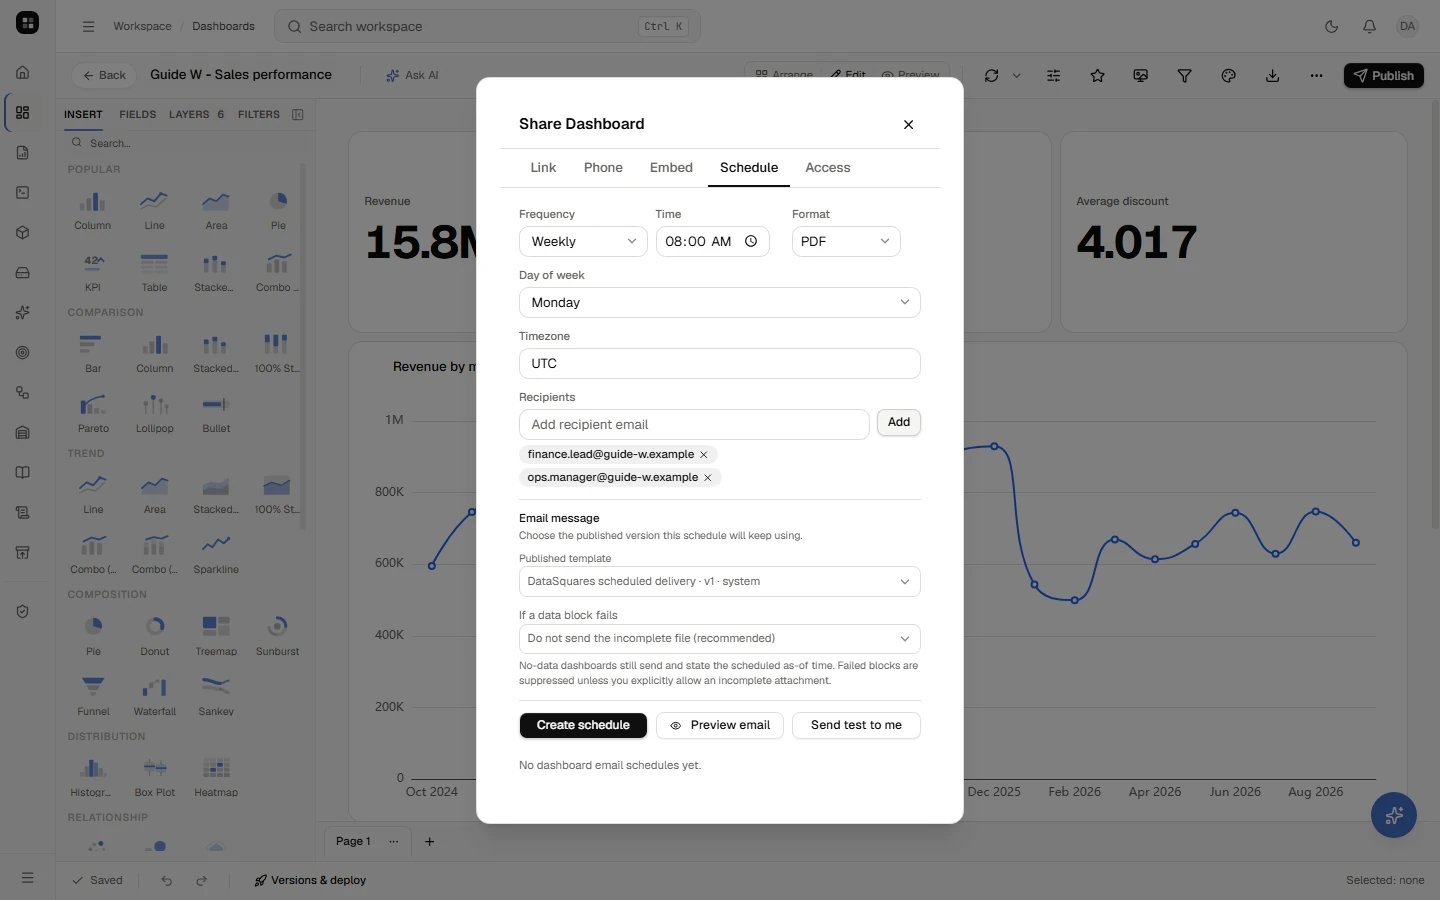
Preview email shows the message the recipients will get, so you can check it before anything is sent. If a block of the dashboard fails to render, the setting above it decides whether the file is held back (recommended) or sent with a warning.
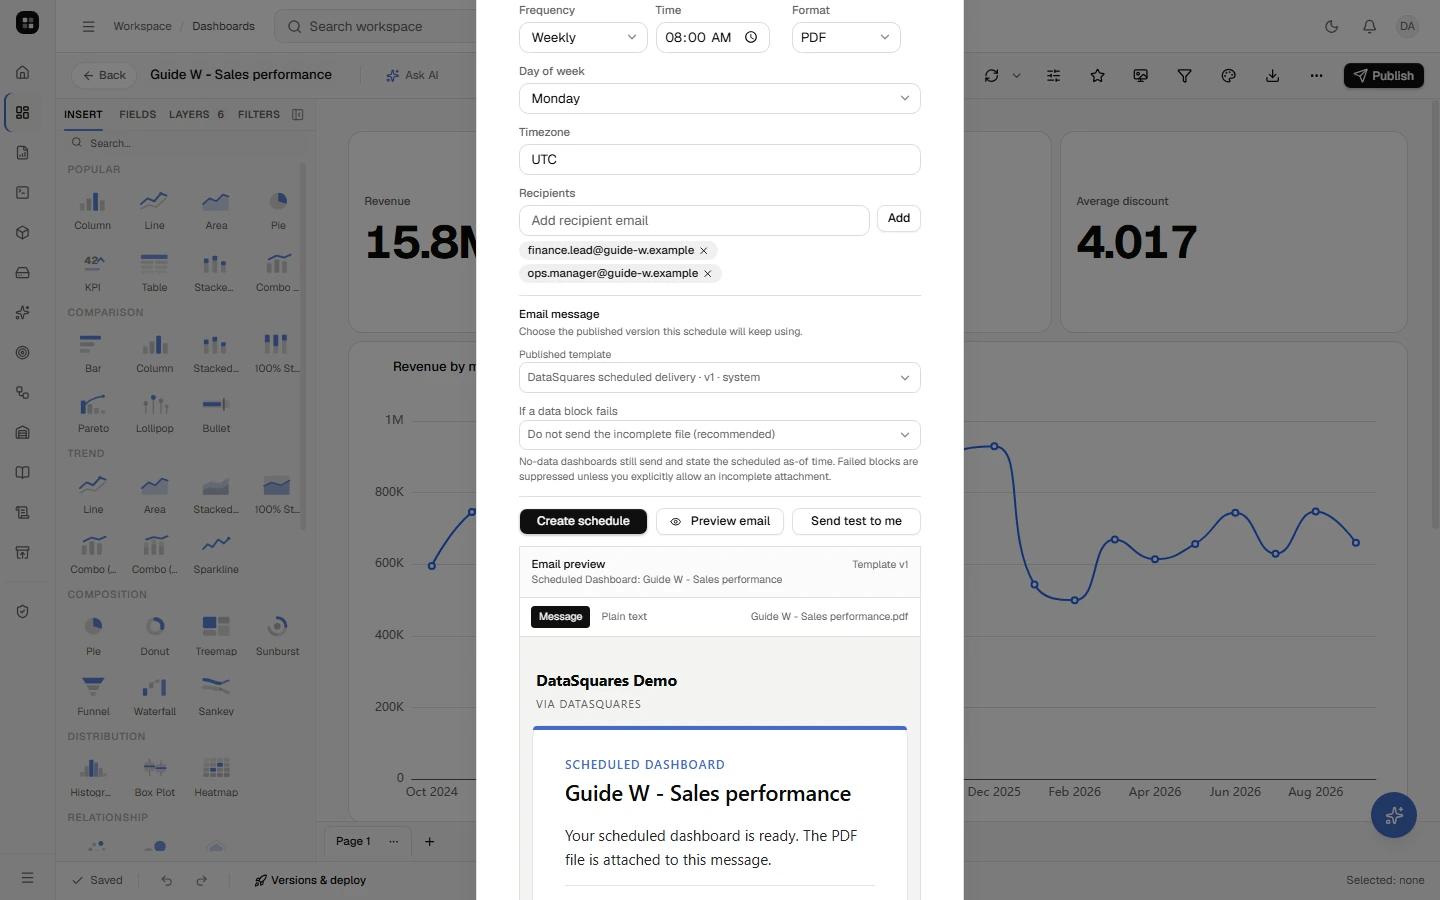
Choose Create schedule. DataSquares emails the dashboard to the recipients on that cadence. The schedule is listed with buttons to edit it, pause it, open its Delivery history (each send and whether it succeeded) and delete it.
Delete schedule stops the emails. The dashboard itself is not changed.
- Hovering a card in the viewer offers Download CSV for that card’s data.
- Export all to CSV combines every card’s data from the dashboard.
Report exports
Section titled “Report exports”The available choices depend on the report kind. Both honor saved filters and the supplied report parameters under the applicable data permissions.
| Report kind | Download choices | Definition and layout |
|---|---|---|
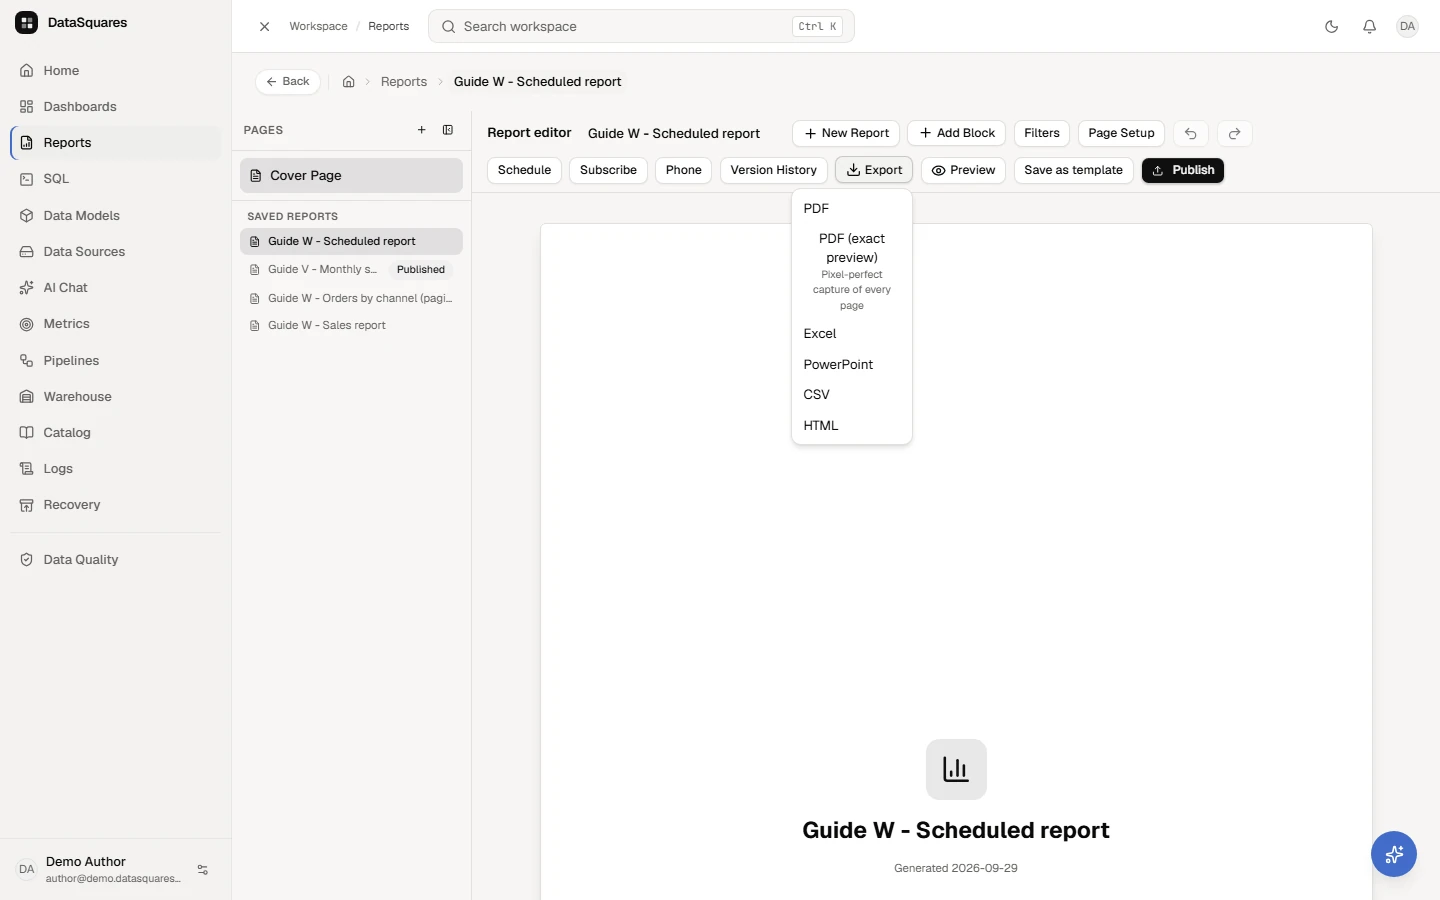
| Standard block report | PDF, PDF (exact preview), Excel, PowerPoint, CSV, HTML | Exact preview captures the displayed pages. Standard page setup includes A4, Letter and Legal. |
| Paginated table or document | Export… (in Share’s arrow) → PDF, HTML, Excel, CSV, Word, PowerPoint | Uses the saved definition and current run parameters. Paper is A4/Letter or an authored measured custom size. |
For paginated reports, Preview PDF renders the current draft. Save edits before choosing Export… or scheduling. The format menu in each delivery flow is authoritative; do not assume the standard editor’s exact-preview capture is a scheduled server format. See paginated authoring.
Paginated format differences
Section titled “Paginated format differences”| Format | What to expect |
|---|---|
| Physical pages with measured rows, repeated headings/bands and wide-table column sets. Review shortening or partial-data notices. | |
| HTML | A self-contained document with report sections and values. Browser printing can paginate differently from PDF. |
| Excel | Typed table values, preserving precision-sensitive numbers/identifiers as text when needed. It is a workbook, not a copy of the printed page. |
| CSV | Tabular values, without print layout, graphics or spreadsheet formatting. Read section/status information; do not sum subtotal and detail records together. |
| Word | Editable flowing tables and text, paper/margins, repeated bands and document page numbers. Word controls physical pagination. |
| PowerPoint | Slide-oriented sections and table continuations. It does not reproduce every PDF page-layout behavior. |
Word supports wide tables as column sets with repeated identifier columns. It flows down each set, wraps/grows rows and uses document-wide page numbers. PDF’s across-then-down order, per-set numbering, fixed row heights and repeated group bands are not reproduced. A single long row may continue to another page without repeating its identifier cell. Paper must fit Word’s 22-inch limit; margins may increase to protect page bands. Charts are images with adjacent values. Run Report checks for Word and inspect the actual file in your intended client.
On-demand downloads can include explicit incomplete-result information when sections fail or source results are capped. Read the warning shown after download and the file’s notices. A file extension or a visible grand total does not establish that all source rows were captured.
Dates and times in CSV and Excel
Section titled “Dates and times in CSV and Excel”Report downloads, scheduled report and dashboard deliveries, and background exports write a date or time column by the same rules, whatever the report kind:
- CSV writes text. A timestamp is written in UTC, to the millisecond when it
has one:
2026-10-15 12:34:56.789,2026-10-15 12:34:56on a whole second, and the date alone at midnight. A source that sends its timestamps as text, such as ClickHouse, Trino or DuckDB, has that text written as it came, every digit kept. - Excel writes a date cell, which sorts, filters and calculates as a date, in
the workspace’s Date format and Default timezone
(Settings). Its number format shows the time to the precision
the value has:
18:04on a whole minute,18:04:56on a whole second,18:04:56.789with milliseconds. Excel dates go no finer than the millisecond. A timestamp its source sends as text is read with the zone the text names: an offset after the time,2026-10-15 12:34:56.789+00, as DuckDB writes aTIMESTAMPTZ, orUTCor an offset after a space,2026-10-15 12:34:56.789 UTC, as Trino, Starburst, Presto and Athena write atimestamp with time zone. Text that names no zone is read as UTC. - A date Excel cannot hold becomes a text cell holding its full ISO 8601 text,
never a wrong date. Excel’s dates end on 31 December 9999, and before
1 March 1900 Excel and other spreadsheets, such as LibreOffice and Google Sheets,
read the same stored date as different days. Both the date the CSV file writes
and the time Excel would show decide: 9999-12-31 20:00 UTC is already
1 January 10000 in
Asia/Kolkata, and 1 January 10000 03:00 UTC is text inAmerica/New_Yorktoo, though it is still 31 December 9999 there. The text is the CSV file’s, on the same day, and it names its zone, so that it never reads as the workspace’s time beside the date cells: a timestamp keeps every digit and the zone its source’s text names, written as ISO 8601 writes one,1850-06-15T00:00:00+05:30, orZforUTC. One that names none is written in UTC with aZ,1850-06-15T05:30:00Z. A date, or a midnight in UTC, is the date alone,1850-06-15, whatever the workspace’s timezone. Text its source sent that these rules do not read as a date is kept as it came instead, as in CSV (see the next point). - A year after 9999 or before year 0 is written as its full ISO 8601 text in
both files:
+010000-01-01T12:34:56.789Z, or+010000-01-01at midnight. Like any text that starts with=,+,-or@, it carries a leading apostrophe so that a spreadsheet does not read it as a formula. A source that sends such a year as text in another form keeps that text as it came in both files, a text cell in Excel: DuckDB writes 1 January 10000 as10000-01-01 00:00:00, and 15 March 45 BC as0045-03-15 (BC). - A column formatted as a Date in a paginated table or document shows the date
alone, whatever its year, in PDF, HTML, Word and PowerPoint and on the display
sheet of a document’s Excel file. It is written in the workspace’s date format
and zone:
0050-06-15or+010000-01-01on the default settings. Text its source sent that starts with a date written year first, as ISO 8601 writes one, and that these rules do not read as a date, such as DuckDB’s0045-03-15 (BC)or a timestamp whose zone is a region, is shown as it came, whatever the date settings. - A hierarchy matrix writes its date values, such as the latest order time,
by the same rules, and so does a
KPI tile bound to a metric. A matrix’s date and
timestamp group members, the keys of its typed paths, are written as text in
both files: as their full ISO 8601 text,
2026-10-15T12:34:56.789Z, or as the text their source sent. - An
ARRAY,MAPorSTRUCTvalue, such as a PostgreSQL array, a JSON column or a DatabricksSTRUCT, is written as its JSON text in both files:["2026-10-15T12:34:56.789Z",null]. A timestamp inside it is ISO 8601 in UTC, to the millisecond, whatever the workspace’s timezone, and aBIGINTkeeps every digit. PDF, HTML, Word and PowerPoint, and the display sheet of a document’s Excel file, show such a value as the dashboard’s table does. AnARRAYreads as its items separated by commas, each timestamp as2026-10-15T12:34:56.789Zand a NULL item as nothing (2026-10-15T12:34:56.789Z,for that timestamp and a NULL). AMAP, aSTRUCTor a JSON object reads[object Object]there, as on the dashboard, so its value is only in the CSV file and in the Excel file outside a document’s display sheet.
An Excel cell holds at most 32,767 characters. A value whose text is longer
refuses the whole Excel file, with a message that names its column, and no cell
is cut: An Excel cell exceeds 32,767 characters (column notes). Such a text can
be the JSON text of a large ARRAY, MAP or STRUCT value, a group’s heading
in a paginated table or document, which holds the group’s value, or a category
in a document’s chart. A document’s message ends
Use Word, HTML or PDF for this document. CSV keeps such a value whole.
A date a file cannot hold as a date is never refused, rounded or cut: it is written as its full text, as an Excel number longer than 15 significant digits is. That is true of every value its source’s driver reads as a date. These values are not read as dates yet, so both files hold what the dashboard shows for them:
- PostgreSQL: a
timestamportimestamptzafter 13 September 275760, which no date here can hold, arrives empty, like a NULL, and asnullinside an array. Databricks refuses such aTIMESTAMPinstead (see the table below). - MySQL and MariaDB: a
DATETIMEorTIMESTAMPwith a zero month or day, such as0000-00-00 00:00:00, arrives empty too. ADATEwith a zero month or day, a day its month does not have, or a year before 100 arrives as another date:2024-02-00as2024-01-31,2024-02-30as2024-03-01,0050-06-15as1950-06-15. So does aDATETIMEwith a day its month does not have or a year before 100.
Cast such a column to text in the query or the model, as col::text in
PostgreSQL or CAST(col AS CHAR) in MySQL, to export its source’s own text.
A timestamp whose text names its zone by a region, such as Trino’s
2026-10-15 08:34:56.789 America/New_York, is not read as a date either: Excel
holds its text, as CSV does. A region’s offset comes from a time-zone database,
and the source’s and DataSquares’ can disagree on it, so the text is kept rather
than risk a wrong time. Convert such a column to UTC in the query, as
col AT TIME ZONE 'UTC' in Trino, Starburst, Presto or Athena, for a date cell.
Background report exports
Section titled “Background report exports”When enabled, open Export… (in Share’s arrow) and then Background exports… in the paginated builder. Save edits first, choose Export contents and File format, then choose Queue saved report. You can close the dialog and return to Your recent exports later.
| Export contents | Scope |
|---|---|
| Document sections | The pinned saved layout and parameters, using normal source query limits. Failed or capped sections produce Incomplete and no downloadable artifact. |
| Complete table query | Streaming CSV or Excel from the selected saved table query. Includes selected fields and row expressions; omits document groups, totals and repeated-list partitions. |
Complete table query honors saved filters and any authored row limit. It does not mean every row in the database, nor one selected repeated statement. For a multi-section document choose Table section. Supported sources and their requirements are listed in Data consistency and source requirements.
| Source family | Consistency and requirements |
|---|---|
| PostgreSQL, including the supported Neon, Supabase, AlloyDB, Azure PostgreSQL, RDS PostgreSQL, Cloud SQL PostgreSQL and TimescaleDB aliases | Read-only repeatable-read snapshot. |
| MySQL/MariaDB, including Azure MySQL, RDS MySQL and Cloud SQL MySQL aliases | Read-only repeatable-read transaction. Snapshot consistency requires transactional tables such as InnoDB; nontransactional tables may change during a read. |
| SQL Server/Azure SQL | Snapshot transaction. A database owner must already have enabled ALLOW_SNAPSHOT_ISOLATION in every referenced database. The exporter does not change that setting. Expose money and decimal/numeric columns above 15 digits as text in the model to preserve exact values. |
| ClickHouse 22.9 or newer | One read-only streaming query, with its schema and exact decimal/large-integer strings. Consistency follows the table engine and server version; distributed or external tables do not promise a single global snapshot. Source limits fail the job instead of publishing partial results. Older servers are refused before the query runs. |
| DuckDB | One SELECT in an explicit transaction on an exclusively leased connection, read in native chunks. Completion, cancellation and early return roll back the transaction. Remote extensions retain their own source consistency. A DuckDB source opened on a MotherDuck md: DSN is refused; see below. |
| Amazon Redshift | One read-only transaction with a forward-only cursor: a single consistent snapshot under the database’s serializable or snapshot isolation, with exact decimal and 64-bit integer strings. Redshift first builds the whole result on its leader node, within the cluster’s cursor size limit; a larger result fails the job instead of publishing part of it. Live acceptance on a Redshift cluster is pending. |
| Snowflake | One statement, so one consistent read of the data committed when it starts, with exact NUMBER values; external tables keep their own consistency. The statement must finish within the source’s query time limit, which also stops it on Snowflake. Snowflake keeps the whole result and the job downloads it in chunks, within that limit again. Reaching the limit fails the job with a message naming it. A result that does not arrive in full fails the job instead of publishing part of it. Live acceptance on a Snowflake account is pending. |
| BigQuery | One query job, so one consistent read of its tables as they were when it starts, with exact INT64, NUMERIC and BIGNUMERIC values; external tables keep their own consistency. The job must finish within the source’s query time limit, which is also its own timeout on BigQuery. It is billed like any query from the source and is refused when it would bill more than the source’s bytes-billed cap, when one is set. BigQuery keeps the whole result and the job reads it page by page, each page within the time limit. Reaching either limit fails the job with a message naming it. A result that does not arrive in full fails the job instead of publishing part of it. Live acceptance on a BigQuery project is pending. |
| Trino, Starburst and Presto | One query, read page by page as the engine produces it, with exact decimal and 64-bit integer values. Cancelling the job cancels the query. Consistency follows each catalog’s connector: Iceberg and Delta Lake tables are read at one snapshot, while other connectors promise none across the read. The read must finish within the source’s query time limit, and a failed query fails the job instead of publishing part of it. Live acceptance on a Trino, Starburst or Presto cluster is pending. |
| Amazon Athena | One query: Athena stores its complete result in the workgroup’s S3 output location, then the job reads that stored result page by page, with exact decimal and 64-bit integer values. Iceberg tables are read at one snapshot; other tables reflect the S3 objects present while the query scans them. The query must finish within the source’s query time limit. Cancelling the job while the query runs stops it on Athena, which bills by data scanned. Live acceptance on an AWS account is pending. |
| Oracle | One query in a read-only transaction, fetched in batches: Oracle returns every row as of the moment the query started. If the database’s undo can no longer provide that (ORA-01555, snapshot too old), the job fails instead of mixing old and new rows. NUMBER values keep their exact digits. The read must finish within the source’s query time limit. Expose BFILE, object, cursor and interval columns as text in the model; the job refuses them. Live acceptance on an Oracle database is pending. |
| Databricks | One statement. Databricks reads each Delta table under snapshot isolation, at the table’s current version when the statement accesses it, unaffected by writes made while it runs; a statement over several tables reads each at its own version, not all at one moment. Tables in other formats (external Parquet, CSV or JSON files) and federated tables keep their own consistency. A result sent as Arrow, inline or as cloud-storage files, keeps every DECIMAL and BIGINT digit, inside ARRAY, MAP and STRUCT values too. The job refuses what would arrive rounded: ARRAY, MAP and STRUCT columns Databricks sends as JSON text instead of Arrow, and, in a result sent in the column-based form, a BIGINT of 2^53 or more, a DECIMAL above 15 digits and every ARRAY, MAP and STRUCT column; cast them to STRING in the model. In a result sent as Arrow, a TIMESTAMP arrives to the millisecond, cut toward 1970, however far it is from 1970: its microseconds are dropped, and a value before 1970 that has them moves up to the next millisecond (1969-12-31 23:59:59.999999 arrives as 1970-01-01 00:00:00.000, and 9999-12-31 23:59:59.999999 as 9999-12-31 23:59:59.999). One more than 100,000,000 days from 1970 fails the job. Cast the column to STRING in the model to keep every digit. Databricks may send a result larger than 1 MB as files in cloud storage of up to 20 MB each; the job then downloads up to ten files ahead of the rows it has read, so besides the file it is reading it can hold about 200 MB of the result at a time. The statement and the reading of its result must finish within the source’s query time limit: reaching it fails the job with a message naming it, and reaching it or cancelling the job cancels the statement on the warehouse while it still runs and closes it there either way. A failed read, or one that arrives short of the rows the warehouse reported sending, fails the job instead of publishing part of it. Live acceptance on a Databricks workspace is pending. |
| Azure Synapse dedicated SQL pools | One SELECT under read committed snapshot isolation, which reads the data committed when the statement starts. A database owner must already have turned on the database’s READ_COMMITTED_SNAPSHOT option (ALTER DATABASE … SET READ_COMMITTED_SNAPSHOT ON, run while connected to master; it closes the database’s open connections). The exporter does not change that setting: without it a dedicated SQL pool reads uncommitted data, so the job is refused before any row. Serverless SQL pools are refused too, because their transactions cover only metadata, not the files they read. External tables keep their storage’s consistency. Expose money and decimal/numeric columns above 15 digits as text in the model to preserve exact values. The read must finish within the source’s query time limit; reaching it, or cancelling the job, cancels the statement. Live acceptance on a Synapse workspace is pending. |
| Uploaded files and app sources: CSV, Excel, Parquet, JSON and SQLite uploads, Google Sheets, REST API and MongoDB | Read-only repeatable-read snapshot of the copy staged at the last upload, replace or refresh, not the live file, sheet or app. A replace or refresh of the same source waits while an export reads that copy; a long read can make it fail and need a retry. |
| DataSquares Warehouse datasets | One read-only streaming query under the workspace’s own Warehouse credential, with exact decimal and large-integer strings. It reads the data present when it starts, so a dataset refresh during the export does not mix old and new rows. The read must finish within the Warehouse query time limit (5 minutes on DataSquares Cloud), and it counts toward the workspace’s Warehouse query hours. Source limits fail the job instead of publishing partial results. |
Other connectors use bounded Document sections exports. Protocol compatibility alone does not add support: other MySQL-wire products and other PostgreSQL-wire engines are not included by implication. Two engines that speak a supported family’s protocol have no complete exports, for these reasons:
- Fabric Warehouse runs every transaction under snapshot isolation, which would give one consistent read, and DataSquares signs in to it with Microsoft Entra ID (its connector is in Preview), but no complete read of a Fabric warehouse has been reviewed and run on a live one yet. A complete export from it is refused before DataSquares connects; Document sections exports from it run.
- MotherDuck’s documentation does not say what one query
in a transaction reads when MotherDuck runs it partly in the local engine and partly
in its cloud (dual execution), and its read-scaling replicas are eventually
consistent. A MotherDuck source, or a DuckDB source opened on an
md:DSN, is refused when the export is queued, before DataSquares connects to MotherDuck; Document sections exports from it still run.
Source-family support is separate from acceptance of a particular managed instance; confirm its requirements in your environment.
Complete query jobs are limited to 1,000,000 rows and 512 MB. Exceeding a limit fails the job; filter or partition the dataset and queue again. Streaming uses bounded batches from one source query (the Databricks row above says how far its reads run ahead of them). The job reads the whole result first and then writes the CSV or Excel file, so the source is released as soon as its rows are read and a source’s query time limit applies to reading the rows, not to building the file. A failed or cancelled job does not publish a partial artifact.
Each job pins the saved definition and parameters at queue time. Data is captured when processing starts; retries capture fresh data. Files are private to the requesting user and expire 24 hours after queuing. The queue shows state, processed rows, bytes, attempt, revision, expiry, export notes and a file checksum. Use Cancel export for queued/running jobs and Remove file for an available artifact. A running cancellation can first show Cancellation requested.
Downloads recheck current report, source and membership permissions. Revoked access can make an earlier successful file unavailable. Expired, revoked, failed, cancelled and incomplete jobs cannot be treated as successful downloads. If Background exports… is absent, the workspace/API capability is not enabled; the ordinary saved download remains a separate path.
Hierarchy matrix exports
Section titled “Hierarchy matrix exports”Dashboard hierarchy matrices have a dedicated data export scope. Dashboard/card CSV and server-rendered block-report CSV, Excel, PDF, HTML and PowerPoint can capture the complete bounded hierarchy, including detail, subtotal and grand-total records. The record kind and typed group paths distinguish those rows. Do not sum them together. Aggregates such as averages, distinct counts and ratios are recalculated at each grain rather than added from child cells.
This scope supports four row levels, four column levels, 20 measures, at most 25 queries, 500 value columns and 250,000 aggregate/displayed values. Browser expansion state, card Top N and card sort do not restrict it. Source caps, changed access, duplicate cells and detected group-domain changes refuse the export. The queries are independent, not a shared transaction; values may change during the recorded capture interval.
- CSV retains raw captured values and a scope note.
- PDF/HTML/PowerPoint retain supported per-measure formats, conditional styles, icons, safe links and data bars. Wide tables continue across pages or slides.
- Excel retains typed values and native numeric data bars, with a companion display sheet for formatted labels, supported links and trend images. Precision-sensitive text cells do not receive numeric bars.
- Data-bar scales cover all captured levels, including totals, with zero included. This can differ from the browser’s currently loaded branches.
- Sparklines use the deepest leaf column groups in deterministic export order; column subtotals are not trend points. Missing or unsafe numeric values leave gaps. Row/shared scales and visible descriptions disclose the domain and gaps. This categorical order is not a guarantee of chronological order. Office trends are captured images, not editable native sparkline objects.
Dashboard image-based PNG/PDF/PowerPoint downloads capture the visible scroll window and current expansion. They do not imply a full hierarchy data capture. Read the export’s scope notice, especially in clients using an older fallback. Window traversal and aggregate-group-domain filtering remain outside the complete hierarchy export; model date buckets as explicit fields where required.
Walkthrough: schedule a report and export it
Section titled “Walkthrough: schedule a report and export it”Open the report and choose Schedule. Set how often it goes out (daily, weekly or monthly), the time, the time zone and the file format (PDF, Excel, PowerPoint or CSV).
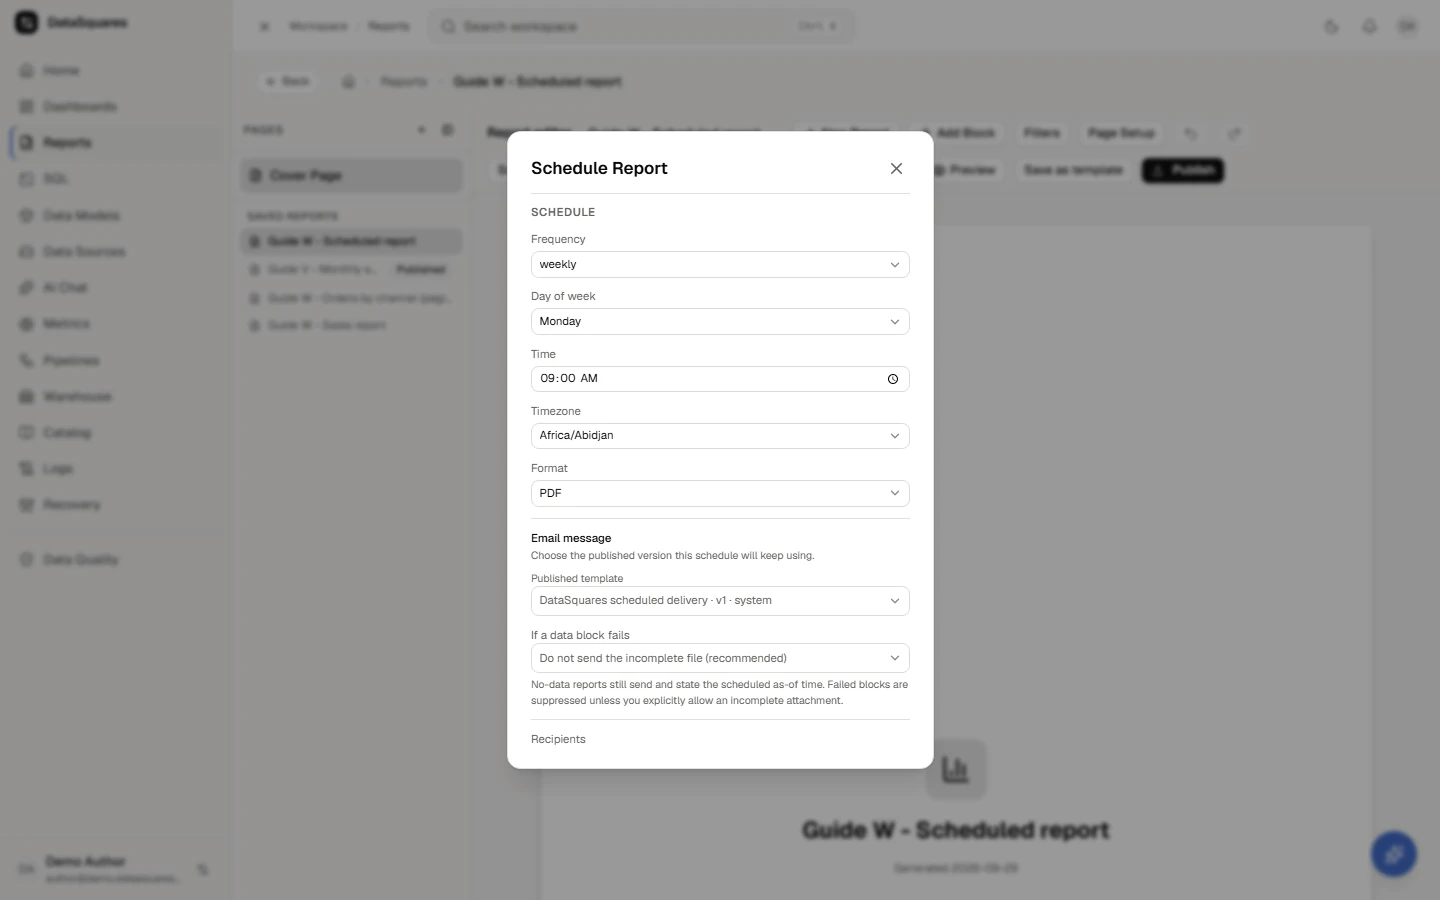
Add each recipient with Add Recipient. The email message can use the system template or a version you publish, and a setting decides what happens if a block of the report fails to render.
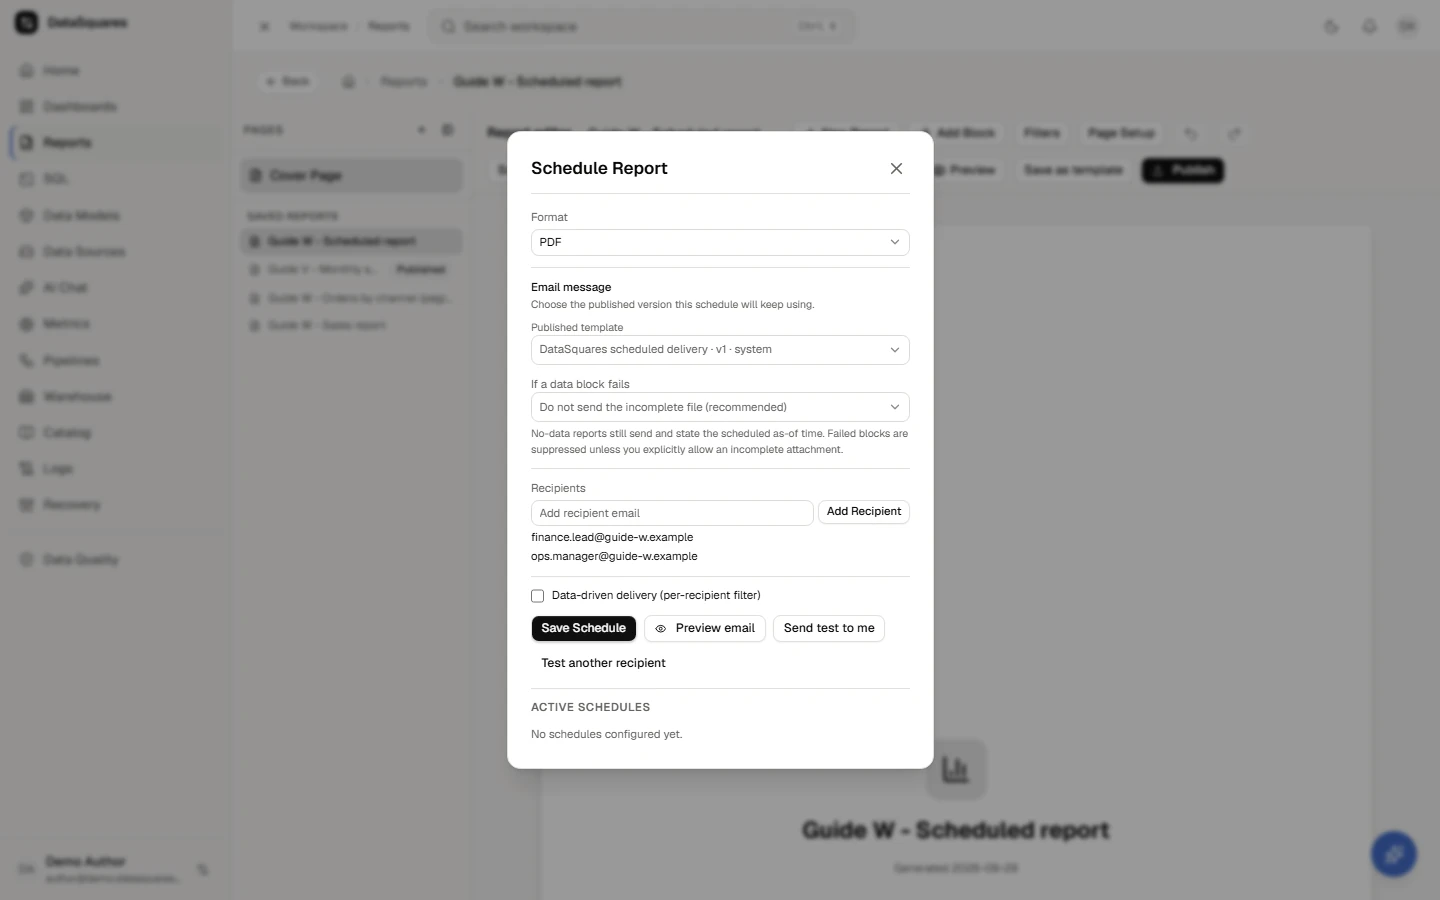
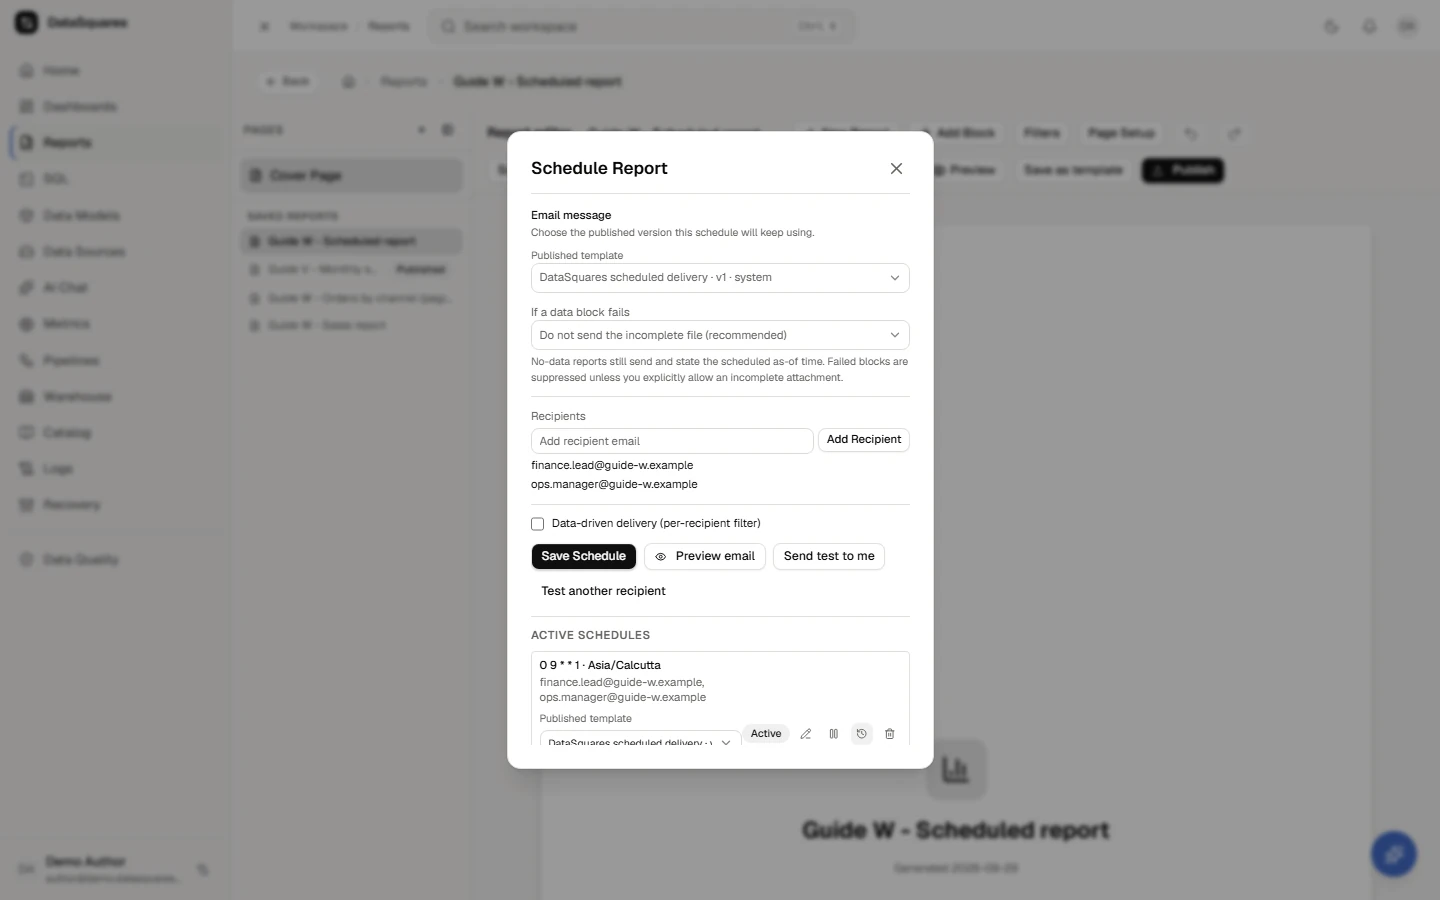
Choose Save Schedule. DataSquares emails the report to the recipients on that cadence. The saved schedule is listed below the form, with its delivery history (each send and whether it succeeded) and a button to delete it.
Export downloads the report right away, without waiting for a schedule: choose PDF, Excel, PowerPoint, CSV or HTML.
HTML export
Section titled “HTML export”The standard block-report HTML file is self-contained: charts are embedded as inline SVG, images as data URIs, styles inline. It renders correctly with the network unplugged, and — because it makes no outbound request — opening it cannot leak the reader’s IP address merely by loading external report assets. Clicking an authored link still navigates to its destination. Review the exported data before sharing a file outside your organization; the recipient is not subject to live application access checks.
A KPI block is a headline value, as in the PDF; a KPI the AI assistant built shows its latest whole period, with the period and its change under it.
For ordinary standard-report table blocks, tables cap at 1,000 rows, with a notice in the file when the data was longer; and author-written text blocks are sanitized on the way out, since the exported file opens in someone else’s browser with none of the product’s protections around it. Paginated documents and hierarchy matrix exports have the separate scopes and limits described above.
Metric tiles in exports
Section titled “Metric tiles in exports”KPI tiles bound to a governed metric render in every format, labelled with the metric’s own name. A tile prints the metric’s number as its card shows it: its latest whole period in the workspace’s time zone, with that period in a Period column beside it (October 2026; in a file the year is always named), or all of its data, All data, for a metric without a time dimension. The page’s filters, and the ones the file was made with, narrow it when their field is on the metric’s data model, as they narrow the card; the rest are named in a Note column beside it (Not filtered by Channel). A metric on a saved query is narrowed by none of them. The metric is evaluated through the governed evaluator, so model-layer row-level security still applies to the exported value — an export cannot become a way around it.
The value is written as a table cell of the same type is. A date or time value,
such as the latest order time, follows
the rules for dates and times: text in CSV,
a date cell in Excel. In PDF, HTML and PowerPoint it is shown in the workspace’s
Date format and Default timezone (Settings), or, on
the default settings, in UTC to the millisecond: 2026-10-15 12:34:56.789. A
KPI tile bound to a model shows its date value the same way. In Excel, a number
its source sends as text, such as a PostgreSQL numeric, is a number cell, and
stays text when it has more than 15 significant digits.
Who can export
Section titled “Who can export”Anyone who can open a dashboard or report can export it, the built-in Viewer role included. An export carries the same row-level security and masking as the screen, so it never shows more than the reader could already see. Embeds can turn export off on their own. See Users & roles.