Connect Data
Refreshing data & schemas
Two different actions on a data source card serve distinct purposes:
| Action | What it does | For |
|---|---|---|
| Refresh | Re-pulls and updates the data rows themselves | Staged pull sources: REST API, the app connectors (Preview), Google Sheets, MongoDB and Apache Iceberg |
| Sync | Re-discovers the schema (tables, columns, and data types) | Direct-query databases, warehouses, and staging |
Test, sync and replace from the card
Section titled “Test, sync and replace from the card”Every source card has Test and Sync. The others depend on the source:
| Action | On |
|---|---|
| Refresh (with its schedule, such as Refresh · daily) | REST API, app connector, Google Sheets, MongoDB and Apache Iceberg sources |
| Replace file | CSV, Excel, SQLite, Parquet and JSON uploads |
| Browse objects | Object stores |
| Import to DataSquares | Every source but a Warehouse dataset, when your company has the Warehouse |
| Open in Warehouse | Warehouse datasets, which are edited and deleted there |
| Edit | Sources you connect with credentials. A staged source (an upload, a REST API or app connector, Google Sheets, MongoDB, Iceberg) has no Edit: replace its file, or use its Refresh dialog (Update credentials for an app connector, Edit mapping for MongoDB, Edit tables for Iceberg) |
| Delete | Every source but a Warehouse dataset (see Deleting a source) |
Edit needs the update permission on data sources, and Delete the delete permission, which the built-in Editor role does not have.
Each source card has its own actions: Test, Sync, Replace file (for file sources) and Edit.
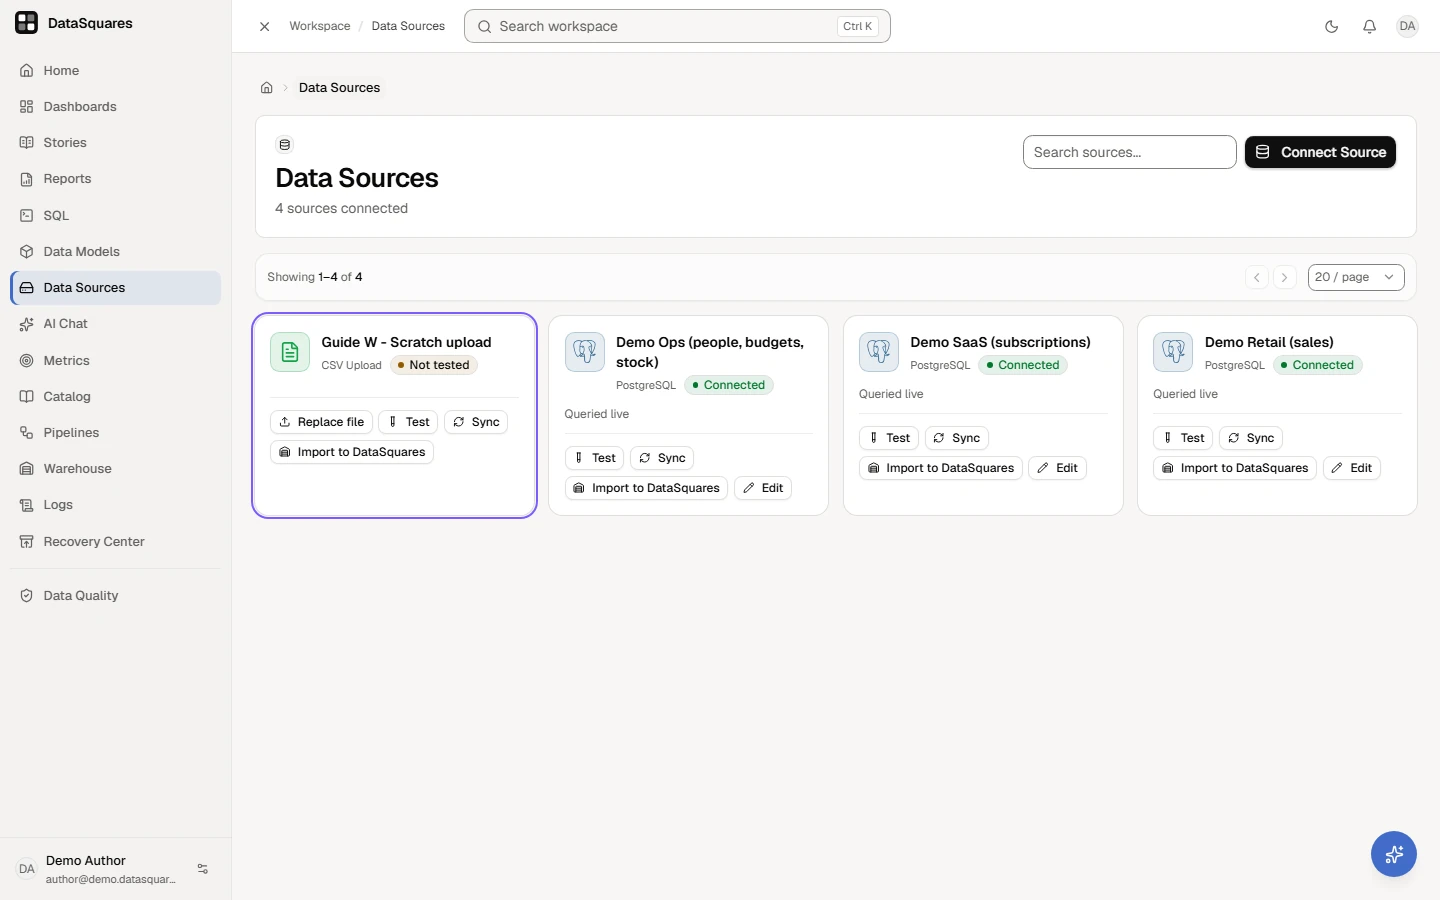
Choose Test. The status on the card shows whether DataSquares can still read the source.
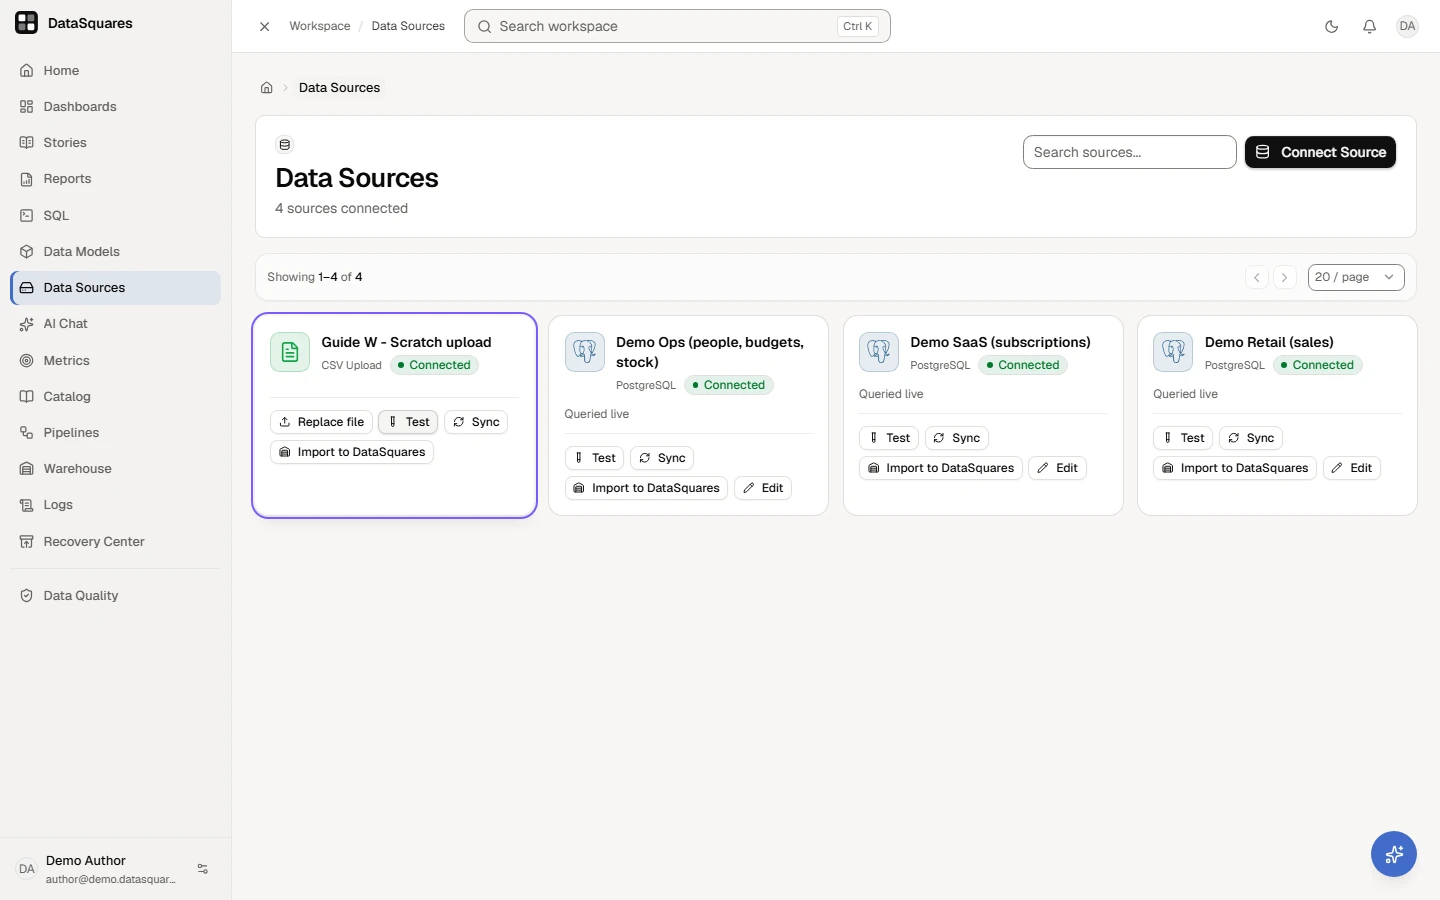
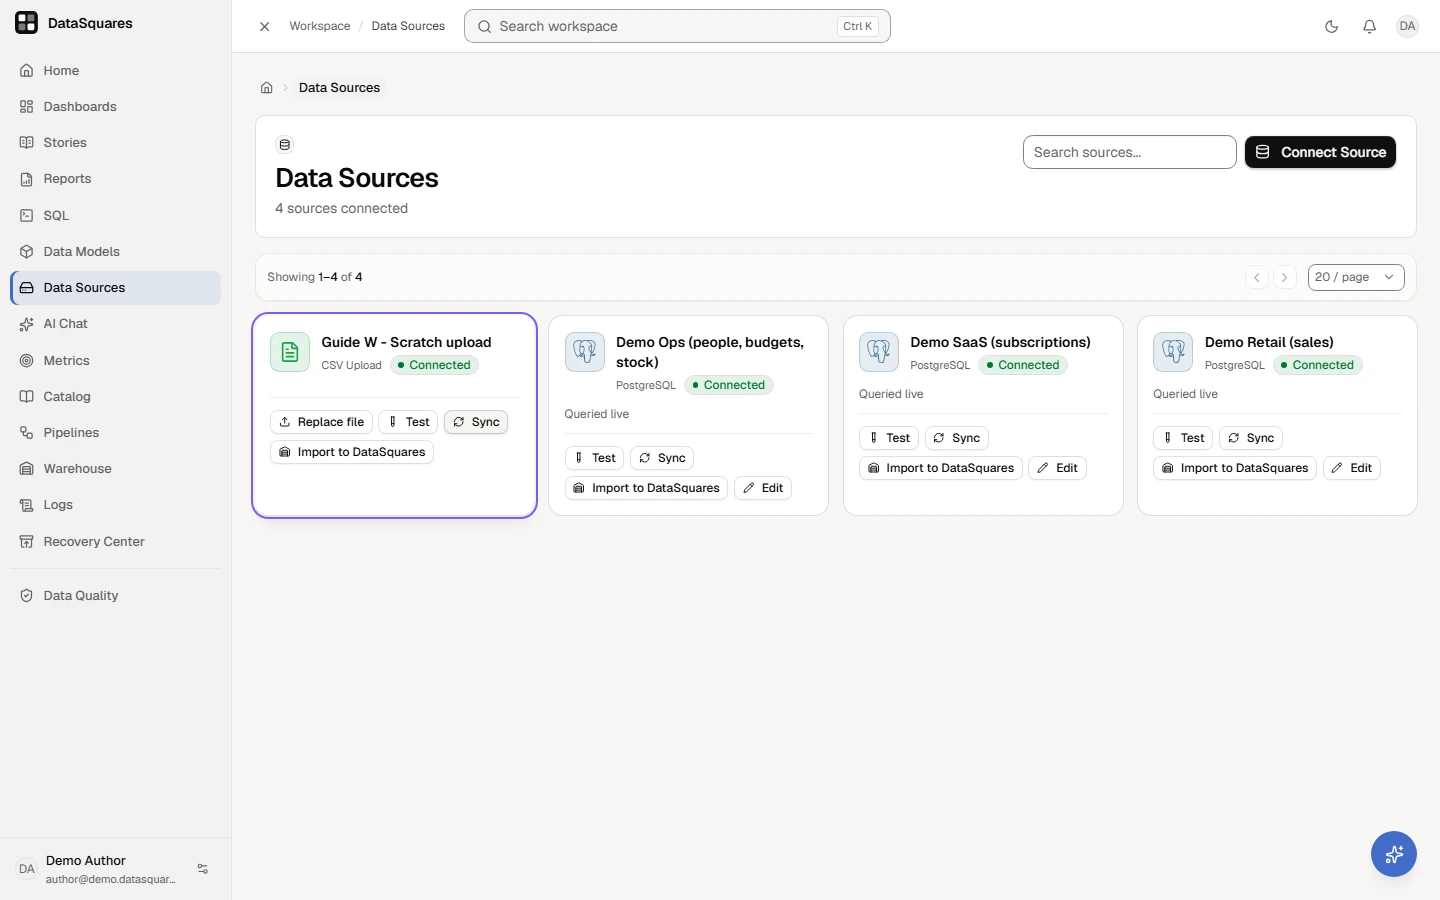
Choose Sync to read the source's tables and columns again after it changed. The button shows Syncing while it runs.
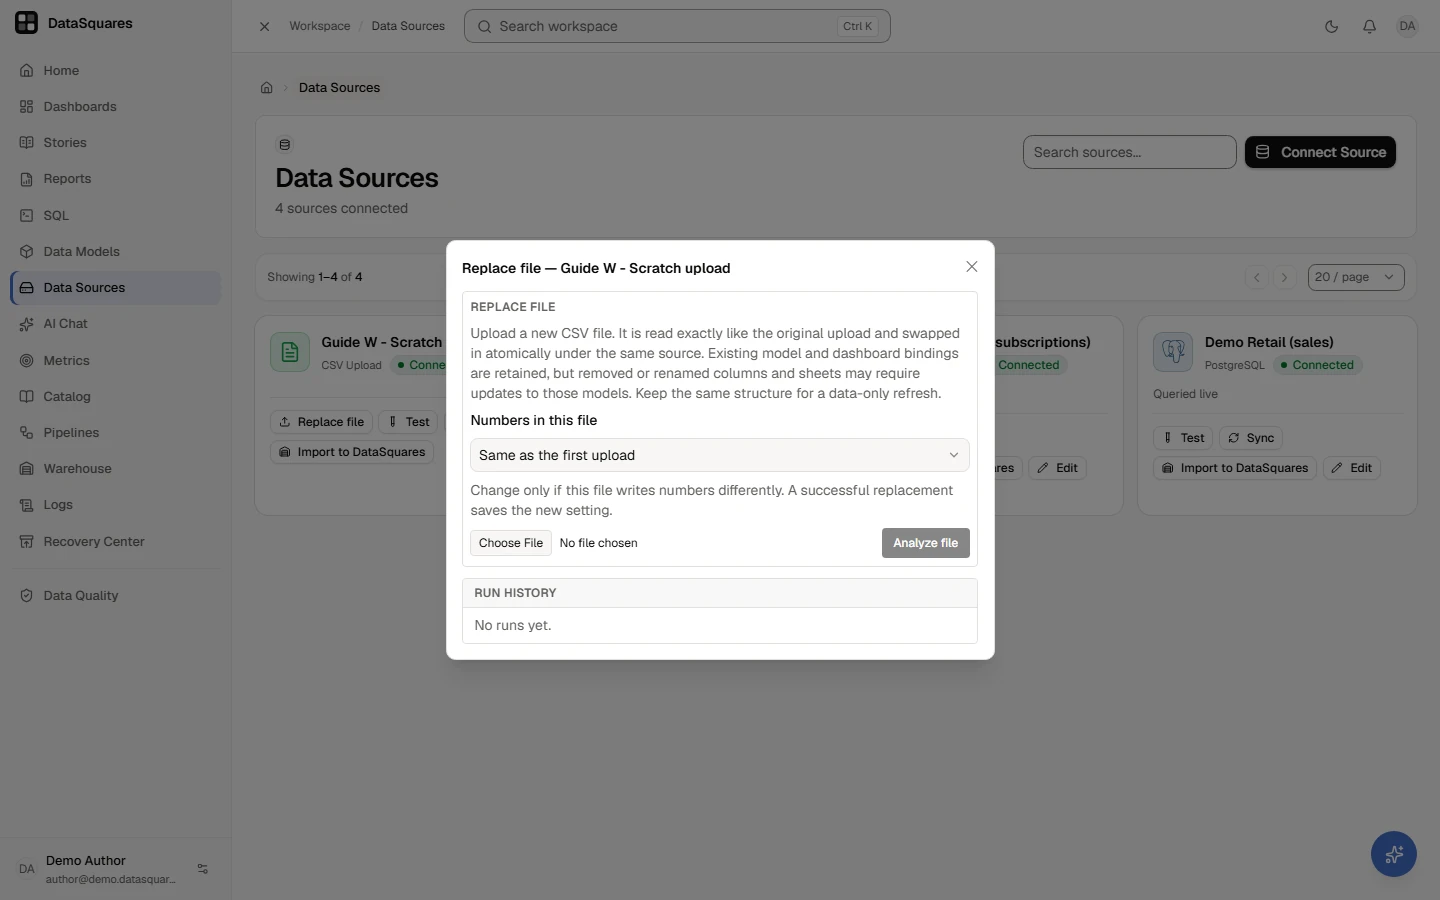
For a file source, Replace file opens the refresh dialog: upload a newer version and the source is updated in place, so models and dashboards built on it keep working.
Refreshing data (API pulls)
Section titled “Refreshing data (API pulls)”For REST API, app connector (Preview), Google Sheets, MongoDB and Apache Iceberg sources, clicking Refresh opens the Refresh dialog:
- Refresh now — Triggers an immediate re-fetch. The UI displays the outcome in real-time (e.g., “Refreshed 3 table(s), 14,250 rows”).
- Atomic transaction swap — Incoming data is staged in temporary tables
alongside existing data. Once validation completes successfully, the tables
are swapped in a single atomic database transaction. Dashboards and reports
never observe half-refreshed states, and removed upstream rows are pruned
cleanly. A MongoDB collection set to read only changes is merged
by
_idinstead: documents deleted in MongoDB stay until you run Full refresh. - Empty-table guard — A refresh that would leave a table empty, or drop it,
where it held rows (a Google Sheets tab cleared, deleted or with its header
row removed) is refused and nothing is replaced. The dialog lists each table
with its previous row count; choose Replace with empty tables to accept
the change, or Keep current data. The refused run is recorded in Run
history with the same counts. API clients send
POST /api/sources/{sourceId}/resyncwith{"allowEmpty": true}; without it the refusal is a409with codeRESYNC_WOULD_EMPTY. - Renamed Google Sheets tabs keep their table — Each tab is tracked by Google’s stable tab id, so renaming a tab refreshes into the same table and the models bound to it keep working. A new tab gets a new table named after it. The success message names renamed tabs.
- Rate limits — When the REST endpoint or Google answers
429or503, the refresh waits for theRetry-Aftertime and tries again, up to three times. If the requested wait is longer than 30 seconds, the refresh stops and the error says when to retry. - Actionable Google errors — A sheet that is not shared with the service account names the email to share it with; a missing spreadsheet, a rejected key and a Google outage each say what to do.
- Apache Iceberg reads only what moved — A refresh first reads each table’s metadata. When every table’s snapshot and schema are the ones last imported, the run is recorded as a success and nothing is read or replaced, so an hourly schedule on a quiet table costs one metadata read. When a snapshot moved, every table of the source is read again and replaced in one swap. See Apache Iceberg.
- File uploads (CSV, Excel, SQLite, Parquet, JSON) are point-in-time snapshots — open the source’s Replace file action and upload the new file; the staged tables are swapped in place under the same source (see CSV upload).
Automated refresh schedules
Section titled “Automated refresh schedules”Inside the Refresh dialog, set the Schedule dropdown to automate ingestion:
- No schedule (manual only)
- Hourly
- Daily
- Weekly
Schedules run as resilient relative intervals evaluated server-side. The scheduler persists across server restarts and multi-instance deployments; a transient network failure will report an error in history but will not disable the recurring schedule.
Due sources refresh a few at a time, taking turns across workspaces, so one slow
endpoint does not hold up everyone else’s refresh. Each scheduled refresh has a
deadline (15 minutes by default); a refresh that runs past it is stopped, nothing
is published, and Run history says so. The next scheduled run tries again.
Operators tune both with SOURCE_SYNC_CONCURRENCY and SOURCE_SYNC_DEADLINE_MS.
Run history & auditing
Section titled “Run history & auditing”The dialog’s Run history table maintains an audit log of the last 20 sync executions:
- Status — Success, Running, or Error with an error message.
- Trigger — Identifies whether the run was triggered by manual user action, an automated schedule, or an inbound webhook.
- Metrics — Start time and, for a successful run, the tables and rows ingested; a failed run shows its error.
Failure notifications & webhooks
Section titled “Failure notifications & webhooks”When a refresh fails — manual, scheduled or webhook — DataSquares dispatches a
source.sync_failed event to your configured Webhooks.
You can route this to Slack or alert channels to catch upstream API issues
instantly.
Event-driven refresh (inbound webhook trigger)
Section titled “Event-driven refresh (inbound webhook trigger)”When upstream systems know exactly when new data is ready, you can push updates instead of waiting for the next polling interval:
- Open the source’s Refresh dialog.
- Check the saved Inbound trigger state. If disabled, click Enable and store the newly generated secret in the calling system. The secret is shown once; reopening the dialog shows the enabled state without revealing it.
- Upstream pipelines or cron jobs send an authenticated
POSTrequest to:
POST /api/sources/{sourceId}/sync-triggerContent-Type: application/jsonX-DataSquares-Timestamp: 1724587200000X-DataSquares-Delivery-Id: 550e8400-e29b-41d4-a716-446655440000X-DataSquares-Signature: e3b0c44298fc1c149afbf4c8996fb92427ae41e4649b934ca495991b7852b855The headers above illustrate the format. Use the current Unix time in milliseconds, a fresh delivery ID and a signature calculated with your secret.
Enable, disable and rotate
Section titled “Enable, disable and rotate”Enabling an already enabled trigger preserves its secret, including concurrent enable requests. To replace a lost or compromised secret, click Rotate secret, review the warning and confirm Rotate secret now. The old secret stops working immediately; copy the new secret into the calling system before sending another trigger. Disable removes the secret; enabling again creates a new one.
For API clients, PUT /api/sources/{sourceId}/sync-trigger requires source-write
scope and permission to update data sources in the current workspace:
| Body | Outcome |
|---|---|
{"enabled":true} |
Enables if needed; preserves an existing secret. |
{"enabled":false} |
Disables the trigger; repeating this is safe. |
{"enabled":true,"rotate":true} |
Rotates an enabled trigger; a disabled trigger returns 409. |
The response contains enabled, secret and url. secret is non-null only
when a new secret was created by that request. Source list and detail responses
expose only sync_trigger_enabled, never the signing secret. Rotation with
enabled:false is rejected with 400. A rotation is recorded as
source.trigger_rotated; repeated enable/disable requests do not record a state
change when nothing changed.
Signature verification contract
Section titled “Signature verification contract”- HMAC SHA-256 — The signature is calculated as the HMAC-SHA256 hex digest
of
"{timestamp}.{deliveryId}.{sourceId}"using your secret key. - Replay attack protection — Each
X-DataSquares-Delivery-Idis accepted strictly once. - Timestamp window — Use Unix milliseconds. Requests more than 5 minutes ahead of or behind the server clock are rejected.
- The resulting execution appears in Run History tagged with the webhook trigger indicator.
Schema sync (Discovery)
Section titled “Schema sync (Discovery)”Click Sync on a database, warehouse, or staged source card to trigger Schema Discovery:
- Waits for completion — The card shows Syncing… until the server job finishes. Each source has its own progress state, so two discoveries can run independently. Completion reports table and column counts; an empty result asks you to check database access.
- Reports failures — A failed job shows a safe connection-error category. Discovery status and schema-sync history omit raw hostnames, usernames and driver response bodies. If the source changes during discovery, run it again.
- Detects structure changes — Identifies newly created tables, added columns, modified column data types, and dropped columns.
- Preserves semantic metadata — Keeps existing descriptions, tags, and SquareX calculated measures attached to untouched fields.
- No data import — Reads metadata and row-count information without copying source tables into DataSquares.
Leaving the page stops its progress checks; an accepted discovery job continues on the server. If the page cannot confirm an outcome within its polling window, it reports that uncertainty instead of claiming success. Click Sync again to resume checking a job that is still running.
Related
Section titled “Related”- Connection flows explained
- Connector catalog
- Webhooks & outbound events
- Data Pipelines — Multi-step transformation, change data capture (CDC), and reverse ETL.