Connect DataFiles & Apps
CSV Upload
You connect CSV Upload from the DataSquares connection wizard. Upload a .csv file — rows are imported into your workspace.
-
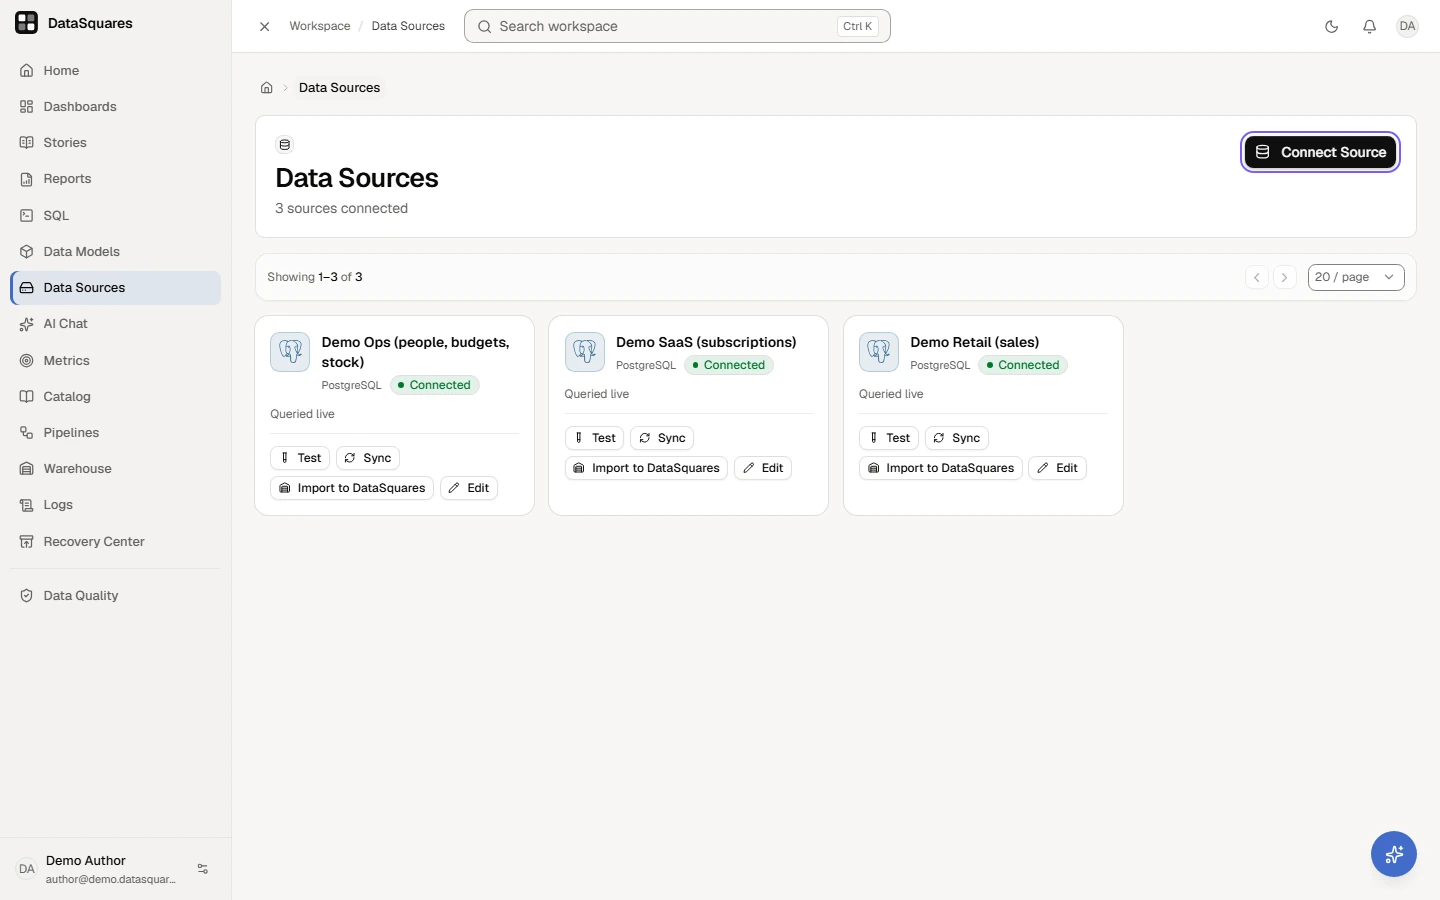
In DataSquares, open Data Sources and choose Connect Source. The Connect a data source page opens.
-
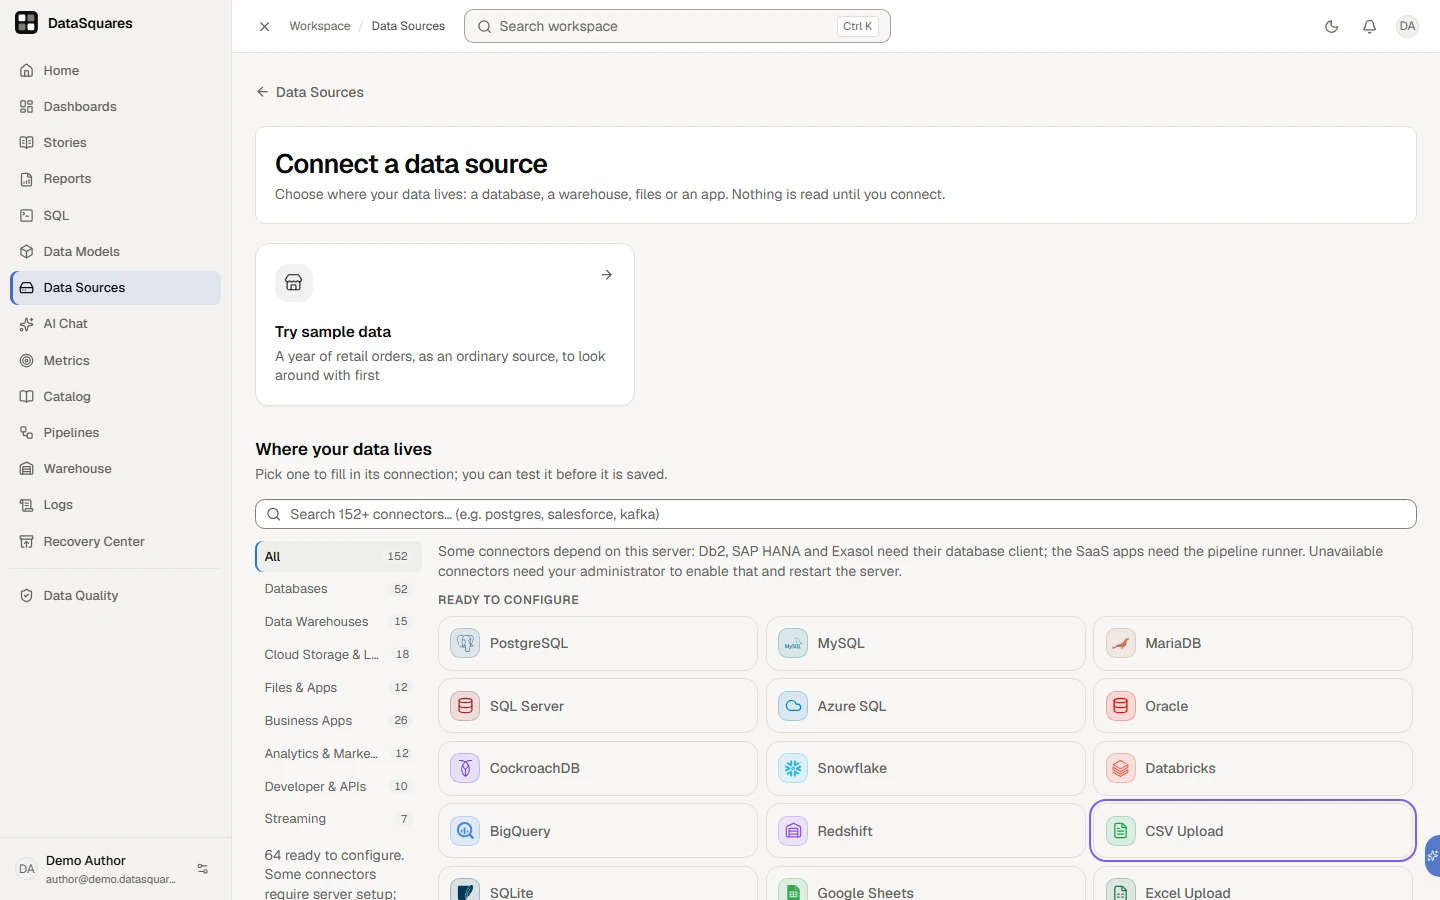
Pick CSV Upload on that page (search or browse by category).
-
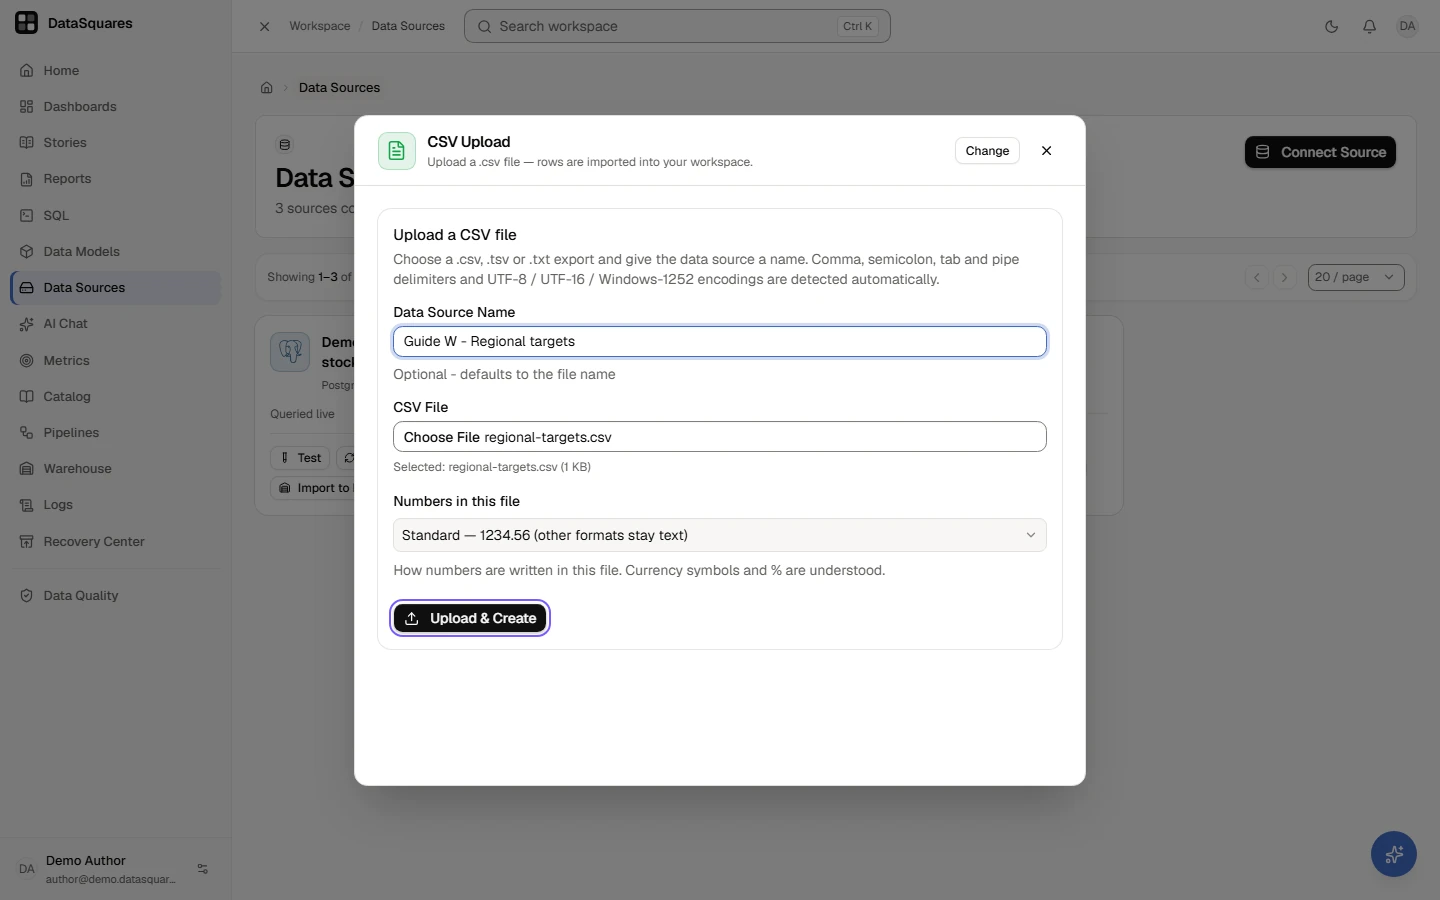
Name the source, choose the file, then choose Upload & Create.
Uploading the file
Section titled “Uploading the file”Pick CSV Upload on the Connect a data source page and upload your file — no credentials needed. The file rows are imported into a staging table in your workspace and become queryable immediately.
File expectations
Section titled “File expectations”- First row = column headers; names are cleaned into valid field names.
- The delimiter is detected from the file — comma, semicolon (European
exports), tab (
.tsv, Excel’s Unicode Text) and pipe all work. - Encoding is detected too: UTF-8 (with or without a byte-order mark), UTF-16 and Windows-1252 exports all keep their accented characters.
- Column types are inferred from the data: integers, decimals, booleans, ISO
dates and date-times, and day-first / month-first calendar dates when the
values make the order unambiguous (
15/01/2024is day-first; a column where every value could be read either way stays text). Scientific notation becomes a floating-point number; values with leading zeros stay text. - Numbers written for a locale (
1,234.50,1.234,50,€12,12%) are never guessed —1,234is a thousand in one locale and a decimal in another. Choose Numbers in this file when you upload: 1,234.56 (decimal point) or 1.234,56 (decimal comma). Thousands separators, a currency symbol before or after the number, a trailing%(12% imports as 0.12, as in Excel) and accounting negatives such as(1,234.50)are then read as numbers. Left on Standard, such columns import as text. A replacement uses the same choice unless you change it. Through the API, sendnumberFormat=dotornumberFormat=commawith the upload. - Date-times keep their meaning: a column whose values carry no UTC offset
(
2026-01-15 09:30) is stored exactly as written, with no time-zone shift for any reader; a column where every value carries one (…Z,…+05:30) is stored as an instant. One offset-less value makes the whole column offset-less. - A file can have at most 1,600 columns.
Replacing the data
Section titled “Replacing the data”An upload is a snapshot. To update it, open the source’s Replace file action and upload the new file — the staged table is swapped in place under the same source, and dashboards built on it pick up the new data. Every replacement is listed in the source’s run history.
The replacement preview checks the same row, column and cell limits as the import. If it refuses a file, split the data or use a pipeline; the existing source remains available. Previewing a file does not change its staged data.
Before you confirm, the preview names what the new file would change: tables and columns added or removed, columns whose type changes, and the models and saved queries (with the dashboards behind them) bound to anything that goes. Approval is tied to the file you analysed — a different file, or a source edited in the meantime, is refused rather than replaced silently.
After the swap, the replacement reports what actually changed. A change that
removes a table or column, or retypes one, is called out as breaking, because
models and saved queries bound to what is gone will fail on their next query.
POST /api/sources/{id}/replace returns that same schemaChange in its
response, so an API caller that skipped the preview still learns what it did.
Importing in the background
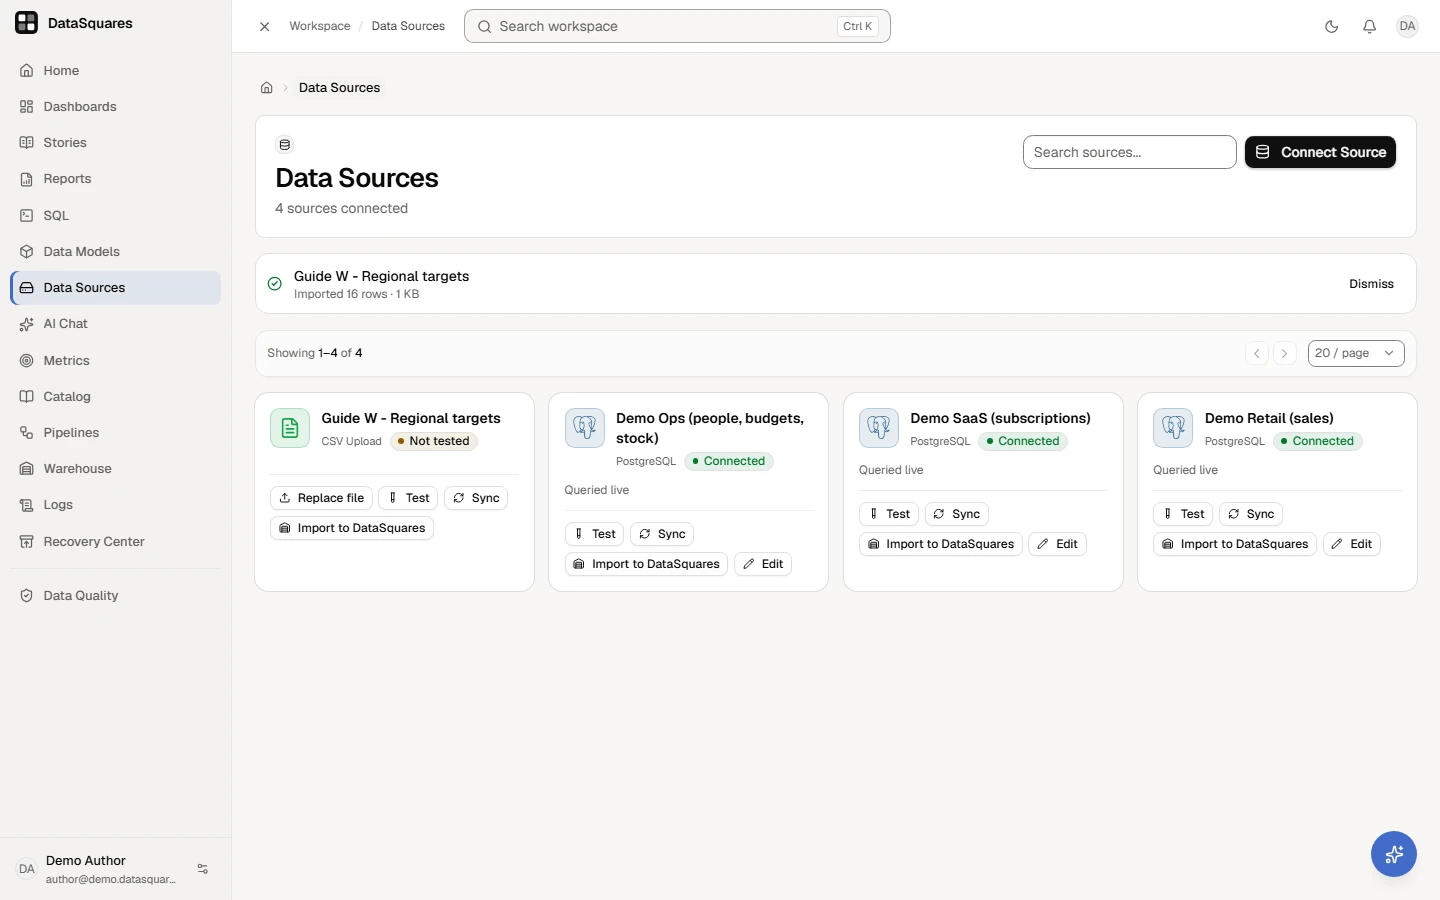
Section titled “Importing in the background”When you upload a file in the app, the upload itself is all you wait for: the file is stored on the server and imported in the background. A panel above your source list shows each import — reading the file, loading rows with a running count, publishing — and a Cancel button. You can keep working, reload the page or close the tab; the import carries on, and the panel picks it up again when you come back. A cancelled import leaves nothing behind. Replace file works the same way, with the progress and Cancel in its dialog; a cancelled replacement leaves the source unchanged.
API callers choose. The upload routes (and POST /api/sources/{id}/replace)
stage the file within the request by default and answer 201. Add
?mode=async to get 202 with an import job instead, then poll
GET /api/sources/ingest-jobs/{jobId} and cancel with
POST /api/sources/ingest-jobs/{jobId}/cancel.
When CSV isn’t the right tool
Section titled “When CSV isn’t the right tool”Multi-sheet workbooks → Excel upload. Very large or repeated extracts → connect the database they come from instead; uploads are best for one-off and occasional data.
Upload a file, step by step
Section titled “Upload a file, step by step”The same steps work for Excel, JSON, Parquet and SQLite files.
Open Data Sources and choose Connect Source.
Pick where the data lives. Choose CSV Upload; Excel, JSON, Parquet and SQLite files work the same way.
Name the source and choose the file. DataSquares detects the delimiter and encoding for you.
The file imports in the background and appears in the list with a status dot. You can keep working while it finishes.
Related
Section titled “Related”- Connector catalog — everything DataSquares connects to.
- Quickstart — from connection to shared dashboard.