Pipelines
Flowlets
A flowlet is a saved chain of transform ops with typed parameter holes — “dedupe by key”, “standardize an address”, “normalize currency”, or “calculate tax” — authored once and instantiated into multiple pipelines with customized arguments.
Manage and build flowlets under Pipelines → Flowlets.
Why use flowlets?
Section titled “Why use flowlets?”Copying transform chains across pipelines causes maintenance drift:
- When business logic changes, copied chains must be found and edited manually in every pipeline.
- A flowlet provides a single centralized definition.
- Every instantiation maintains provenance metadata (“from flowlet Dedupe by key v2”), so a step shows which flowlet and version it came from.
Anatomy of a flowlet
Section titled “Anatomy of a flowlet”A flowlet definition consists of:
- Name & Description — Identifies the reusable module.
- Parameters (up to 24) — Typed inputs with optional default values and descriptions.
- Transform Ops (up to 50) — Standard declarative operations with
${parameterName}placeholders.
{ "name": "Dedupe by key", "description": "Keep the newest row per primary key.", "params": [ { "name": "key_col", "type": "column", "description": "The identity column to deduplicate on" }, { "name": "sort_col", "type": "column", "description": "Timestamp column for ordering" } ], "ops": [ { "op": "rank", "as": "_rn", "partitionBy": ["${key_col}"], "orderBy": [{ "column": "${sort_col}", "direction": "desc" }], "method": "row_number" }, { "op": "filter", "where": { "column": "_rn", "op": "eq", "value": 1 } }, { "op": "select", "drop": ["_rn"] } ]}Parameter types
Section titled “Parameter types”| Type | Input control | Description |
|---|---|---|
column |
Autocomplete input | Bound to incoming pipeline dataset column names with datalist matching |
string |
Text field | Arbitrary string values and literal expressions |
number |
Numeric field | Concrete numbers (rendered as typed numeric values in expressions) |
boolean |
Dropdown | true or false boolean flags |
Substitution is type-aware: when a ${param} placeholder represents the entire
value, it is replaced with the concrete typed value rather than a string literal.
Author a flowlet, step by step
Section titled “Author a flowlet, step by step”An example: a dedupe-by-key flowlet with one parameter.
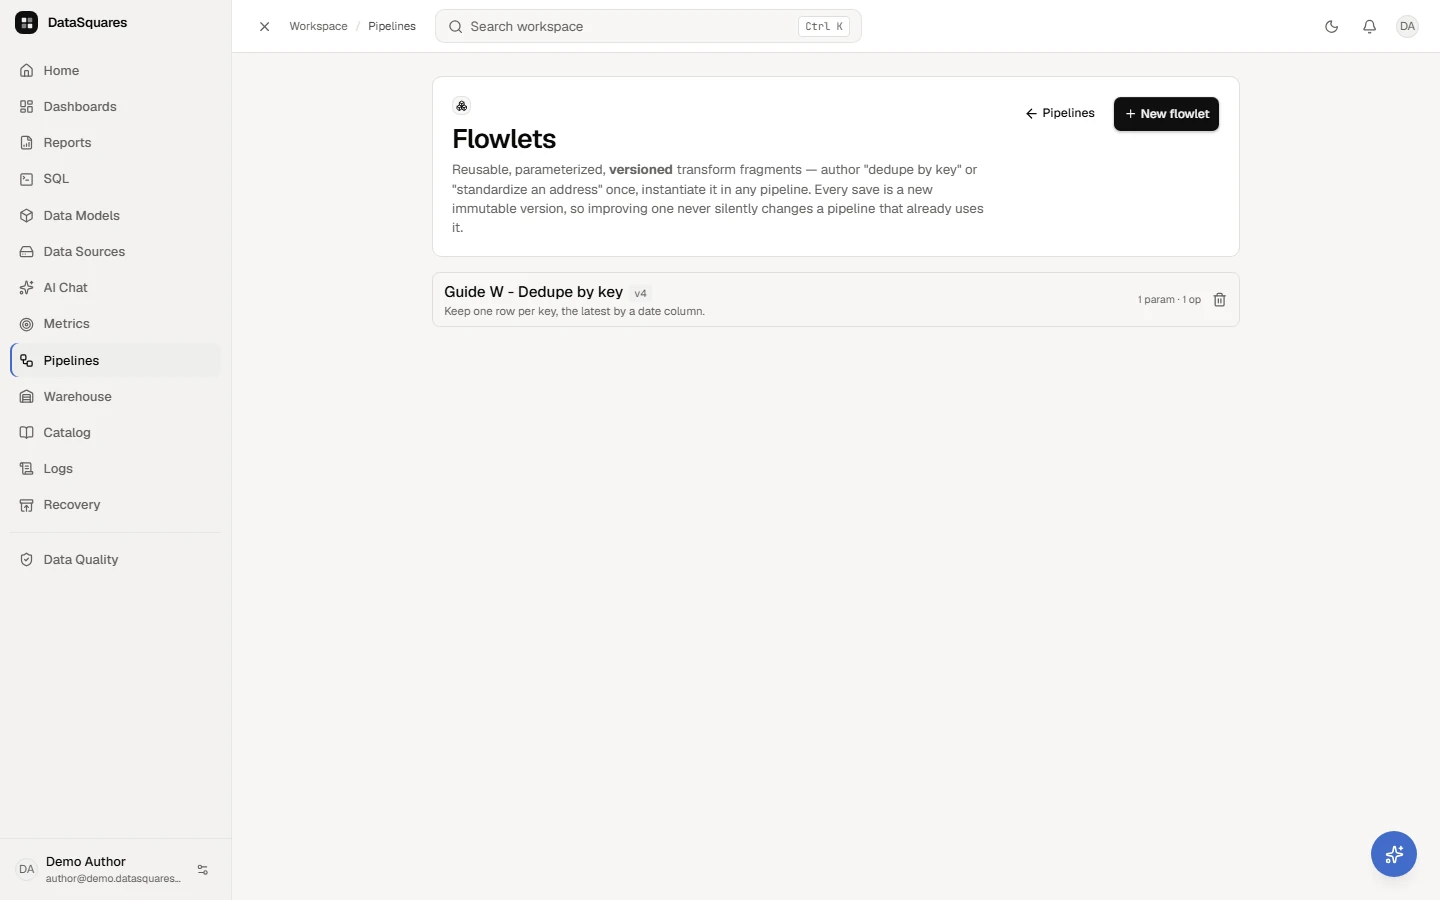
Open Flowlets from Pipelines. A flowlet is a reusable, versioned transform fragment, such as "dedupe by key", that any pipeline can insert.
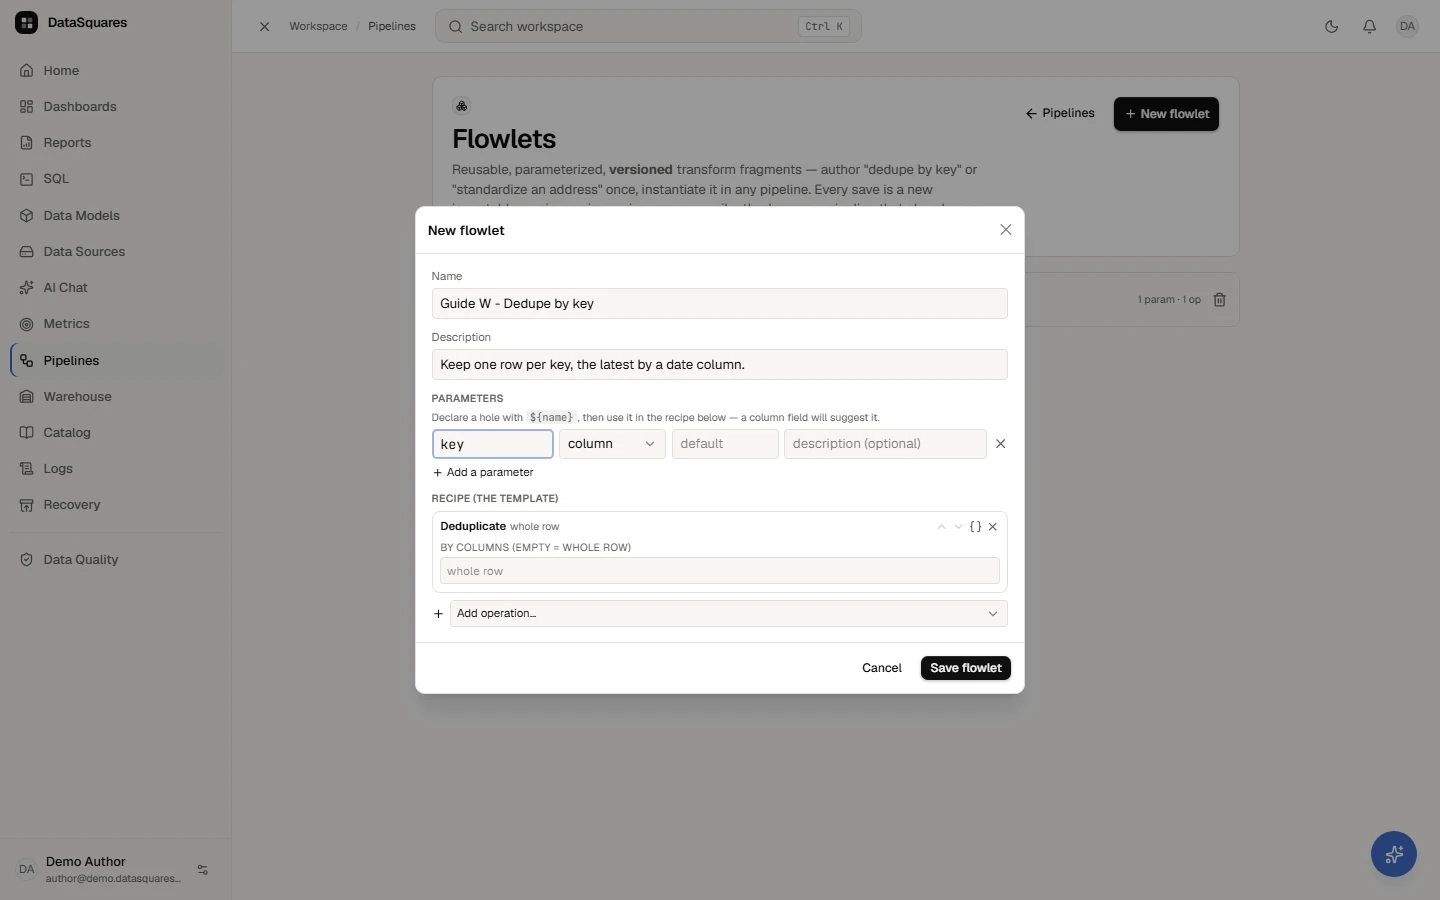
Choose New flowlet. Name it and describe it. Parameters (a key column, a date column) make it reusable, and its steps are the transforms it runs.
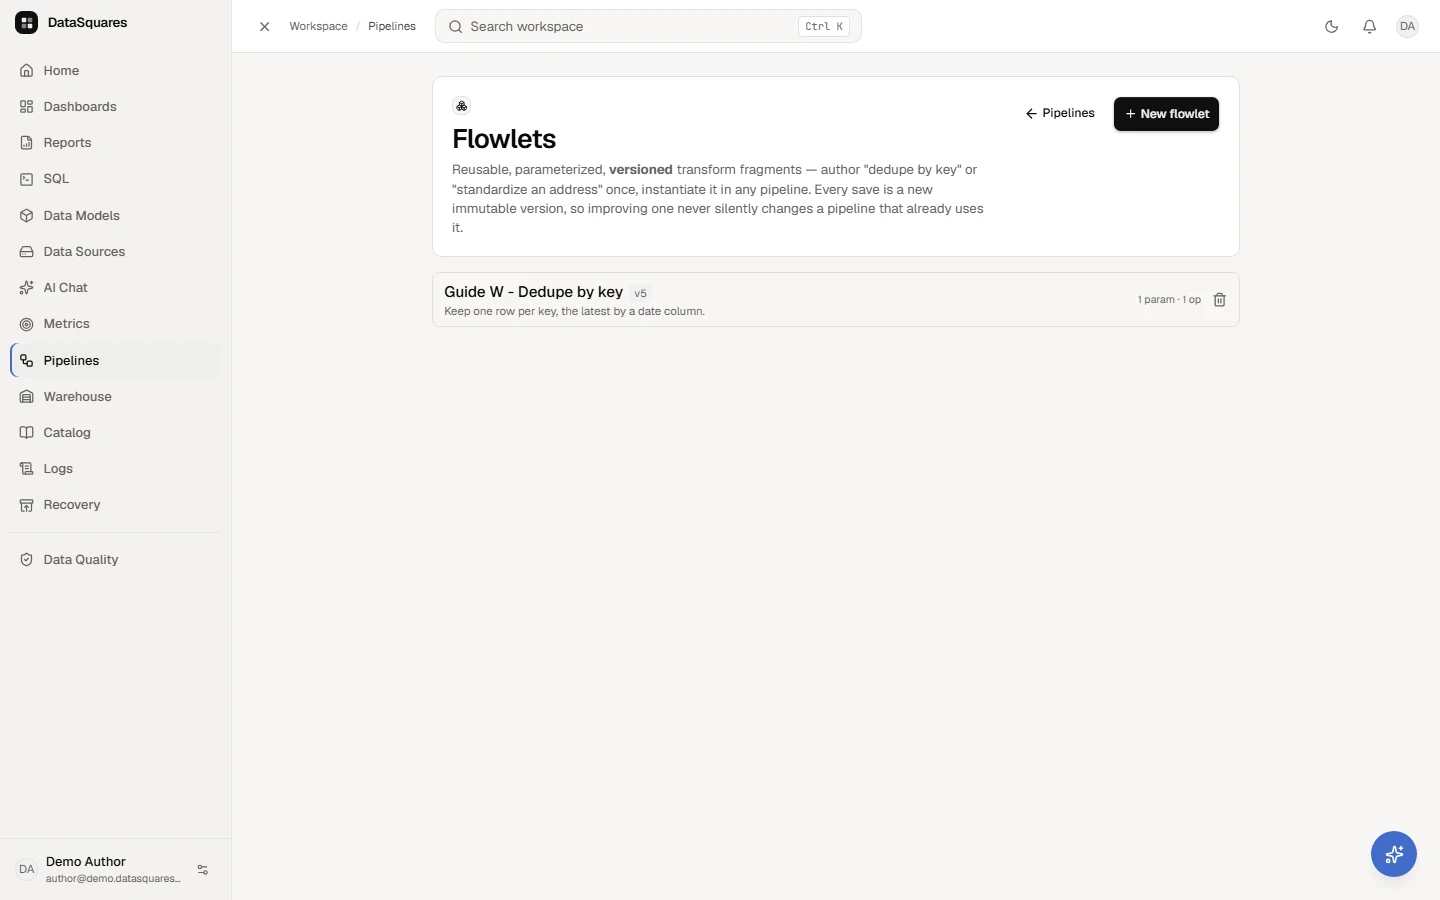
Save flowlet stores version 1. Every later save is a new immutable version, so improving a flowlet never silently changes a pipeline that already uses it. Use Retire to take a flowlet out of the library.
Authoring flowlets
Section titled “Authoring flowlets”- Go to Pipelines → Flowlets and click New flowlet.
- Define your parameters and assign their types and defaults.
- Build the steps under Recipe (the template). Declared parameters are
suggested as
${paramName}in column fields. - Click Save flowlet. The platform validates the template by synthesizing test inputs to ensure all referenced ops and parameters are valid.
Instantiating into a pipeline
Section titled “Instantiating into a pipeline”- In the pipeline editor, select or add a Transform (SQL) step in Visual recipe mode.
- Click Insert from flowlet in the transform toolbar.
- Select the desired flowlet from your library.
- Choose version: The dialog shows the latest version; open history
(
v1,v2, …) to insert an older one. - Provide the concrete column arguments and parameter values.
- Click Insert into step. This replaces the step’s recipe with the
flowlet’s ops and marks the step with a provenance badge
(
from <Name> v<Version>).
Immutable versioning
Section titled “Immutable versioning”Saving a flowlet under a name that already exists makes the next immutable
version (v1 → v2 → v3); there is no edit in place.
- No surprise regressions: Publishing a new flowlet version never modifies existing pipelines. Running pipelines continue using their frozen op snapshots.
- Audit trail: When a new version is published, pipeline authors can choose when to open the flowlet dialog and re-instantiate with the updated logic.
- Retirement safety: Retire removes every version of a flowlet from the library; pipelines that already inserted it keep working.
Security & SQL injection safety
Section titled “Security & SQL injection safety”Parameters cannot smuggle unescaped SQL:
- Parameter values are inserted into strictly typed op schemas.
- The pipeline SQL compiler automatically quotes all identifiers and parameterizes literals before query compilation.
- Broken templates fail validation at authoring time rather than during scheduled execution.
Limits
Section titled “Limits”- Flowlets support declarative ops only (SQL ops builder). Raw SQL queries and Python code steps cannot be packaged as flowlets.
- Maximum of 24 parameters and 50 ops per flowlet definition.
Related
Section titled “Related”- Building a pipeline — Transform step operations and DAG editor.
- Where pipelines can write — Output destinations.
- Pipelines API — Flowlet endpoints.