Pipelines
Building a pipeline
New pipeline opens a page with the ways to start one: Blank pipeline, Import a definition, and the templates (complete flows such as Replicate a table or Join two sources). Blank pipeline asks only for a name (“e.g. Nightly sales sync”) and takes you straight to the editor; a template opens the editor on its flow. As on the list, nothing is offered there until your pipelines have loaded, so a pipeline is never made twice. The pipeline isn’t created until its flow validates, so drafts never clutter the list.
Build a pipeline, step by step
Section titled “Build a pipeline, step by step”An example: replicate the orders table from the demo retail source into a managed dataset.
Start from a template. Replicate a table adds two steps: Extract, which reads a table from a source, and Load, which writes it to a managed dataset.
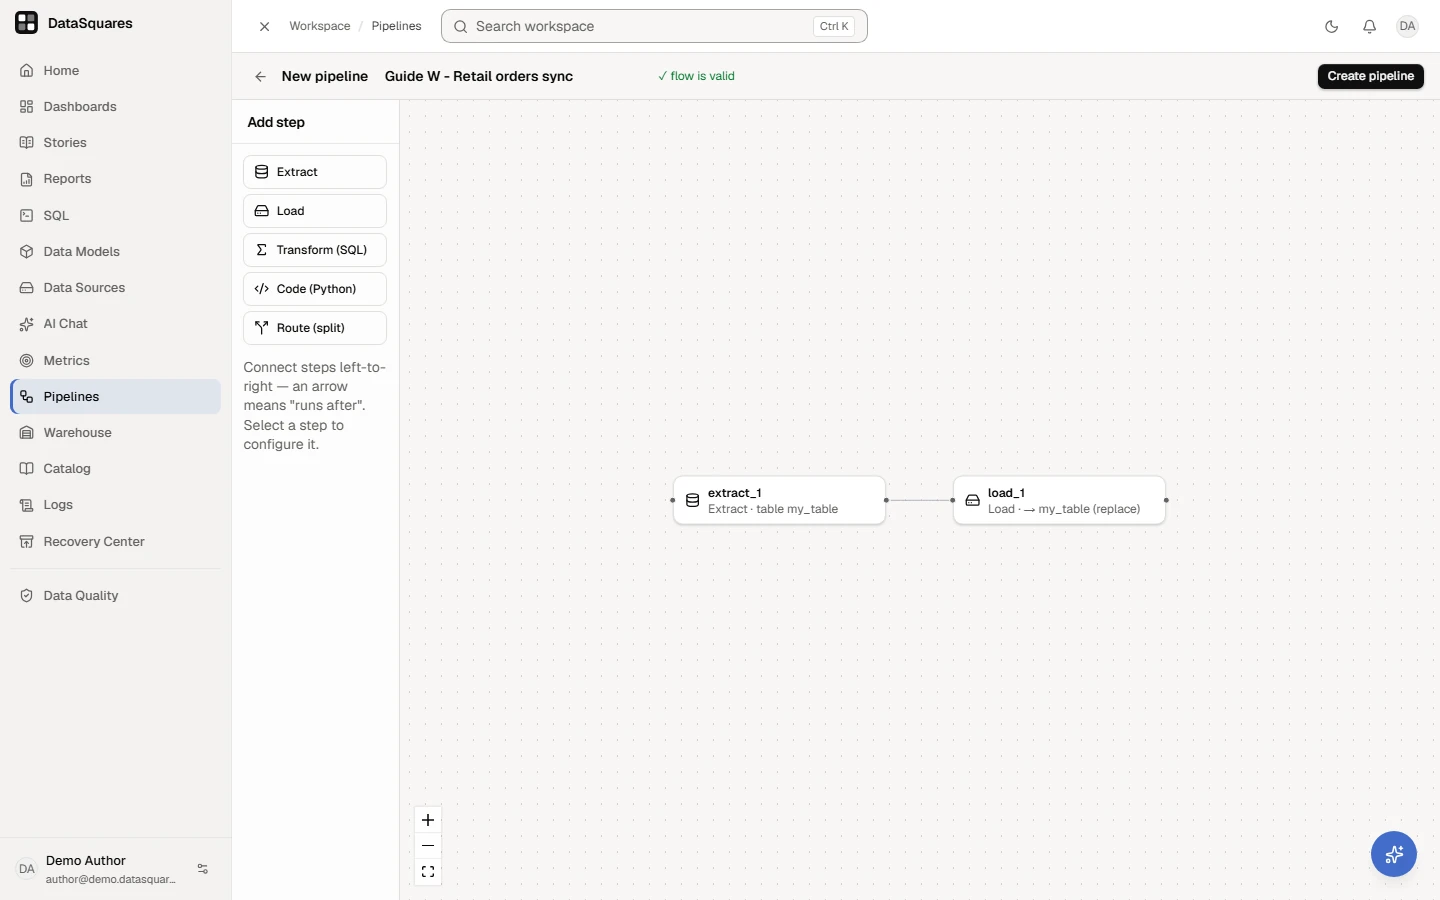
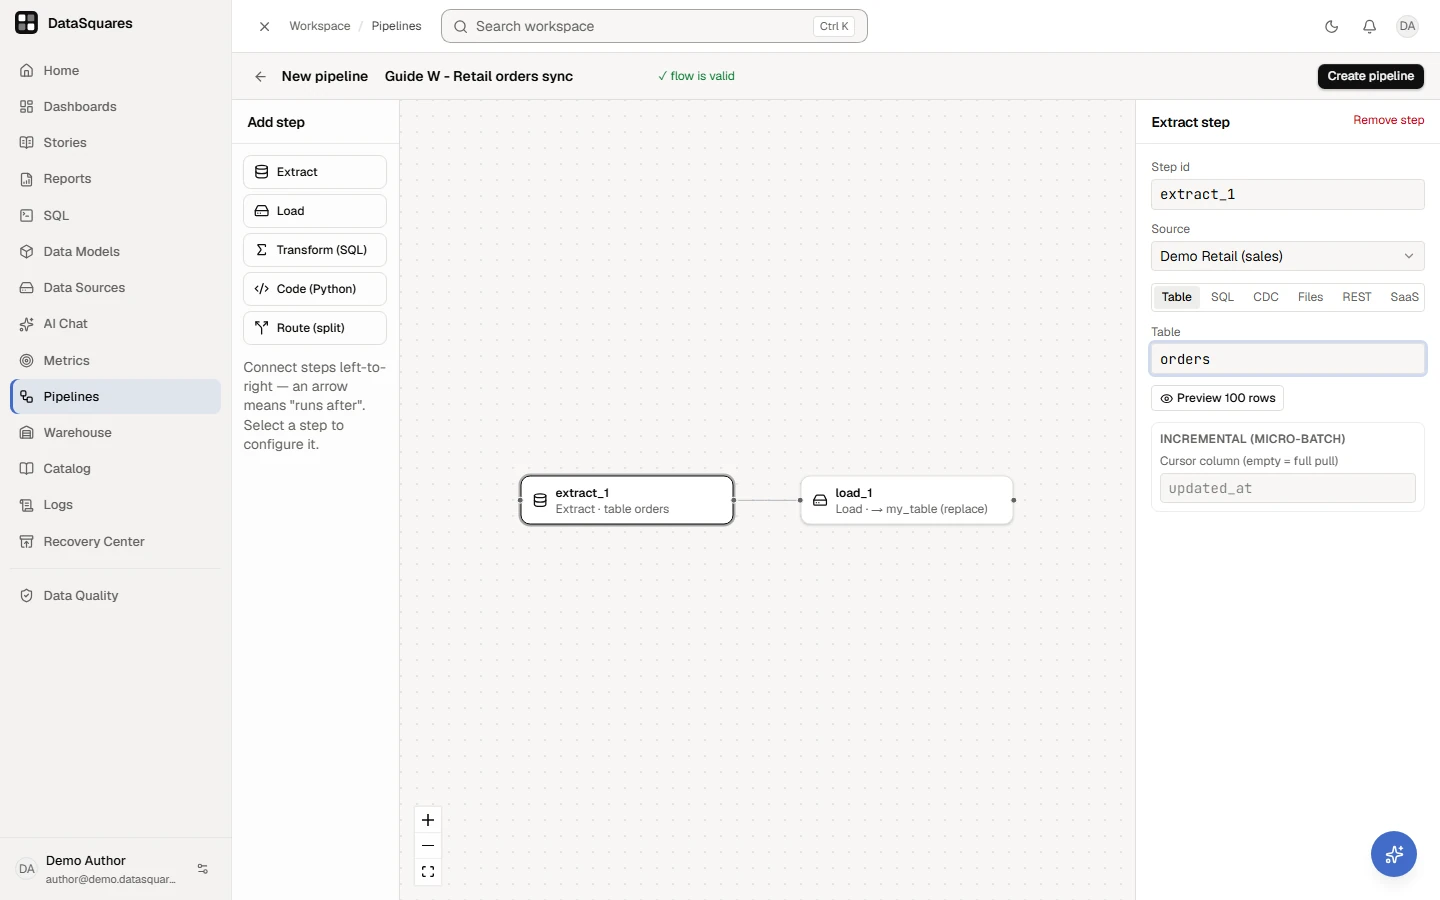
Select the Extract step and choose its source and table. Preview 100 rows reads a sample from the source, and the Incremental option pulls only new rows using a cursor column.
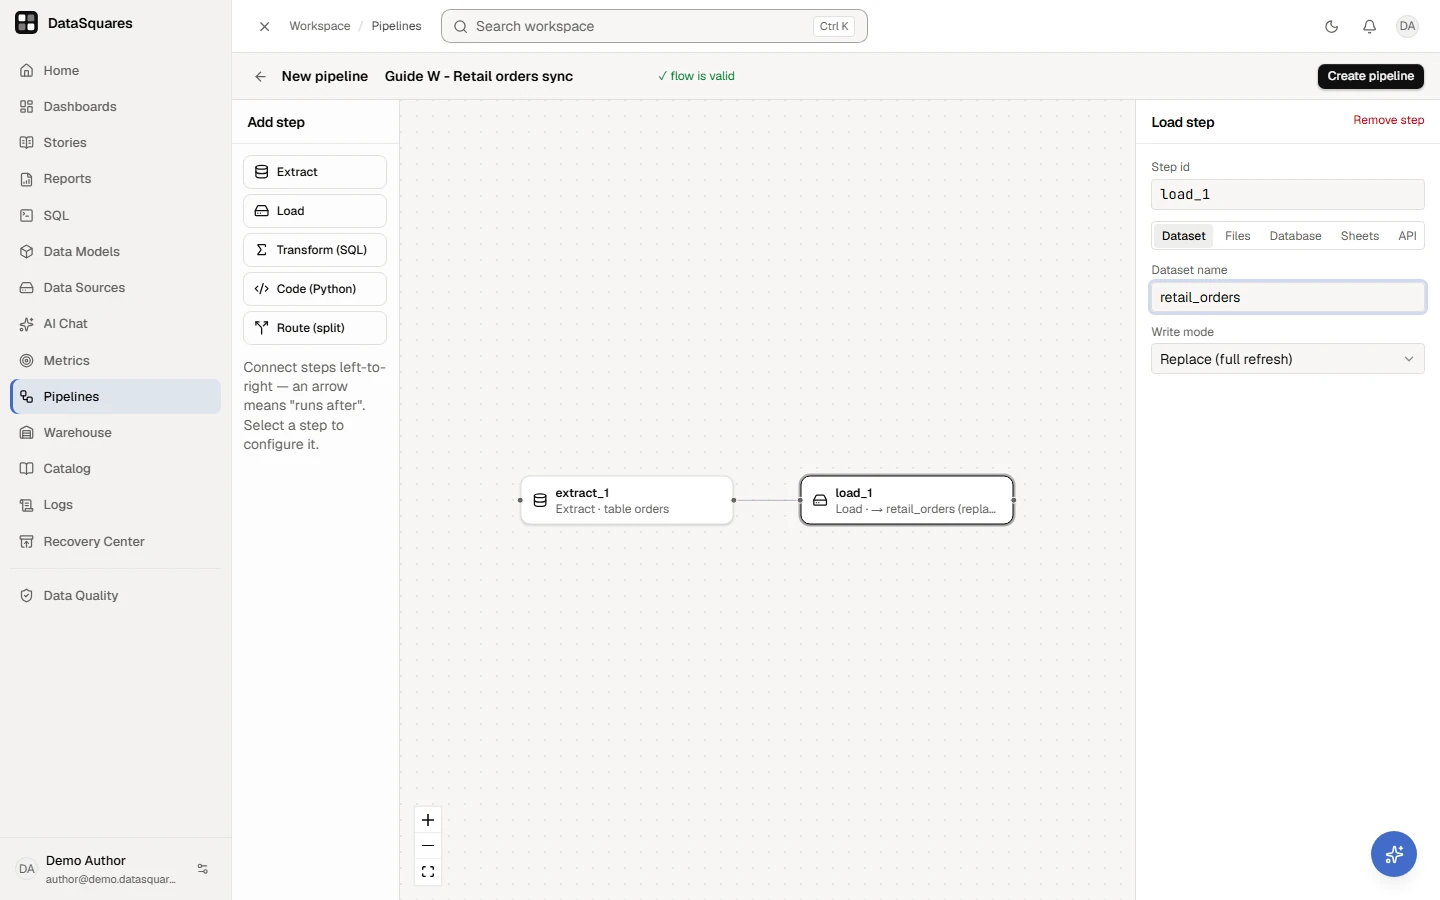
Select the Load step to name the managed dataset it writes and choose the write mode: replace the data each run, or append to it.
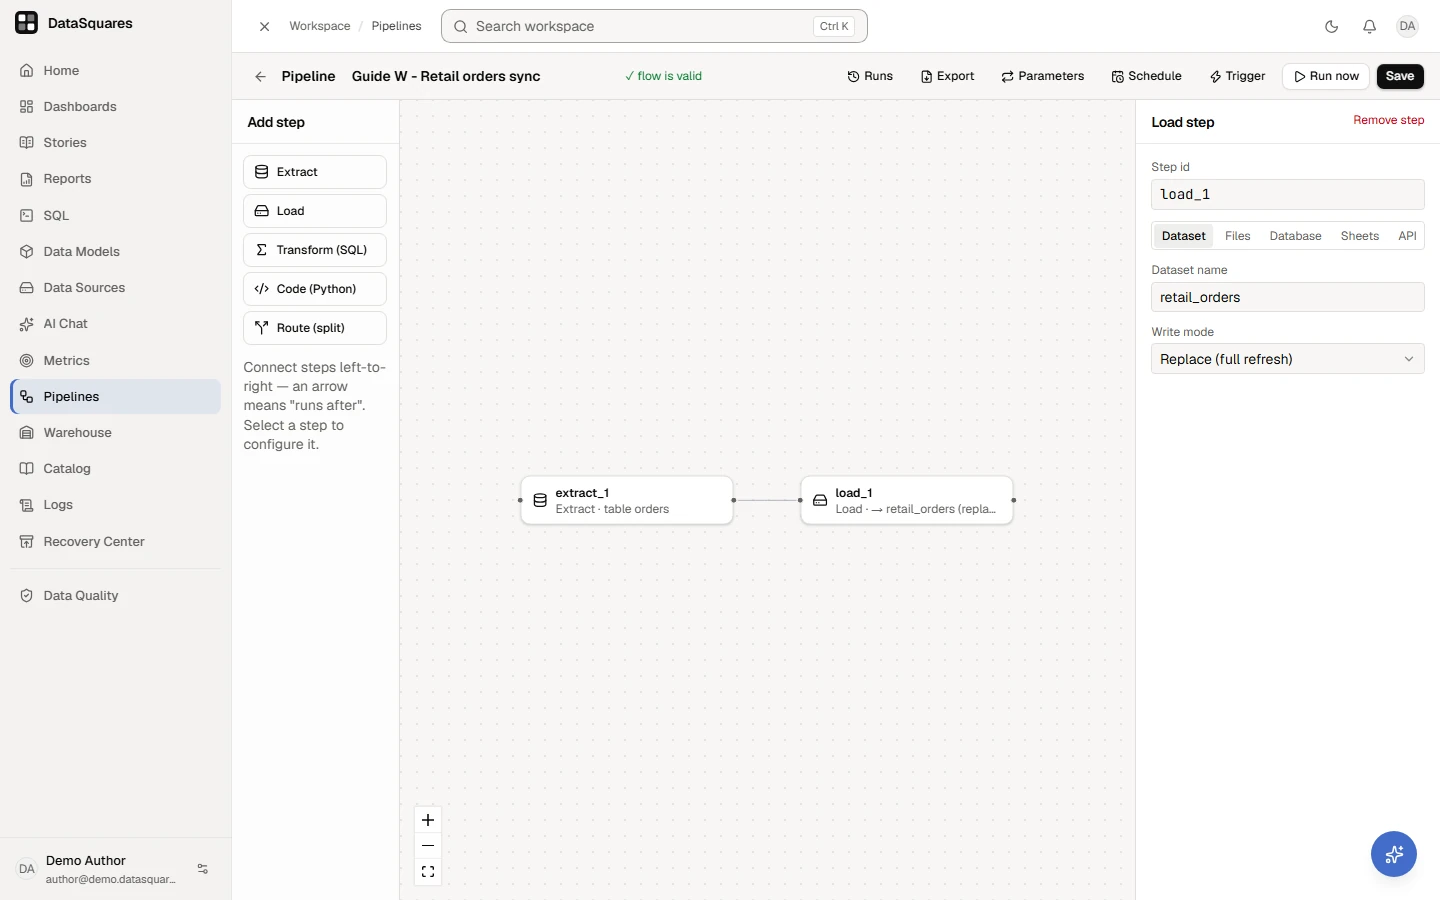
Choose Create pipeline. The pipeline is saved and its editor reopens, with Run now, Schedule and Trigger for when the execution plane is available.
The editor
Section titled “The editor”Three panes: an Add step palette on the left, the canvas in the middle, and a config drawer for the selected step on the right. Drag between steps to connect them — an edge means runs after, and that’s how you express ordering, fan-in and fan-out. A DAG holds up to 100 steps.
Extract
Section titled “Extract”Pulls rows from a source. The config drawer offers six tabs — Table, SQL, CDC, Files, REST and SaaS — and a step uses exactly one of them.
Pick a Source (a database or warehouse connection — see
What Extract can pull from) and a table
(schema.table). The whole table is read, unless you set a cursor — see
Incremental below.
Pick a Source and write a query. Use this to filter, join or pre-aggregate at the source, where the database is already good at it.
Consume a CDC stream — inserts, updates and deletes captured off a PostgreSQL or MySQL source by managed Debezium. You name the stream id, not a connection: Debezium already holds the source credentials.
Pair it with a Merge (upsert by key) load to apply the changes.
Read objects out of a store — S3 and the S3-compatible stores, Azure Blob, ADLS Gen2, GCS, SFTP, or plain HTTPS.
Connect your storage in the connection wizard under Data Sources (or create it via the REST API).
From the object browser. A folder (or one object) too large to import —
past the import’s limits on objects, bytes or rows — is refused there with
Create a pipeline dataset, which opens the editor on a new pipeline: a
Files extract of the same objects and a replace load into a dataset of the
name you gave. The path reads what the import would have (a prefix such as
exports/2026-08 becomes exports/2026-08**, every key that starts with it);
Folder names are columns is on when it was on for the import; and Max
files per run is raised to the folder’s object count when it holds more than
the default, up to 10 000. Nothing runs until you save and run it.
| Field | What it does |
|---|---|
| Path | a prefix or glob inside the store: raw/orders/, raw/orders/*.csv |
| Format | auto (by file extension), csv, json or parquet |
| Compression | auto, none, gzip or zstd |
| Union by name | on by default — files whose columns differ by name still stack, so schema drift across a folder of daily exports just works |
| Only new files | only objects newer than the last successful run (off by default) |
| Max files per run | one run’s intake bound — default 1000, max 10 000. A full read that matches more objects is refused, never cut short: raise it (up to 10 000), narrow the path, or turn on Only new files, which reads the oldest that many per run and catches up on the next runs |
| Folder names are columns | off by default (hivePartitioning in the pipeline file). Folders named key=value (sales/year=2026/month=10/…) become columns of every row — the layout Spark, Hive, Glue, DuckDB and the Files load target write. Values are text, so month=01 keeps its zero; type them with a cast step or hiveTypes. A column of the same name inside the files takes the folder’s value |
CSV files take the usual extras (delimiter, header, quote, escape, null string, skipped rows, explicit column types, date/timestamp formats). A date or timestamp the reader would land as something other than what the file says fails the run instead, naming the column, the value and the file:
- A date marked BC, as Postgres writes it (
0044-03-15 BC), which would land as the year 44 AD: in a column typed as a date or detected as one, anywhere in the file, and in each date of a list of dates. Write such dates as0044-03-15 (BC), or type the column as text (VARCHAR) to keep them as written. infinity,-infinityandepochin a column read with the date (or timestamp) format, which would read them as 1900-01-01. Leave the format out when the dates are written asYYYY-MM-DD: they then load as infinite dates and 1970-01-01. Or type the column as text.- A timestamp with a time zone that cannot be read (
05/01/2026 10:00,0044-03-15 10:00:00+00 BC), which would land as empty. Write it as2026-01-05 10:00:00+00, or type the column as text. An empty value stays empty.
Without a format, dates or timestamps that are not written as YYYY-MM-DD
(05/01/2026, 2026/01/05 10:00) are read with a format the reader works out
from each file, and that format reads infinity, -infinity and epoch as
1900-01-01 without failing the run: set the date (or timestamp) format so the
run refuses them, or type such a column as text.
Large folders. A Files extract reads a folder of any size. A read bigger than a few gigabytes goes in windows, one after another in listing order, and still lands as one table: nothing is skipped or cut short, and an object bigger than a window is read on its own. One run may take up to 24 hours, and a run that fails starts again from the first window, so a read that needs longer (about a terabyte over a slow link) does not finish: narrow the path, or turn on Only new files to load the backlog across runs.
The table has the columns and types one read of all the files gives, even when
the files differ from window to window: a column a later export added, a number
a later file writes with decimals, a header whose case changed, a newest export
that holds only its header, a column left empty for a while, a JSON field that
is null in a whole export. Where only the files themselves hold one read’s
values, a window is read again, so every value lands as one read lands it: a CSV
column that turns out to hold text later keeps each value’s spelling (1.50
stays 1.50), a JSON field one read keeps as text or as JSON text (a timestamp
beside an empty string, a number beside a string, a list beside a number) keeps
it, and Parquet files that type a column differently are each converted once,
straight to one read’s type. JSON fields are typed from the first 20,480 records
of each file, so a large JSON file whose later records hold something its first
ones do not (a decimal among whole numbers, a string among numbers, a new key)
is read again with the types one read gives. A JSON file read again reads only
the fields that need it and keeps the rest as its first read gave them, so its
dates and timestamps keep one read’s conversion (an offset such as +02:00
turned into UTC). A JSON field that holds whole numbers of both signs is stored
as a decimal number, as one read stores it, and files of only empty objects or
nulls beside files of objects load as rows of empty values. The read takes
longer, the data is the same; explicit column types for a CSV avoid the second
read. A file that is read again must not change in between: a file rewritten
while the read runs, in CSV, JSON or Parquet, is never mixed with its earlier
version or read with the types its earlier version gave. That attempt fails,
naming the file, and a retry reads every file afresh.
A large read refuses only what windows cannot rebuild, and names the field and
the files: JSON keys that differ only in case, a JSON object one read might turn
into a map - the lines themselves too, when their keys each appear in few of the
lines across the files, or number 200 or more and differ from file to file -
JSON files whose lines are arrays or single values beside files whose lines are
objects (one read keeps every line whole in a single json column), a JSON date
or timestamp in a field a file must be read again for (a second read cannot
convert it exactly as one read does: an offset would be lost, or a time cut to
its date), and, rarely, a JSON field with whole numbers of both signs in a
window of several large files, where which sign each file’s first 20,480
records hold cannot be told, or a Parquet column of signed whole numbers below
-2^53 beside files that store it unsigned (one read rounds those through a wider
integer type).
With Union by name off, one read takes its columns from the first file and its types from the first files, then reads every later file into them:
- Parquet: the first file’s columns and types. A column the first file lacks is left out; a file missing one of its columns fails.
- CSV: the first file’s columns; types sniffed from the first 10 files
together (one type stays, whole numbers beside decimals give decimals,
anything else gives text, and a column the 10 leave empty is text). A later
file whose own values sniff as another type fails the read, unless they are
whole numbers where the 10 give decimals, or the 10 give text. Dates and
timestamps are read with the formats sniffed from those 10 files, so
01-02-2026in a later file reads as they read it. - JSON: the columns and types of the first 32 files merged, keys as well as types; a later file’s decimal is rounded into whole numbers, and a key the 32 never hold fails the read.
A large read gives the same, and refuses a CSV or JSON window whose columns differ from the first file’s, and CSV dates or timestamps in files a window sniffs apart from the first 10 unless the CSV date and timestamp formats are set. One case differs: a large JSON file whose records past its first 20,480 hold a key or a kind of value its own first records do not fails a large read even where another file’s first records would let one read load it: turn Union by name on, or narrow the path.
A CSV column with hexadecimal text (0x1F) beside decimals fails one read but
loads in windows, with the hexadecimal values as numbers (31). A JSON date field
whose strings mix orders in one large file (01-02-2026 written month-first
beside day-first dates, or two- and four-digit years) can load differently in a
large read, as it can in one read on another machine; ISO dates and timestamps
(2026-01-02, 2026-01-02T10:00:00Z) are not affected.
A partitioned folder, read with its partitions typed:
{ "sourceId": "8f14e45f-…", "file": { "path": "sales/**/*.parquet", "hivePartitioning": true, "hiveTypes": { "year": "integer" } }}hiveTypes takes the cast types (string, integer, double, boolean,
date, timestamp) and must name partition folders exactly. A folder typed
date whose value is marked BC (dt=0044-03-15%20BC) is refused before
anything is downloaded: name it 0044-03-15 (BC), or leave the key out of
hiveTypes to keep the value as text.
Every object the path matches must be a data file under the same key=value
folders. Anything else is refused before a byte is downloaded, and the message
names the object and the fix:
- A non-empty marker or checksum —
_SUCCESS,_committed_*,.crc— inside a partition folder or above it (an empty_SUCCESSis skipped like any empty object), and anything under a hidden folder, such as the_temporary/an unfinished write leaves behind. Spark, Hive and Arrow treat a name starting with_or.as hidden (a_key=valuefolder is still a partition); folder partitions refuse such a name rather than guess that it can be skipped. A hidden name the path asks for is read: one it names, such assales/_landing/, or one a path segment that itself starts with_or.matches at the same depth, such assales/_staging_*/**/*.csv. A bare*or**does not count. - With Format
auto, a file whose extension names no format — it would be read as the other files are. - A file outside the partition folders, such as
sales/part-9.parquetbesidesales/year=2026/….
The fix a refusal names is a glob that still reads every data file the path
matched and leaves the refused objects out: the data files’ extension for a
marker (sales/**/*.parquet), their folders for a hidden folder
(sales/year=*/*.parquet), and their folders plus the start of their name for
a hidden file that shares their extension (sales/year=*/part-*.parquet) or
for data files with no extension (sales/year=*/0* for Hive’s 000000_0).
It is always your own path narrowed, so it never reads more than the path
does: sales/year=*/* gets sales/year=*/*.parquet, not sales/**/*.parquet,
which would also read a sales/backup/ copy. When no such glob fits, it says
to narrow the path.
Table formats are refused too. A Delta, Hudi or Iceberg table,
or a Spark streaming sink, keeps files its log no longer counts — files a
later write removed or replaced, or a batch that never committed — so its
folders cannot be read as plain files. That includes the tables a pipeline’s
own Delta Lake and Apache Iceberg file destinations write: a replace
keeps the old files for time travel. With folder partitions on, a read that
matches files in such a table’s folder is refused: a folder holding
_delta_log/, .hoodie/ or _spark_metadata/, a folder whose metadata/
holds Iceberg’s version-hint.text or *.metadata.json files, or a partition
folder holding Hudi’s .hoodie_partition_metadata. The tables are found in
the whole listing under the path’s literal part, so a glob that leaves the log
out, such as tbl/year=*/*.parquet, is refused as well. So is a path that
starts inside a table, in a partition folder such as tbl/region=emea/ or in
an Iceberg table’s data/: the log sits above it, so the extract also looks
in each folder above such a path, up to the first one that is neither a
partition folder nor data/. The Files extract does not read table formats
yet; Delta Lake and
Apache Iceberg list the ways in today.
Pull a paginated JSON HTTP API. It needs a REST API connection — the URL and any auth headers live encrypted on the connection, and the step schema refuses an inline secret rather than letting it ride along in the DAG.
| Field | What it does |
|---|---|
| Records path | where the record array lives, JSONPath-lite: $.data.items |
| Columns | project each record into named columns by path ($.customer.id) |
| Pagination | none, offset, page, cursor, or link_header (RFC 5988) |
| Page size | up to 10 000; max pages defaults to 1000 |
| Rate limit | space requests out, up to 100 per second |
| Incremental | send the last watermark back as a query param on the next run |
REST incremental is its own thing — a query param plus the record field the watermark is read from, with an optional first-run value.
Pull a SaaS app through a curated, sandboxed connector: Salesforce, HubSpot, Stripe, Google Analytics 4, Shopify or Jira. Pick the provider, its connection (credentials stored encrypted), and optionally the resources to pull — leave it empty for the provider’s standard set (e.g. Stripe: charges, customers, invoices, subscriptions).
The connector runs inside a hardened container — pinned image, non-root, capability-dropped, memory/time capped, credentials on a RAM-only mount that vanishes with the container. You never supply a URL: each connector is pinned to its vendor’s own API domain, and the only identifiers you provide (a shop name, a site name, a property id) are strictly character-gated.
Incremental is on by default: each resource keeps a cursor watermark
(updated_at, SystemModstamp, created, …) that advances only when the
run succeeds — a failed run never skips rows. HubSpot objects are read
through its CRM search API on hs_lastmodifieddate, so a run fetches only the
records changed since the last one.
Schema drift (wire extracts)
Section titled “Schema drift (wire extracts)”Sources change mid-life: a column gets added, dropped, or retyped. On the
Table and SQL extracts you can opt into a managed drift policy with
schemaDrift:
allow— a new column flows through; a removed column keeps its place, null-filled, so downstream shapes stay stable instead of breaking the night a source column disappears; a retyped column takes the new type with a loud warning in the step log.strict— any drift fails the step, naming the exact columns. The governance mode for shapes that must never move silently. (Strict is checked on the single-stream path, so it can’t be combined withpartition.)
The baseline is a per-step schema snapshot that advances only when the part
actually lands. Leaving schemaDrift unset keeps the legacy behavior:
whatever the source has now is what lands.
{ "sourceId": "8f14e45f-…", "table": "public.orders", "schemaDrift": "allow" }Object-store connections
Section titled “Object-store connections”Connect S3, Azure Blob, ADLS Gen2 or Google Cloud Storage in the connection wizard (Data Sources → Connect Source → Cloud Storage & Lakes), or create the connection with the REST API. Either way it appears in every picker that wants a store: the Files extract tab, the Files load target, and the file-arrival trigger.
curl -X POST https://<your-host>/api/sources \ -H "Authorization: Bearer $DS_TOKEN" \ -H "Content-Type: application/json" \ -d '{ "name": "Data lake (S3)", "type": "s3", "config": { "bucket": "my-data-lake", "region": "eu-west-1", "accessKeyId": "AKIA…", "secretAccessKey": "…" } }'The type is s3, azure_blob, adls_gen2 or gcs — or one of the
S3-compatible stores, in Preview: minio, ceph, cloudflare_r2,
backblaze_b2, wasabi, digitalocean_spaces, scaleway_object_storage,
ovh_object_storage or ibm_cos — and the token needs the source:write scope.
Each takes its own config:
| Type | Config |
|---|---|
s3 |
bucket, accessKeyId, secretAccessKey; region defaults to us-east-1 |
| the S3-compatible stores | as s3, plus a required endpoint in the store’s own form; the region is derived where the store decides it (S3-compatible stores) |
azure_blob / adls_gen2 |
account, container, plus either accountKey or sasToken |
gcs |
bucket and credentials — the service-account key JSON, as a string |
What Extract can pull from
Section titled “What Extract can pull from”| Family | Engines | How it reads |
|---|---|---|
| Postgres wire | Postgres, Redshift, CockroachDB, TimescaleDB, Neon, Supabase, AlloyDB, YugabyteDB, Azure/RDS/Cloud SQL Postgres, and more (17) | streaming cursor |
| MySQL wire | MySQL, MariaDB, TiDB, SingleStore, PlanetScale, Azure/RDS/Cloud SQL MySQL, and more (11) | streaming cursor |
| TDS | SQL Server, Azure SQL, Azure Synapse | streaming cursor |
| Bulk unload | Snowflake, BigQuery | the warehouse’s own COPY INTO / EXPORT DATA into your staging bucket |
| Object stores | S3 and the S3-compatible stores (MinIO, Ceph, R2, B2, Wasabi, Spaces, Scaleway, OVHcloud, IBM COS), Azure Blob, ADLS Gen2, GCS, SFTP, HTTPS | the Files tab |
| HTTP | any paginated JSON API | the REST tab |
Redshift row-streams over the Postgres wire by default and upgrades to a bulk
UNLOAD when the connection has staging configured — see
bulk staging.
Fabric Warehouse speaks TDS too, but a pipeline cannot read from it yet: it signs in only with Microsoft Entra ID, and the pipeline worker signs in to SQL Server-family databases with a username and password. The extract is refused before it connects, saying why, and a schedule that keeps meeting the refusal pauses itself.
Incremental extract
Section titled “Incremental extract”Set a cursor column (“Cursor column (empty = full pull)”) and a Start from value, and each run pulls only a bounded window: rows greater than the last watermark and less than or equal to a freshly probed maximum. Two properties matter:
- The cursor advances only when the whole run succeeds — a failure halfway through never skips rows on the next run.
- An idle window is a 0-row success, not an error.
Partitioned extract
Section titled “Partitioned extract”A single cursor is one connection and one thread. Split the key range and pull it in parallel:
{ "id": "extract_events", "type": "extract", "config": { "sourceId": "8f14e45f-…", "table": "public.events", "partition": { "column": "id", "count": 8 } }}count is 2–64 (the worker also caps real concurrency, default 4). Split by an
orderable, roughly-uniform column — typically the primary key; a heavily skewed
column just produces unbalanced partitions.
Transform (SQL)
Section titled “Transform (SQL)”Fully enabled. A transform step is either a declarative op chain or raw SQL — exactly one of the two.
Both compile through one shared compiler, so the SQL you preview is byte-for-byte
the SQL the worker runs. Every identifier is quoted per dialect and every literal
is typed; only a derive expression is free-form, and it’s guarded.
What a derive may use. A derive reads the step’s own columns and nothing else: names of its columns, literals,
operators, CASE, casts, IN with a list of values, the common SQL forms (EXTRACT(… FROM …), SUBSTRING(… FROM … FOR …), TRIM(… FROM …), position(a IN b)) and the listed scalar functions (text, numbers, dates, conditions, arrays
with lambdas). It is refused, naming what it found, when it names another table or database, uses IN with a table,
a subquery, a dictionary or join lookup (dictGet, joinGet), a table function (remote, url, file, s3, …), an
aggregate or window function, a comment, or a function not on the list. A column whose name is a SQL word is written
quoted ("on"), and spaces are plain spaces. The check runs when the pipeline is saved or previewed and again when
it runs; a value in a filter, pivot or check always stays one string, whatever characters it holds.
The 21 ops
Section titled “The 21 ops”Up to 50 ops per chain, grouped in the drawer:
| Group | Ops |
|---|---|
| Rows | Filter · Sort · Limit · Deduplicate · Assert (quality gate) |
| Shape | Select (keep/drop/rename) · Derived column · Cast · Aggregate · Pivot · Unpivot · Surrogate key |
| Analytics | Window (running totals, lag/lead, first/last per partition) · Rank |
| Combine | Join · Union · Lookup · Exists |
| Semi-structured | Flatten · Parse JSON · Stringify |
As DAG JSON, a chain is just a list:
[ { "op": "filter", "where": { "column": "status", "op": "eq", "value": "paid" } }, { "op": "derive", "column": "net", "expression": "amount - discount" }, { "op": "aggregate", "groupBy": ["region"], "measures": [{ "fn": "sum", "column": "net", "as": "revenue" }] }, { "op": "sort", "by": [{ "column": "revenue", "direction": "desc" }] }]Several of them exist to avoid classic footguns:
- Lookup dedupes the reference side first (
firstMatchOnly, on by default), so a duplicated key cannot multiply your rows. That’s what makes a lookup a lookup rather than a join. - Exists with negate compiles to
LEFT JOIN … IS NULL, sidestepping theNOT INNULL trap that quietly returns nothing. - Window’s
last_valuealways sees the whole partition — without that, the SQL default frame stops at the current row andlast_valuejust echoes it. - Pivot takes an explicit value list (
values: [{ "value": "Q1" }, …]) — static SQL can’t conjure columns it hasn’t seen, so you name the columns you want, exactly like a warehousePIVOT … IN (…). A cell with no rows is an honestNULL, and each cell aggregates with thefnyou pick (sumby default;countneeds no column). - Surrogate key numbers rows from
startAt(default 1). Give it anorderByto make the numbering deterministic — without one, engine row order decides.
Assert — the quality gate
Section titled “Assert — the quality gate”An assert holds up to 32 named checks: rules (any structured predicate —
not-null, ranges, formats), unique keys (rows whose key appears more than
once all fail — keeping one would be Deduplicate’s job), references (the
value must exist in another connected step) and freshness (the newest
timestamp must be no older than a number of minutes). Checks are
NULL-strict: a comparison that can’t be proven fails the check; add
or is_null to a rule if NULLs are acceptable. One assert per chain.
What happens to failing rows is the onFail policy:
fail(default) — any failing row fails the step with per-check counts (amount_positive (2), unique_id (1)), before anything is published. The load is blocked.quarantine— failing rows leave the chain at the gate and land on aquarantineport on the step (amber handle on the canvas), each row stamped with_ds_checknaming the first check it failed. Clean rows flow on as the step’s normal output. Connect the quarantine port to a load (or any step) to inspect or replay the bad rows — a port left unconnected still writes its part, so nothing is ever silently dropped.warn(Warn only) — nothing is filtered or blocked: failing rows flow on, and their counts are recorded on the run.
{ "op": "assert", "onFail": "quarantine", "checks": [ { "name": "amount_positive", "where": { "column": "amount", "op": "gt", "value": 0 } }, { "name": "unique_id", "unique": ["id"] } ]}The preview’s SQL tab shows both statements a quarantining step runs — the pass filter and the quarantine complement.
Raw SQL
Section titled “Raw SQL”Each upstream step is a view named after it, so raw SQL reads like
SELECT * FROM extract_orders JOIN extract_customers USING (customer_id). It’s
the escape hatch for anything the op set doesn’t express.
Preview
Section titled “Preview”Preview shows the step’s compiled SQL straight away, and its rows from the last successful run’s data: 50 rows in the editor, up to 500 through the API. A raw-SQL step shows its SQL only.
AI authoring
Section titled “AI authoring”Describe the transform in plain language and choose Suggest recipe to get back a validated declarative op chain — never raw SQL, never a black box. You see the ops, you can edit them, and they validate like any hand-built chain (one automatic repair round if the first attempt doesn’t validate). Each suggestion uses AI credits, as the editor says.
Suggest recipe writes the step’s recipe, so it is there for people who may edit the pipeline; a role that may only view pipelines doesn’t see it.
What the AI is told about the data comes from the pipeline’s last successful
run, read by DataSquares itself: each upstream step’s column names and types,
and how many rows it produced. Never a value, never a statistic. Every column
the suggested ops name is then checked against those columns, op by op, the way
the run will see them: a column a select renames, a derive or parse adds,
or an aggregate or pivot produces counts from that op on, and one a select
drops does not. A join’s, lookup’s or exists’s other side is checked against
its own step’s columns. An op that names a column the data doesn’t have goes
back to the AI in its repair round; if its second answer still does, you’re
told which column. A step that hasn’t run yet, or didn’t run in the last
successful run, has no known columns: ops reading it aren’t checked, and the
AI is told so. Run the pipeline once and its columns are known. If the AI can’t be reached or takes too
long, you’re told so and asked to try again; the step is left as it was. When the suggestion is
refused because the workspace’s AI credits are used up, or its
AI controls pause it, the message is the one the rest of
the app gives you: a workspace admin is pointed to where to fix it, everyone
else is told to ask one.
Run in parallel across workers
Section titled “Run in parallel across workers”Tick “Run in parallel across workers” and set Partitions (2–64) to fan a transform across the worker fleet. The rules are strict because correctness is:
- Row-wise ops only — filter, select, derive, cast, parse, stringify, flatten. Anything that has to see rows together (aggregate, dedupe, join, union, lookup, exists, sort, limit) is refused by name.
- A windowed derive (an expression containing
OVER) is refused — a window reads other rows. - Raw SQL can never be partitioned — it can’t be proven row-wise.
- The step needs exactly one upstream (it slices that input’s parts).
Large aggregates and joins don’t need this: at scale they’re pushed down into the warehouse instead.
Where a transform runs
Section titled “Where a transform runs”You don’t pick. Small inputs run in-process on DuckDB; past a size threshold a declarative chain is pushed down into ClickHouse, reading Parquet straight from the lake. Same compiler, same results.
Flowlets
Section titled “Flowlets”A chain you’ll want again — “dedupe by key”, “standardize an address” — can be saved as a flowlet: a reusable, parameterized, versioned fragment you instantiate into other pipelines.
Code (Python)
Section titled “Code (Python)”For what SQL can’t express. Your script runs in a hardened sandbox: a digest-pinned image, no network, non-root, all Linux capabilities dropped, with hard memory and wall-clock caps.
The contract is I/O-shaped: Parquet in → Parquet out. Read from DS_IN (one
directory per upstream step, named by step id) and write one or more
*.parquet files into DS_OUT.
import os, globimport pandas as pd
src = os.path.join(os.environ['DS_IN'], 'extract_orders', '*.parquet')df = pd.concat(pd.read_parquet(f) for f in glob.glob(src))
df = df[df['amount'] > 100]
df.to_parquet(os.path.join(os.environ['DS_OUT'], 'big_orders.parquet'), index=False)duckdb, pyarrow, pandas and numpy are pre-installed. There’s no network, so there
is no pip install at run time — that’s a security property, not a gap.
| Setting | Range |
|---|---|
| Code | up to 1 MiB (bulk data ships through the lake, not the script) |
| Timeout | 10–3600 s (default 600) |
| Memory | 256–16 384 MB (default 1024) |
Nothing the script prints is trusted as a result — the worker validates that the outputs actually parse as Parquet. The step needs the sandbox executor enabled server-side; if it isn’t, it refuses cleanly.
Route (split)
Section titled “Route (split)”Send rows down named ports by condition. First match wins, and rows
matching nothing land on the default port (rest unless you rename it) — so
every input row lands on exactly one port. 1–16 routes.
{ "id": "split_by_region", "type": "route", "dependsOn": ["extract_orders"], "config": { "routes": [ { "port": "emea", "when": { "column": "region", "op": "in", "values": ["DE", "FR", "ES"] } }, { "port": "amer", "when": { "column": "region", "op": "eq", "value": "US" } } ], "defaultPort": "rest" }}A downstream step names the port it consumes:
{ "id": "load_emea", "type": "load", "dependsOn": ["split_by_region"], "fromPorts": { "split_by_region": "emea" }, "config": { "datasetName": "orders_emea", "mode": "replace" }}A route splits exactly one incoming step, and a consumer that doesn’t name its port is refused at save.
Five target kinds, on tabs — Dataset, Files, Database, Sheets and API:
- Dataset — a managed dataset in your ClickHouse. Modes: Replace, Append, or Merge (upsert by key).
- Database — write straight back into your own database or warehouse.
- Files — Parquet, CSV, JSON or Excel (
.xlsx) into an object store, optionally hive-partitioned, or a Delta Lake or Apache Iceberg table (Preview). - Sheets — a tab of a Google Sheets spreadsheet.
- API — batched POSTs to a webhook connection.
Each is covered properly — with merge semantics, CDC deletes, and multi-sink fan-out — in Where pipelines can write.
Every step carries its own retry policy: maxAttempts 1–10 (default 3, counting the first attempt), an initial interval, and a backoff coefficient.
"retry": { "maxAttempts": 5, "initialIntervalMs": 2000, "backoffCoefficient": 2 }Parameters, conditions and loops
Section titled “Parameters, conditions and loops”In the editor, Parameters opens one dialog for all three.
Parameters are inputs a run is given — text, number, on/off or a list,
each with an optional default and optionally required. Use one in any step
setting as {{ params.name }} (for example a table sales_{{ params.region }}
or a page size {{ params.size }}). When you run a pipeline by hand, it asks
for the values, pre-filled with the defaults; scheduled and triggered runs
use the defaults, and a webhook call can pass {"parameters": {…}}.
Conditions — run a step only when… a parameter is (not) a value, is one of a list, or is on/off. A step whose condition is false is skipped, and so is anything that reads only from it; the run shows them as skipped, with the reason.
Loops (for each) repeat the steps you choose once per item — over a
fixed list or a list parameter (up to 100 items). Inside those steps,
{{ item }} is the current item and {{ index }} its position. A step
after the loop that reads a looped step receives every item’s output — a
load writes them all into one dataset. Iterations show on the run as
the step id, two underscores, the loop’s id and the item’s position — for the
first loop you add, load__loop10, load__loop11, ….
Each run is resolved when it starts: the values it uses and the exact steps it runs are kept with the run (shown on the run panel), so editing the pipeline later never changes a run that already exists. A value that doesn’t fit — the wrong type, a missing required one, one that makes a setting invalid — is refused before anything runs.
There is no repeat until: a run always finishes. To keep something going until a condition holds, use a schedule or a trigger.
Validation
Section titled “Validation”The editor validates continuously: a “✓ flow is valid” chip, or an issue count with a Fix before saving list — unconnected steps, missing config, cycles, a route consumer with no port named.
Create pipeline / Save commits. If someone else edited the pipeline while you had it open, you’ll be asked to reload — last write doesn’t silently win.
Schedules
Section titled “Schedules”Schedule sets the cadence:
| Preset | Fires |
|---|---|
| No schedule (manual only) | never — you run it |
| Hourly | every hour |
| Daily (02:00) | once a day |
| Weekly (Mon 02:00) | once a week |
| Micro-batch (every N seconds) | every N seconds — 15-second floor, max 86 400 |
| Custom (cron) | a full cron expression (e.g. 30 6 * * 1-5) |
Cron schedules take a timezone (default UTC). A schedule is either cron or every-N-seconds, never both, plus an Enabled toggle.
Schedules fire. A poller ticks every ~10 seconds and starts every due schedule; each row is claimed atomically, so multiple API instances never double-fire. After downtime it fires once for the latest missed occurrence and re-arms — it doesn’t stampede through every window you were down for.
Triggers
Section titled “Triggers”A schedule answers when; a trigger answers because of what. Open Trigger in the editor toolbar and pick a When. A pipeline can have both a schedule and a trigger.
When files arrive in a folder
Section titled “When files arrive in a folder”Watch a folder on S3 or an S3-compatible store, Azure Blob, ADLS Gen2, GCS or SFTP and run when new objects land. (The storage picker lists your connected object-store sources created under Data Sources.)
| Field | Meaning |
|---|---|
| Storage + folder/pattern | what to watch |
| Wait for quiet (seconds) | don’t fire while the newest object is younger than this — 0–3600, default 60 |
| Wait for at least | fire only once N new files are waiting (default 1) |
Two things make this safe:
- It baselines on first observation, so turning it on never retro-fires the folder’s existing history.
- The quiet period is the point. A multipart upload lands as several objects over several seconds; firing on the first one reads a half-written batch. This is the single most common event-trigger bug, and the default guards against it.
After another pipeline finishes
Section titled “After another pipeline finishes”Pick the upstream pipeline and whether to chain only if it succeeded (the default) or whenever it finishes, even on failure. A pipeline can’t follow itself — that’s refused at save.
When an external system calls a URL
Section titled “When an external system calls a URL”A URL you paste into whatever already knows the data is ready: a CI job, a vendor’s “callback URL” box, a curl at the end of someone else’s script.
-
Add the webhook trigger to the pipeline and save.
-
Ask for the URL. It’s a write-grade act — handing over a credential — so this call is authenticated:
Terminal window curl -s https://<your-host>/api/pipelines/<pipeline-id>/webhook \-H "Authorization: Bearer $DS_TOKEN"{"enabled": true,"url": "https://<your-host>/api/pipelines/<pipeline-id>/webhook?token=9f2c…","token": "9f2c…"} -
Have the external system POST to it — no body needed. You get
201and the new run row back:Terminal window curl -X POST "https://<your-host>/api/pipelines/<pipeline-id>/webhook?token=9f2c…"The token can ride a header instead, if the caller prefers:
Terminal window curl -X POST https://<your-host>/api/pipelines/<pipeline-id>/webhook \-H "x-datasquares-token: 9f2c…"
When a trigger can’t fire
Section titled “When a trigger can’t fire”Triggers use the same ladder as a manual run: the product must be licensed, a concurrency slot must be free, the plan allowance must not be exhausted, and there must be warehouse storage for the load. With no worker online, the run waits in the queue. A trigger can never skip a rung that a schedule respects. If one is failing, the editor toolbar shows “Trigger error” and the dialog says “This trigger is failing.”
A file-arrival trigger pointed at a database connection, a connection from
another workspace, or a pipeline following itself is refused at save (422).
Pointing a trigger somewhere else (another kind, storage, path, upstream
pipeline or outcome) resets its cursor.
Related
Section titled “Related”- Where pipelines can write
- Runs, backfill & monitoring
- Change data capture
- Flowlets
- Connector catalog — what Extract can pull from.