Pipelines
Activations (reverse-ETL)
While standard pipelines extract data into DataSquares, Activations perform governed reverse-ETL: sending curated business metrics and managed datasets out to a webhook endpoint on automated schedules.
Every activation delivers to a webhook connection: an endpoint URL with an optional signing secret and optional static headers, saved under Data Sources. Activations deliver only to webhooks: there is no built-in destination for a SaaS or CRM tool. To feed one, point the webhook connection at a receiver that writes to it.
Manage activations under Pipelines → Activations.
What you can activate
Section titled “What you can activate”| Source Kind | Description | Query Execution & Scope |
|---|---|---|
| Metric | A governed metric (current scalar value or timeseries) | Evaluated through the semantic engine under a pinned run-as identity |
| Dataset | A managed dataset in the DataSquares warehouse | Read via tenant-scoped database drivers: every column, or only the columns its field mapping sends |
A dataset run reads at most 10,000 rows unless you raise its row limit (in its field mapping, up to the server’s row ceiling, 100,000 by default). A dataset with more rows than that is refused, never cut short: the run fails, sends nothing, and says so, rather than sending part of the dataset as if it were all of it. The first such refusal tells the activation’s owner in their notifications (not again while the runs keep being refused that way), as every refused run does.
Security & data governance
Section titled “Security & data governance”Activations are governed in four ways:
-
Pinned run-as identity — An activation runs as the user who created it, with that user’s current role. For a metric activation, Row-Level Security (RLS) policies apply identically to dashboard views.
-
Row-level security for datasets — A dataset activation sends the table’s rows unfiltered, so it is refused when an RLS policy applies to its user: at creation, and again on every run in case a policy was added later. A refused run fails in the run history and sends nothing, and the first such refusal tells the activation’s owner in their notifications (not again while the runs keep being refused that way). To share filtered figures, use a metric activation, which applies the user’s row filters.
-
Sensitivity labels, for every role — What an activation sends leaves DataSquares, so a field with a sensitivity label is never sent, whatever the creator’s role:
- a dataset activation without a field mapping reads every column, so it is refused when any model built on the dataset labels one of its fields;
- a dataset activation with a field mapping reads only the mapped columns: a labelled column it does not map no longer stops it, and a labelled column can’t be mapped (a run refuses one that was labelled after it was mapped);
- a metric activation is refused when its metric reads a labelled field’s data (its measure reads one, or it filters on one), an admin’s activation included; a metric whose measure reads none is sent, whatever else its table holds.
The first refused run tells the activation’s owner in their notifications.
-
Destination redirect protection — Target webhook URLs are strictly validated before each transmission; HTTP 3xx redirects are refused to prevent destination hijack.
The new activation form
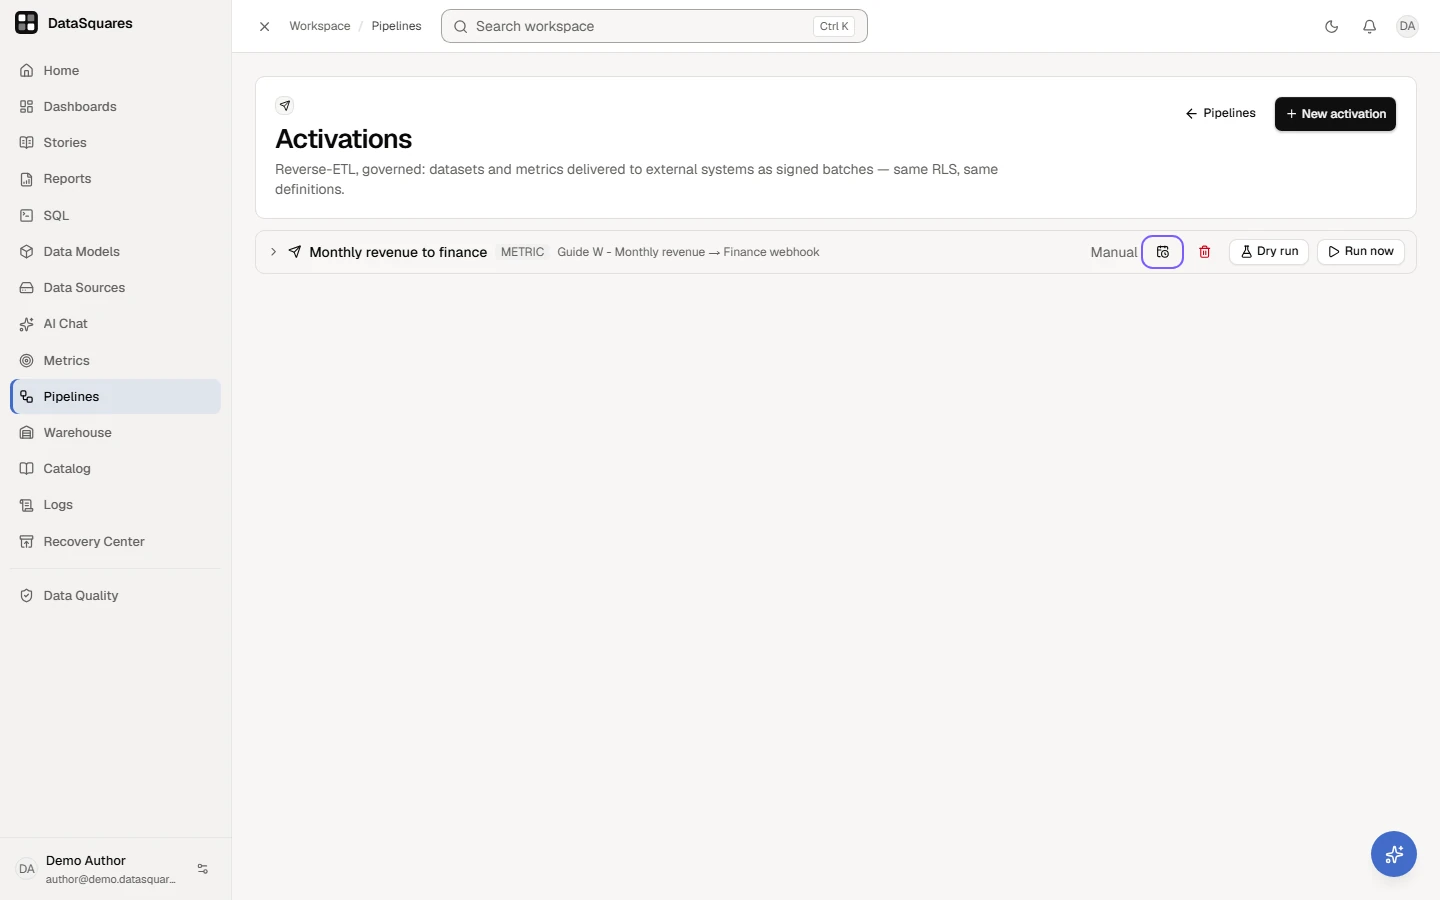
Section titled “The new activation form”Activations lists each activation as a row: what it sends and where to, when it runs (Manual until it has a schedule), the calendar icon that sets its schedule, Dry run and Run now. New activation asks for a dataset or a governed metric and a webhook destination.
Open Activations from Pipelines. An activation pushes a warehouse dataset or a governed metric to an outside system as signed batches, on a schedule. Each one is a row: what it sends and where, when it runs (Manual until it has a schedule), the calendar icon that sets its schedule, Dry run and Run now.
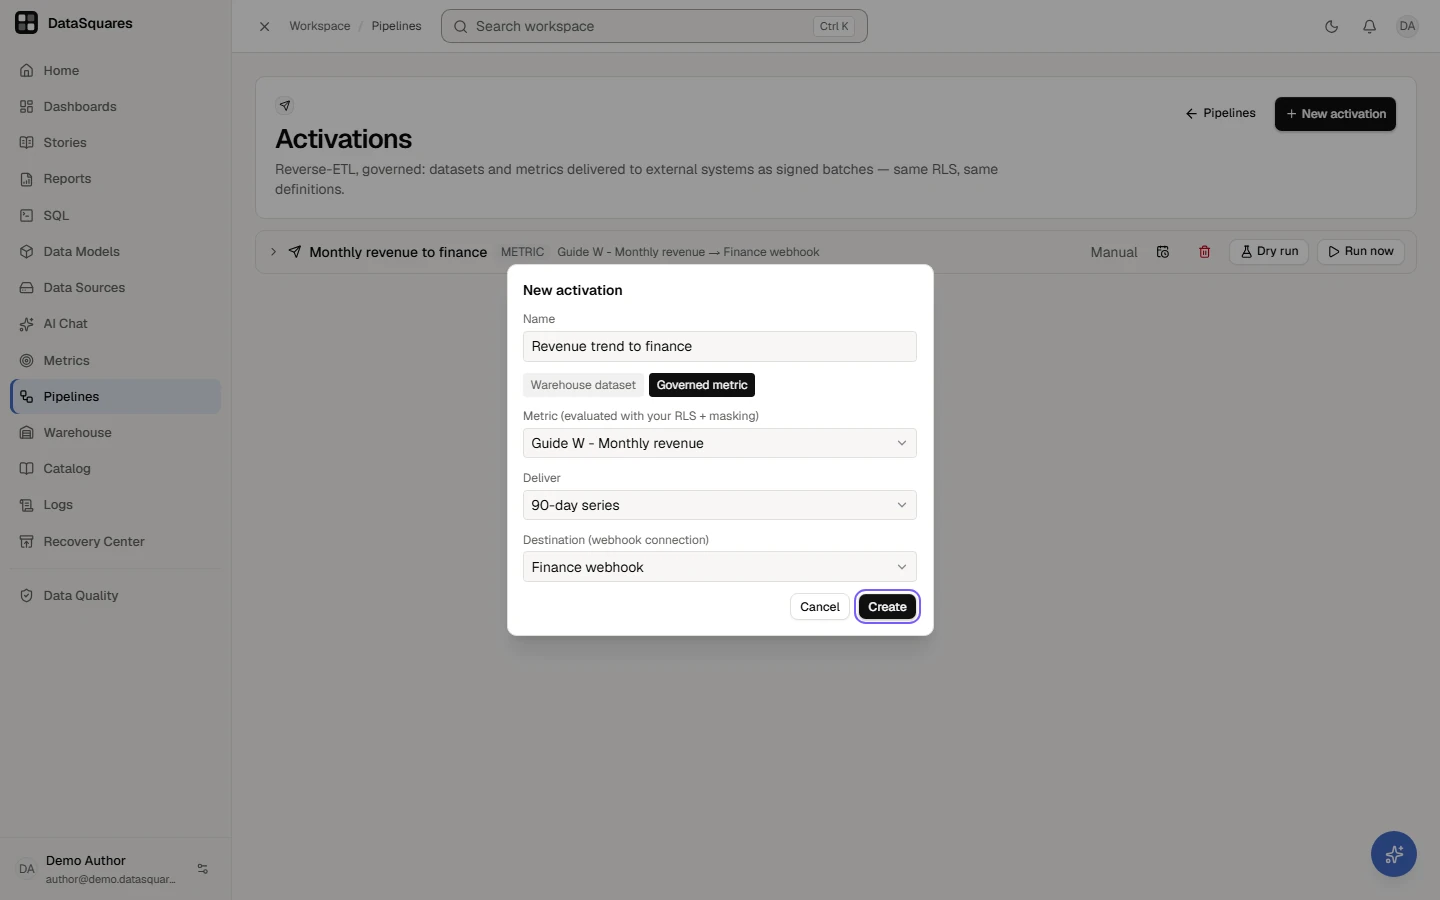
Choose New activation. Name it, pick a Warehouse dataset or a Governed metric (evaluated with your row-level security and masking), and choose the destination, a webhook connection. After you create it, set its schedule from the calendar icon on its row; the row is also where you map the fields of a dataset and try a dry run.
Creating an activation
Section titled “Creating an activation”- Navigate to Pipelines → Activations and click New activation.
- Enter an activation name.
- Choose what to send:
- Governed metric: Pick a metric, then under Deliver choose its current value or a 30-day, 90-day or year-to-date series.
- Warehouse dataset: Pick a managed warehouse dataset.
- Under Destination, choose a webhook connection. The URL, secret and headers are set on the connection; if the list is empty, create one under Data Sources first.
- Click Create.
- For a dataset, choose the fields it sends: the columns icon on its row opens its field mapping.
- Click Dry run on its row to see what it would send, before it sends anything (see Dry runs).
- To deliver on a schedule, click the calendar icon on the activation’s row, choose Hourly, Daily (02:00), Weekly (Monday 02:00) or a custom cron, and a time zone (UTC by default), then click Save schedule. Without a schedule, an activation runs only when you click Run now.
Field mapping
Section titled “Field mapping”A dataset activation sends every column of its dataset under the column’s own name, unless you map its fields. A field mapping chooses the columns to send and the key each is sent as at the destination, and marks one of them as the key: the one that identifies a record there (an id, an email, an external reference). The dry run compares deliveries by that key.
Open it from the columns icon on a dataset activation’s row:
- Each row picks a dataset column and types its destination key. Each key can be used once; tick Key on the row that identifies a record.
- Columns with a sensitivity label are listed but can’t be chosen: an activation never sends them.
- Rows a run reads, at most sets the activation’s row limit (10,000 when blank).
- Save mapping checks the mapping against the dataset as it is now; Remove mapping goes back to sending every column.
Each run checks the mapping again before reading anything. If the dataset has since lost a mapped column (its import changed), the run is refused and names the column, rather than sending rows without it, and the first such refusal tells the activation’s owner. Mapping a dataset’s fields, suggesting a mapping and dry runs need permission to edit pipelines.
Suggest mapping
Section titled “Suggest mapping”When the destination’s keys are many, or named differently from the columns, let the DataSquares AI assistant draft the mapping:
- Under Destination keys, type the keys the destination takes, separated by commas or one per line, or paste a sample record the destination accepts: a JSON object, a JSON list of objects, or CSV with its header line. One suggestion takes up to 200 keys and a sample of up to 100,000 characters.
- Click Suggest mapping. It uses AI credits, as the dialog says.
- Check the rows it adds: your own rows stay as they are, and a suggested key is marked as the key only when you have not marked one.
- Click Save mapping.
What the suggestion sends to the AI is the dataset’s column names and types (labelled columns left out) and the keys you typed or the keys of the sample you pasted. A pasted sample’s values are dropped before anything is sent: only its keys go. No row of the dataset is read. The suggestion may only map the dataset’s columns to the keys you listed: anything else in the AI’s answer is left out, and the dialog says how many. Nothing is saved until you save, and the save is checked like any other. See what the AI reads.
Dry runs
Section titled “Dry runs”Dry run on an activation’s row runs it as its run-as user through every check a run passes (the destination’s address, row-level security, sensitivity labels, the field mapping and the row limit), then sends nothing: no request reaches the destination, no run is added to the history, and the read is not counted as data out.
It shows:
- how many rows a run would send now, and in how many batches;
- the first five rows, exactly as they would be sent (under the mapped keys);
- compared by key with the last successful delivery: the rows added (keys it did not send), changed (the same key, another row), unchanged and removed (keys it sent that the data no longer has).
A successful delivery keeps, for each key, a fingerprint of the key and of its row (an HMAC-SHA256 hash, made with a key only the DataSquares server holds), never the values, and only the latest delivery’s. The comparison needs a key: a dataset activation with a mapping uses its marked key, a metric series its dates, a metric’s current value the metric itself. A dry run with nothing to compare with says why: no key mapped yet, no successful delivery yet, or the key changed since the last one. Rows that share a key are compared as one, and the dry run says how many keys have more than one row.
When a check would refuse the run, the dry run shows the refusal the run history would. The rows are shown to the person asking: when that is not the activation’s run-as user, they see them only if no row-level-security policy limits them on that data.
Delivery protocol & signature verification
Section titled “Delivery protocol & signature verification”Rows are transmitted as batched JSON payloads via HTTP POST requests. With
a field mapping, each row carries the destination’s keys.
Request headers
Section titled “Request headers”POST https://api.yourservice.com/v1/ingestContent-Type: application/jsonX-DataSquares-Timestamp: 2026-10-18T09:00:00.000ZX-DataSquares-Delivery-Id: 550e8400-e29b-41d4-a716-446655440000:0X-DataSquares-Signature: sha256=f9b2c34...Any static headers saved on the webhook connection are sent as well.
Signature verification
Section titled “Signature verification”When the webhook connection has a signing secret, every delivery request
includes an X-DataSquares-Signature header: sha256= followed by the
HMAC-SHA256 hex digest of "{timestamp}.{deliveryId}.{payload}", keyed with
that secret. Without a secret, the header is left out.
Idempotency & rate limiting
Section titled “Idempotency & rate limiting”- Stable delivery IDs — The
X-DataSquares-Delivery-Idformat (<activationRunId>:<batchIndex>) is stable across retries, enabling idempotent ingestion on the receiving server. Retry-Aftercompliance — If the destination endpoint returnsHTTP 429orHTTP 503with aRetry-Afterheader, DataSquares pauses delivery without exhausting retry attempts.
Delivery history & monitoring
Section titled “Delivery history & monitoring”Click any activation row in the Activations table to expand its Delivery history:
- Shows the last 20 runs: when each started, whether it was manual or
scheduled, its status (
succeeded/failed), its rows, and how many of its batches were delivered. - Shows the error of a failed run. When batches failed at the destination, the run’s errors are grouped: click the error to see each group, how many batches and rows it held, and how to fix it.
- Use Run now to trigger an immediate out-of-band delivery to test endpoint connectivity. When it fails, the message leads with the first group’s fix.
Grouped delivery errors
Section titled “Grouped delivery errors”Every batch that fails gets one class from what the destination answered:
| Group | What happened | What to do |
|---|---|---|
| Refused (HTTP 400 or 422) | The destination did not accept the rows | Check the keys and value formats it expects against the field mapping |
| Refused (HTTP 401 or 403) | Not authorised | Check the signing secret and headers on the webhook connection |
| Refused (HTTP 404, 405 or 410) | The address was not found | Check the URL on the webhook connection |
| Refused (HTTP 413) | The batches are too large | Lower the batch size |
| Refused (another 4xx) | Refused by the destination; sending the same rows again gets the same answer | Check what the destination expects |
| Throttled | The destination kept answering 429 (or 503 after asking to wait), after the waits it asked for |
Lower the batch size or run less often |
| Server error | A 5xx answer on every attempt |
Check the receiving service |
| Timed out | No answer in time | Lower the batch size, or check why the service is slow |
| Unreachable | The host did not resolve, or the connection was refused or dropped | Check the host name and that the service is reachable from the internet |
| Address refused | The address is private or internal, or the destination redirected | Use the destination’s final public URL |
A refusal is one group per status; every other class is one group. A destination refused before any batch (a private address) shows as a group held “before anything was sent”.
Related
Section titled “Related”- Governed metrics — Creating standardized business metrics.
- Warehouse — Managing warehouse datasets.
- Webhooks — Event-driven notifications and webhook signature verification.
- Where pipelines can write — Writing data directly into external databases.
- What the AI reads — What Suggest mapping sends, and what it never does.