Model Data
Joins & fan-out
Joining a parent table to a related table with multiple matching rows (a 1:N or N:M relationship)
multiplies parent rows across each matching child. While standard relational behavior for detail queries,
this quietly invalidates aggregates: summing an order’s total_amount after joining to its line items counts the
order’s total once per item instead of once per order.
This is called a join fan-out, and it is one of the most common causes of silent data corruption in business intelligence. DataSquares automatically detects and rewrites queries to eliminate fan-out double-counting across parent and child measures, and refuses queries loudly with specific corrective guidance rather than producing incorrect numbers when a shape cannot be auto-corrected.
Define a relationship
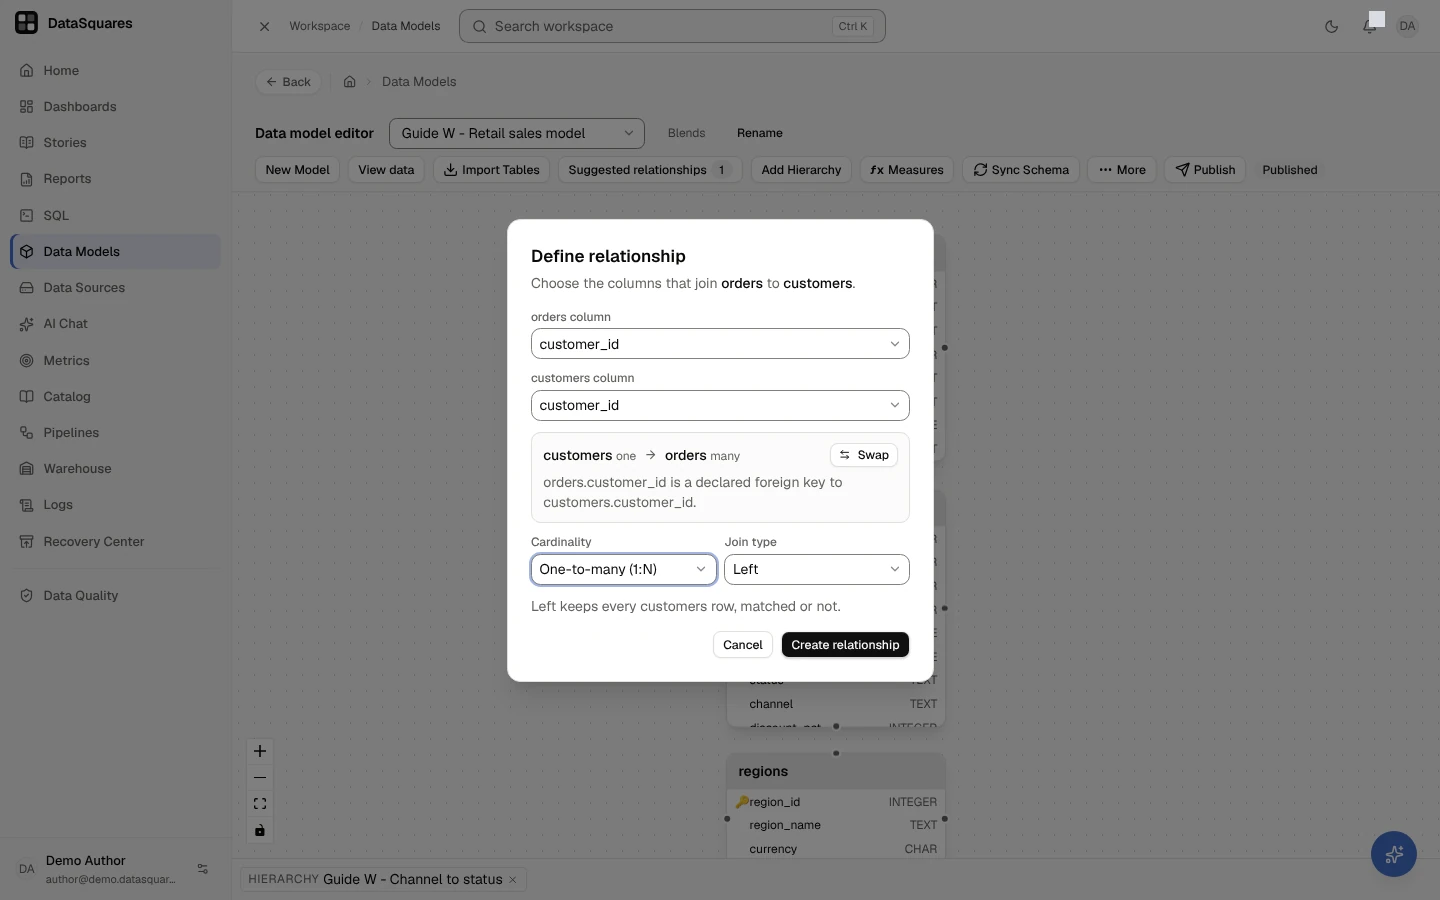
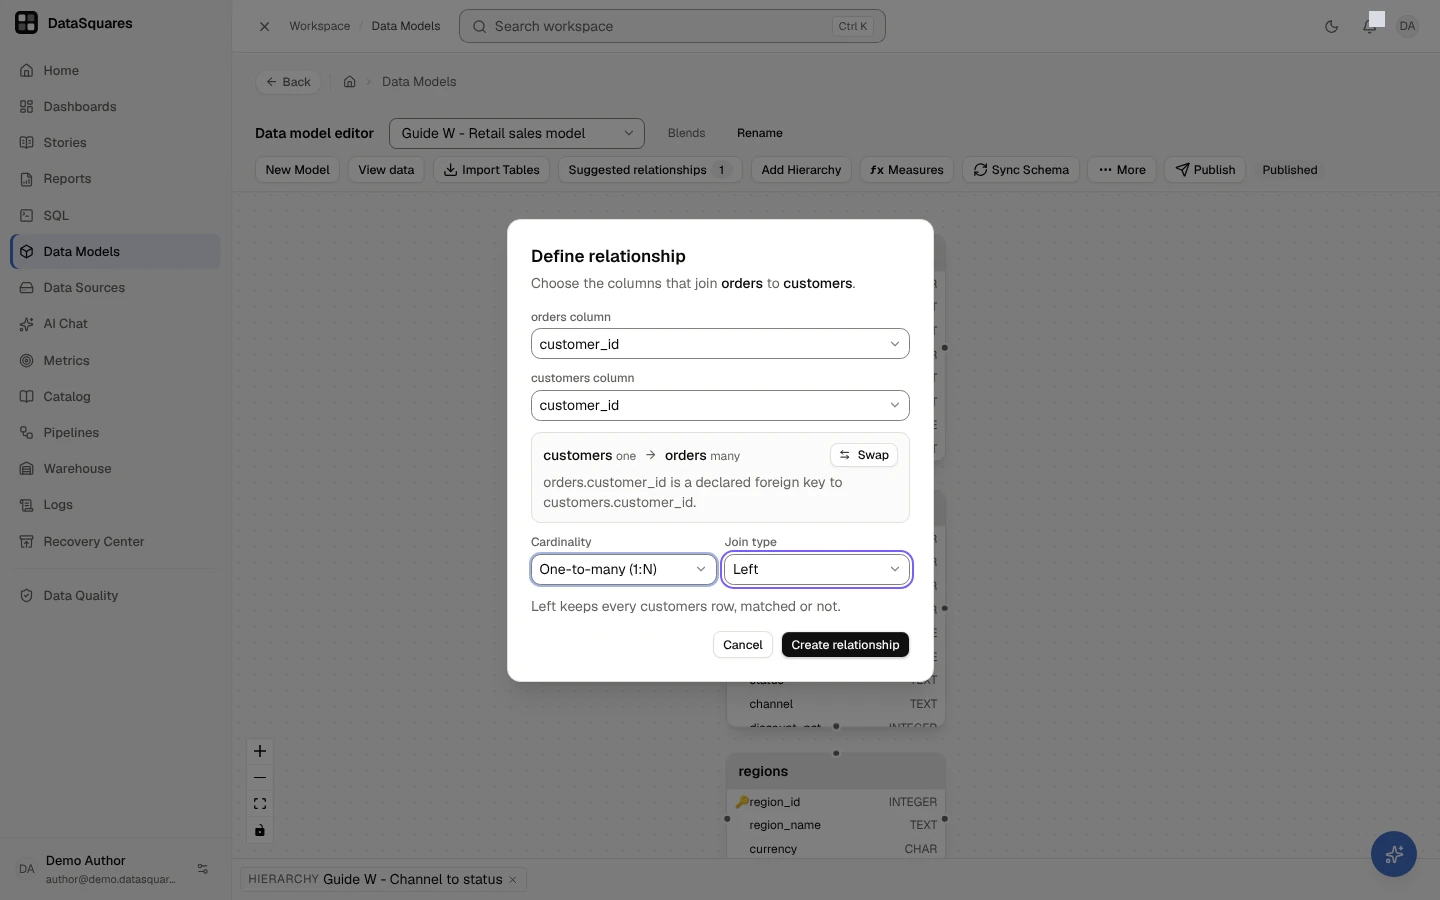
Section titled “Define a relationship”Drag between two tables and choose the matching columns, cardinality and join type. The dialog starts on Left; a relationship created through the API without a join type is Inner. The join type can’t be changed on the canvas afterwards (see Defining relationships).
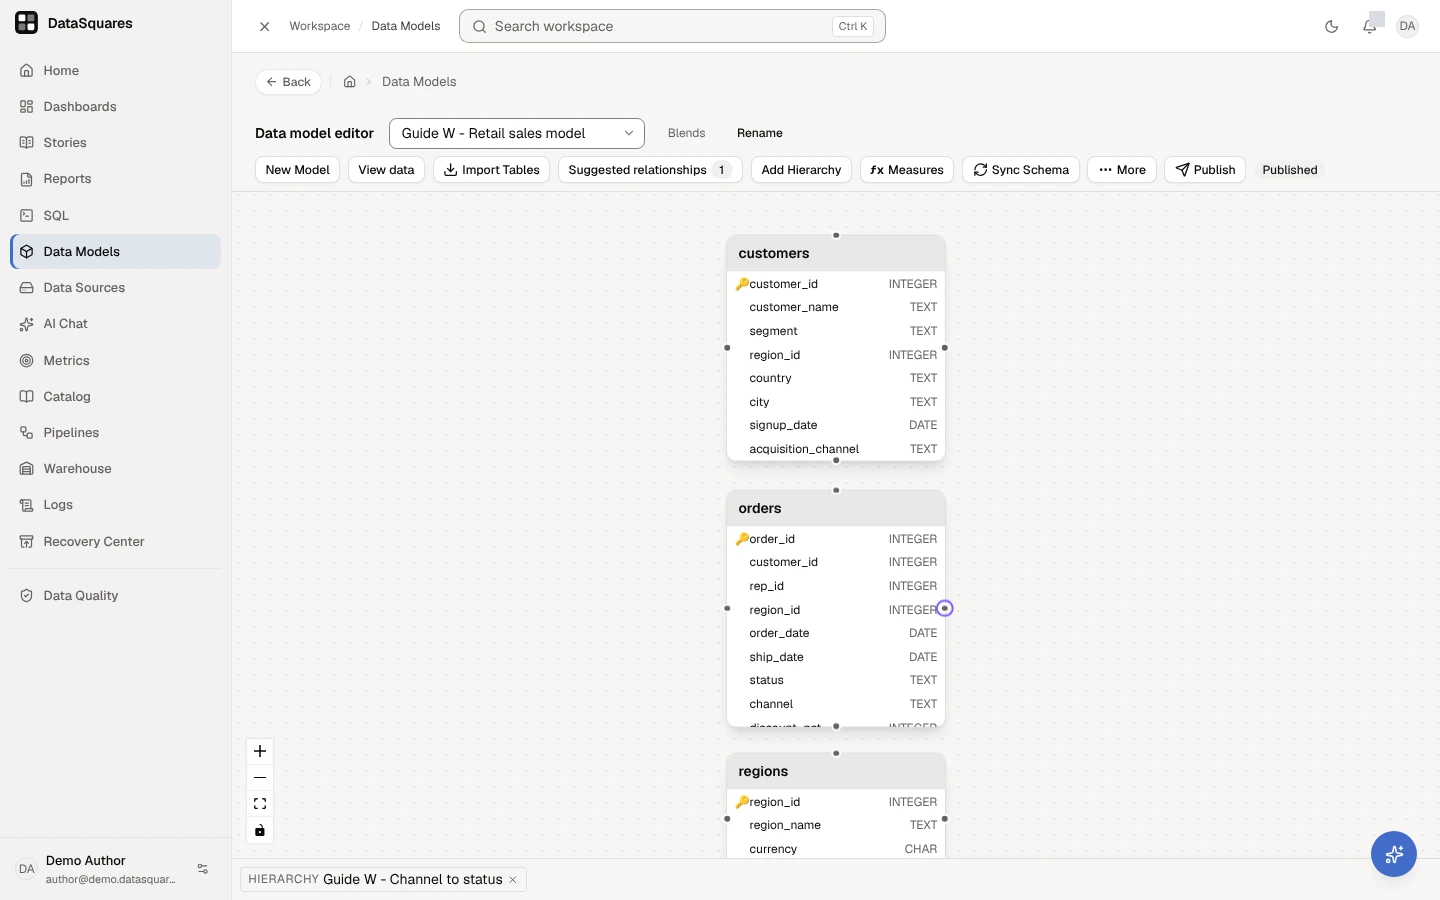
Open a model that has more than one table. To relate two of them, drag one table's name onto the other.
A dialog asks which column on each side holds the match. Here orders.customer_id points at customers.customer_id.
Set the cardinality (how many rows on each side can match) and the join type: inner keeps only matching rows, left keeps every row of the first table, full keeps everything.
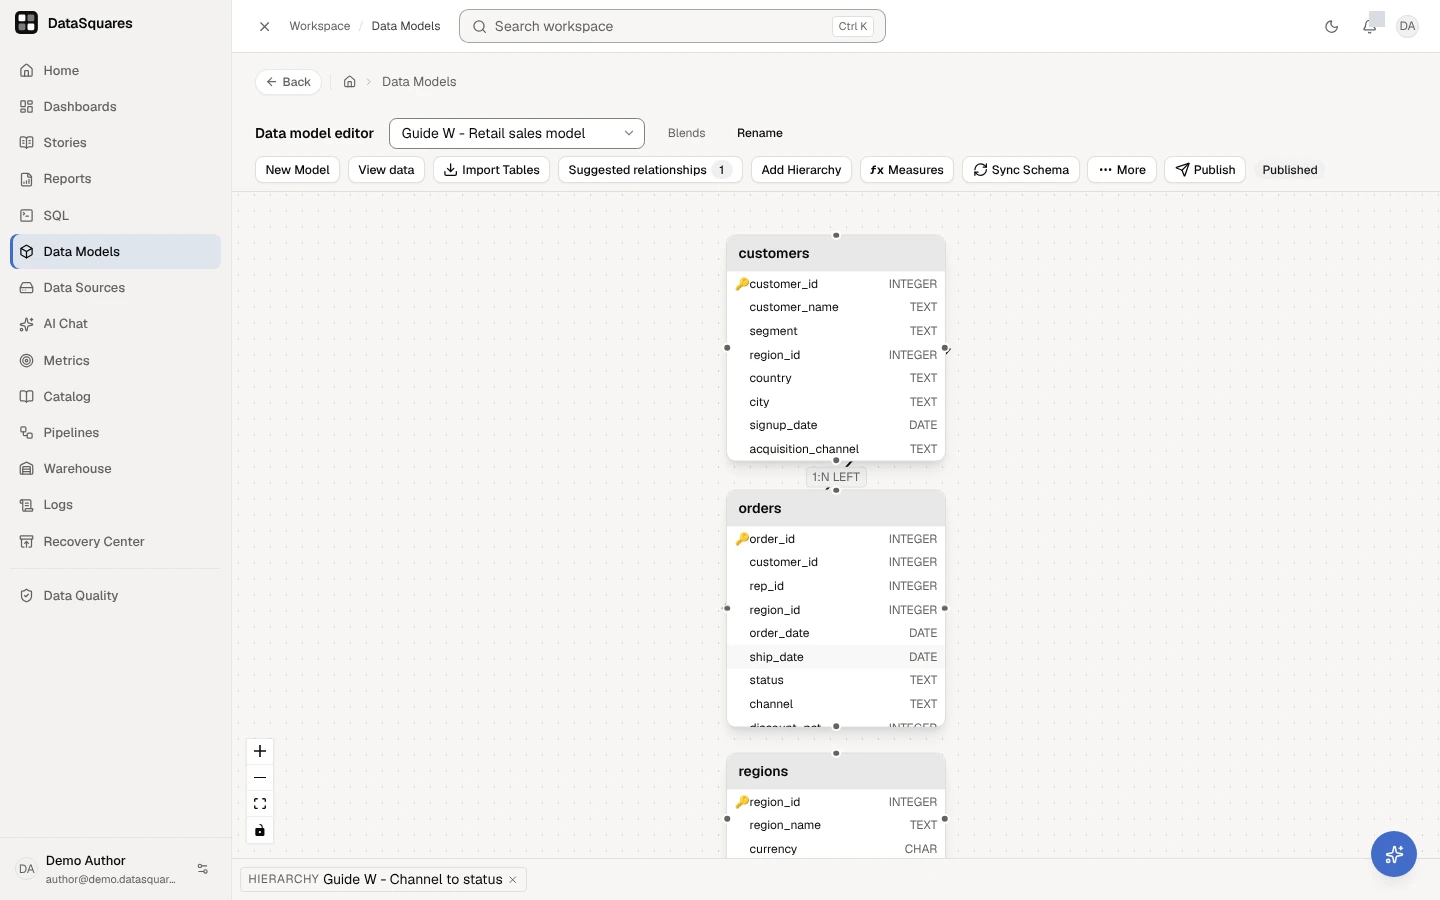
The join line now connects the two tables. Dashboards built on this model can combine columns from both.
What a fan-out looks like
Section titled “What a fan-out looks like”Consider an orders table (one row per order) and an order_items table (multiple rows per order):
orders (id, total) |
order_items (order_id, qty) |
||
|---|---|---|---|
| 1 | $100 | 1 | 2 |
| 1 | 3 | ||
| 2 | $50 | 2 | 1 |
Joining these tables produces three rows in the result set:
- Order 1 is duplicated because it contains two items.
- Naive evaluation of
SUM(orders.total)returns $250 ($100 + $100 + $50), instead of the true total of $150. - Naive evaluation of
AVG(orders.total)orCOUNT(orders.id)is similarly distorted.
Which joins a chart makes
Section titled “Which joins a chart makes”A chart joins exactly the tables it reads — the tables of its dimensions, filters and measures — along the
shortest path between them, preferring tables it already joins. A revenue-by-region chart joins regions and
orders, and nothing else from the model, even when regions also relates to targets or web_sessions.
A region filter on a product chart reaches regions through order_items and orders, the tables that
relate them.
Lookups are not fan-outs
Section titled “Lookups are not fan-outs”A fan-out only distorts an aggregate over the table whose rows it repeats. In revenue by region, each order meets
exactly one region: the regions are repeated, the orders are not, so SUM(orders.order_total) grouped by
regions.region_name is exact over the plain join. The same holds for any dimension or filter above the
measured table — a region filter on an orders-by-month chart, a customer segment on an orders-by-channel chart, a
category on a units-by-product chart. These charts run as written, with no rewrite.
A distortion needs the measured table to sit on the one side of a join that a chart travels toward the many
side — orders.total summed with order_items joined in. MIN, MAX and COUNT DISTINCT are never
distorted: a repeated row cannot change them.
A lookup never adds rows
Section titled “A lookup never adds rows”The table on the one side of a relationship is a lookup of the table on its many side: an order’s customer, a customer’s region. When a chart measures the orders, a lookup only labels and filters them — it never adds a row of its own. Say regions have customers and customers have orders. An orders-by-channel chart filtered to Europe reaches the region through each order’s customer, and the customers who have not ordered yet stay out of it: no blank channel for them, and a count of orders doesn’t count them.
The join from the orders to a lookup is therefore a left join, whichever side you declared the relationship to
keep (Left, Right or Full). Three cases are different:
- Declared
Inner. It still filters, as you asked: an order with no matching customer is left out. - One-to-one. A one-to-one relationship keeps the side you declared.
- A chart that measures only the lookup, such as distinct customers by order channel. It keeps the side you declared too, so the customers who have ordered nothing still count, under a blank channel. Measure the orders beside them and it is back to the customers who have ordered.
A chart by the lookup lists every member of it. Revenue by region starts from the regions, so with
Left (the Define relationship dialog’s default) a region that has no orders is a row with an empty revenue, and a count of orders reads 0; declared Inner,
the relationship keeps only the regions that have orders. A calendar table works the same way: if it runs past your
data, those months are listed, empty. Filter the calendar to the range you want.
Measures over their own tables
Section titled “Measures over their own tables”A SquareX measure is computed over the tables it reads. Each aggregate in it that the chart’s joins
would repeat moves into a CTE of its own: its table, plus the tables of the chart’s dimensions and filters, joined
back once per group. Revenue charted beside its target, by region — or Divide([Revenue], [Revenue target]) —
reads orders and targets separately, so neither is counted once per row of the other. A Calculate is
computed the same way, over its own tables, never over another measure’s.
With a shared date table that both facts reference (a calendar above orders.order_date and
targets.month_start), revenue against target by month works the same way, each fact filtered through its own
path to the dimensions.
A filter on another fact. A chart filter limits a measure where it says something about the rows the measure
adds up: a column of the measure’s own table, or of a table it looks up. Show each region’s revenue and target,
filtered to the Web channel. The channel is a column of an order, so the revenue is Web revenue; it says nothing
about a target, so the target is whole. The filter still decides which regions the chart lists — those with Web
orders. A condition written inside a measure is never set aside this way: a target measure whose own Calculate
filters on orders.channel is refused, because applying it would repeat each target once per order.
Plain fields, side by side. Plain fields are answered the same way when the correction below can’t take them. Sum of order total beside Sum of revenue target, by month and filtered to Europe — a filter on a dimension neither fact is grouped by — computes each sum over its own tables, each reaching Europe through its own relationship, and joins the two on the month. A chart the correction can already answer keeps the plan it had.
Some shapes stay refused: a filter or a grouping on a table below the measured one (the orders that have a line
for one product), and a measure’s own condition on another fact. A plain-field chart over a relationship declared
Inner keeps the refusal it had when a sum computed on its own would skip that join, because the sum would then keep
rows the inner join drops. When a chart is refused has the messages and
what to do.
How DataSquares corrects fan-out
Section titled “How DataSquares corrects fan-out”When a chart or query combines measures and dimensions across 1:N relationships, the DataSquares query planner
identifies the fan-out and computes each measure at its authentic grain, joining results back cleanly.
This protection is universal across canvas dashboard cards, the visual query builder, SquareX measures, and exports.
The query engine dynamically chooses between two automated rewrite mechanisms:
1. Foreign-key pre-aggregation (__fanout_<alias>)
Section titled “1. Foreign-key pre-aggregation (__fanout_<alias>)”For composable aggregations (SUM, COUNT, MIN, MAX, AVG), the child table is collapsed into a Common Table Expression (CTE)
grouped by its foreign key before joining back to the parent:
- Child WHERE pushdown: Filters applying exclusively to child tables are pushed directly inside the pre-aggregation CTE.
- Exact AVG decomposition:
AVG(x)is decomposed intoSUM(x) / NULLIF(COUNT(x), 0)within the CTE so parent weighting remains mathematically exact rather than averaging averages. - Join type preservation: An
INNER JOINagainst the child table joins against the pre-aggregation CTE withINNER JOIN, correctly preserving parent filtering for parents with active children. ALEFTjoin whose child filters move into the CTE becomes anINNERjoin, since a filter on the child keeps only the parents that have matching children.
2. Grain-keyed measure CTEs (__mgrain_<alias>)
Section titled “2. Grain-keyed measure CTEs (__mgrain_<alias>)”Non-composable measures (COUNT DISTINCT, MEDIAN, STDEV, VAR) cannot be reconstructed from foreign-key partials.
For these operations:
- Each measure is evaluated in a dedicated CTE at the report’s exact grouping grain.
- The join path is traversed independently for that measure and joined back to the primary grain using null-safe equality written the same way for every database:
(a = b OR (a IS NULL AND b IS NULL)), so a group whose key is empty still meets its measure. - Row-Level Security (RLS) policies and table transforms compose across all generated measure CTEs.
Multi-hop join paths
Section titled “Multi-hop join paths”When queries traverse across multiple table hops (e.g. Customers → Orders → Order_Items), the planner walks the full
relationship graph. Multi-hop parent and child measures are each calculated at their respective true grains without compounding duplication.
Cross-source Blends and aggregation push-down
Section titled “Cross-source Blends and aggregation push-down”A blend (Blends, /blends) pulls each side through its own governed query and joins them in an isolated
in-memory engine. The left side runs first; its join-key values then narrow the right side (a semi-join) when there
are few enough of them (up to 1,000 different keys).
Walkthrough: blend a database with an uploaded file
Section titled “Walkthrough: blend a database with an uploaded file”The steps join the retail orders of a database source to a regional quota file on region_id, then run the blend grouped by region.
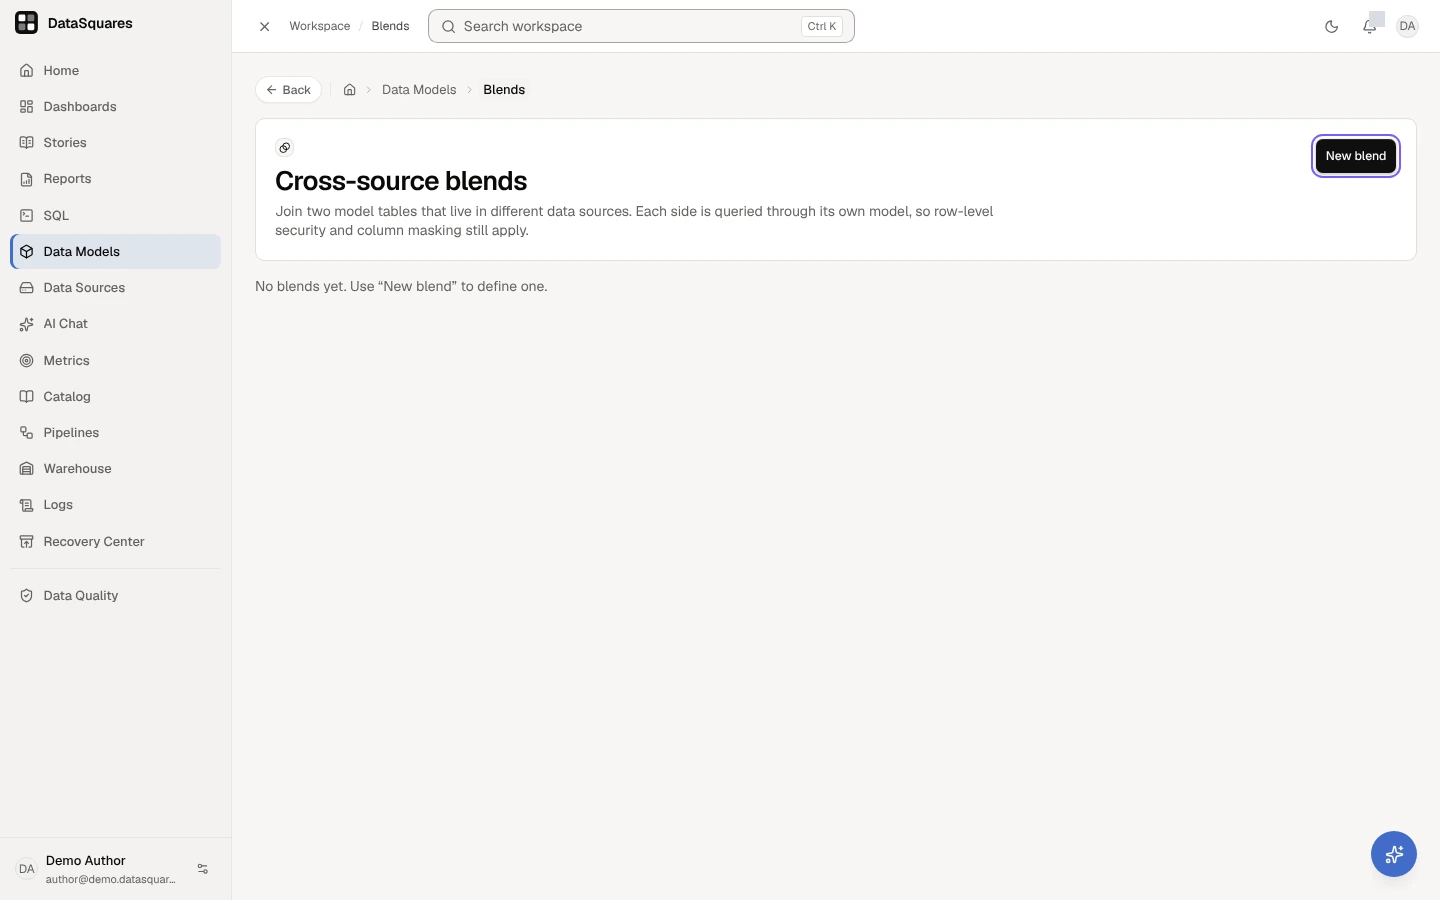
Open Blends from the Data Models toolbar. A blend joins two model tables, even when they live in different data sources. Choose New blend.
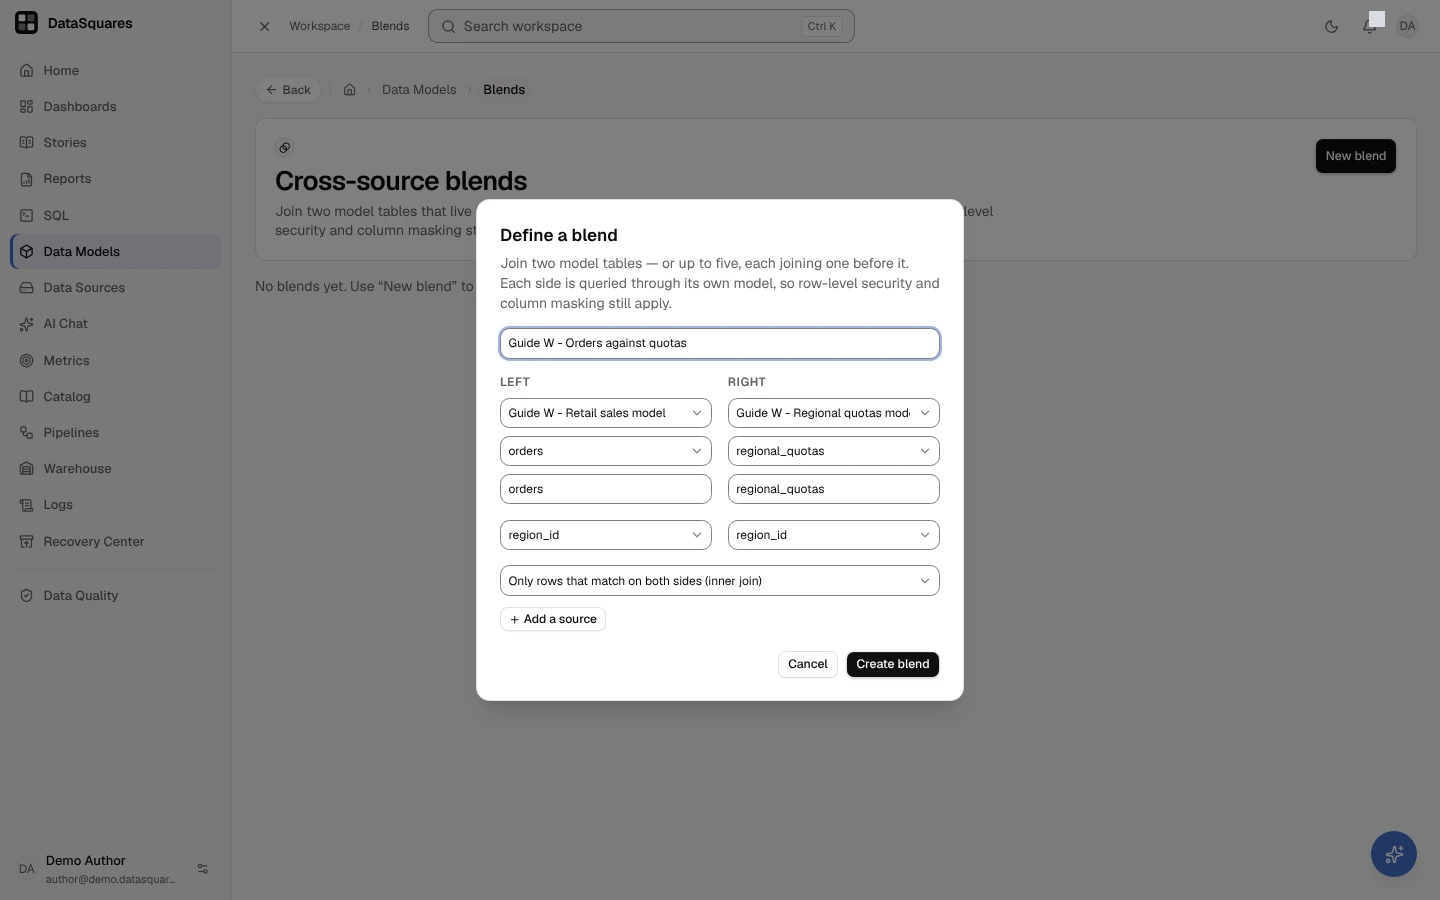
Name the blend, then pick the model and table on each side and the join key on each. Here the retail orders (a database) join a regional quota file (an upload) on region_id. Rows to keep says whether unmatched rows stay; the default keeps only rows that match on both sides.
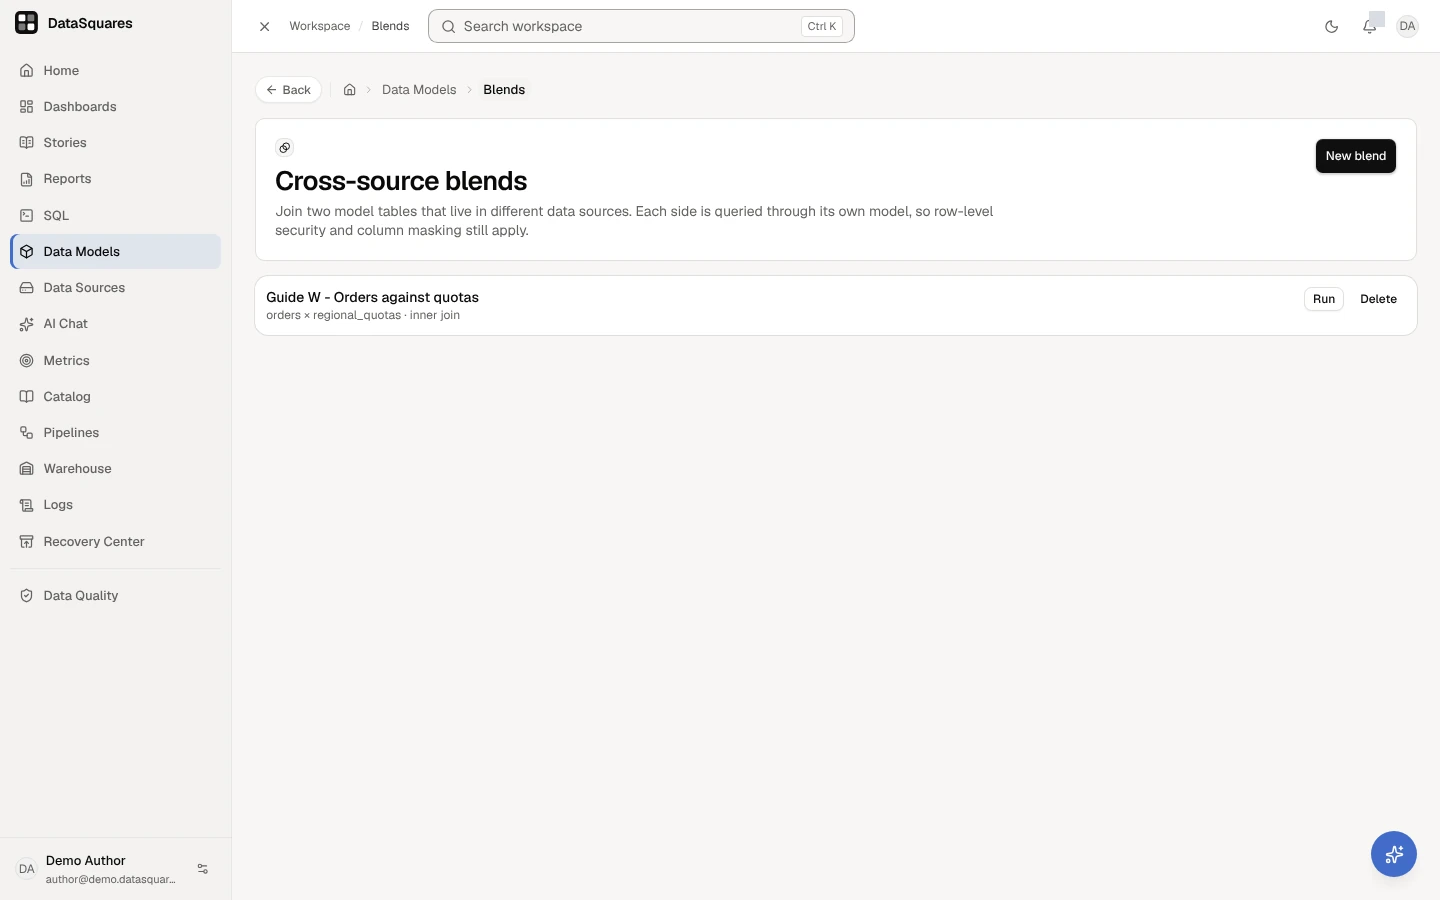
The blend appears in the list with the two tables it joins. Each side is still read through its own model, so row-level security and masking apply.
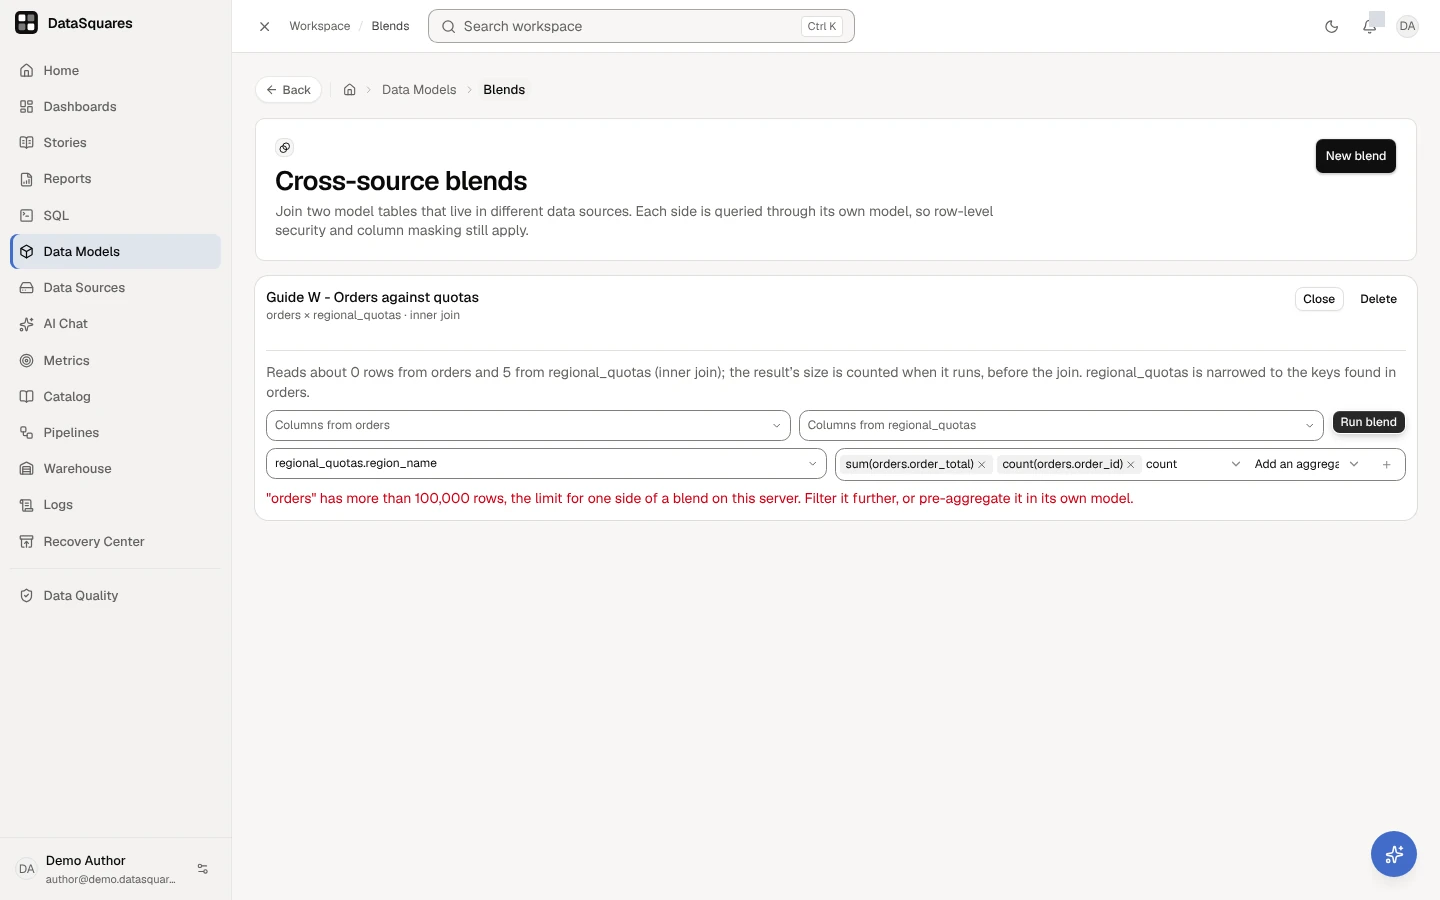
Choose Run, then tick the Group by columns in its list and add each aggregate (its function and field, then Add aggregate), and choose Run blend. Each side is read first: a side larger than the server’s limit for one side of a blend (100,000 rows unless an admin changes it) is refused before the join, with what to do instead.
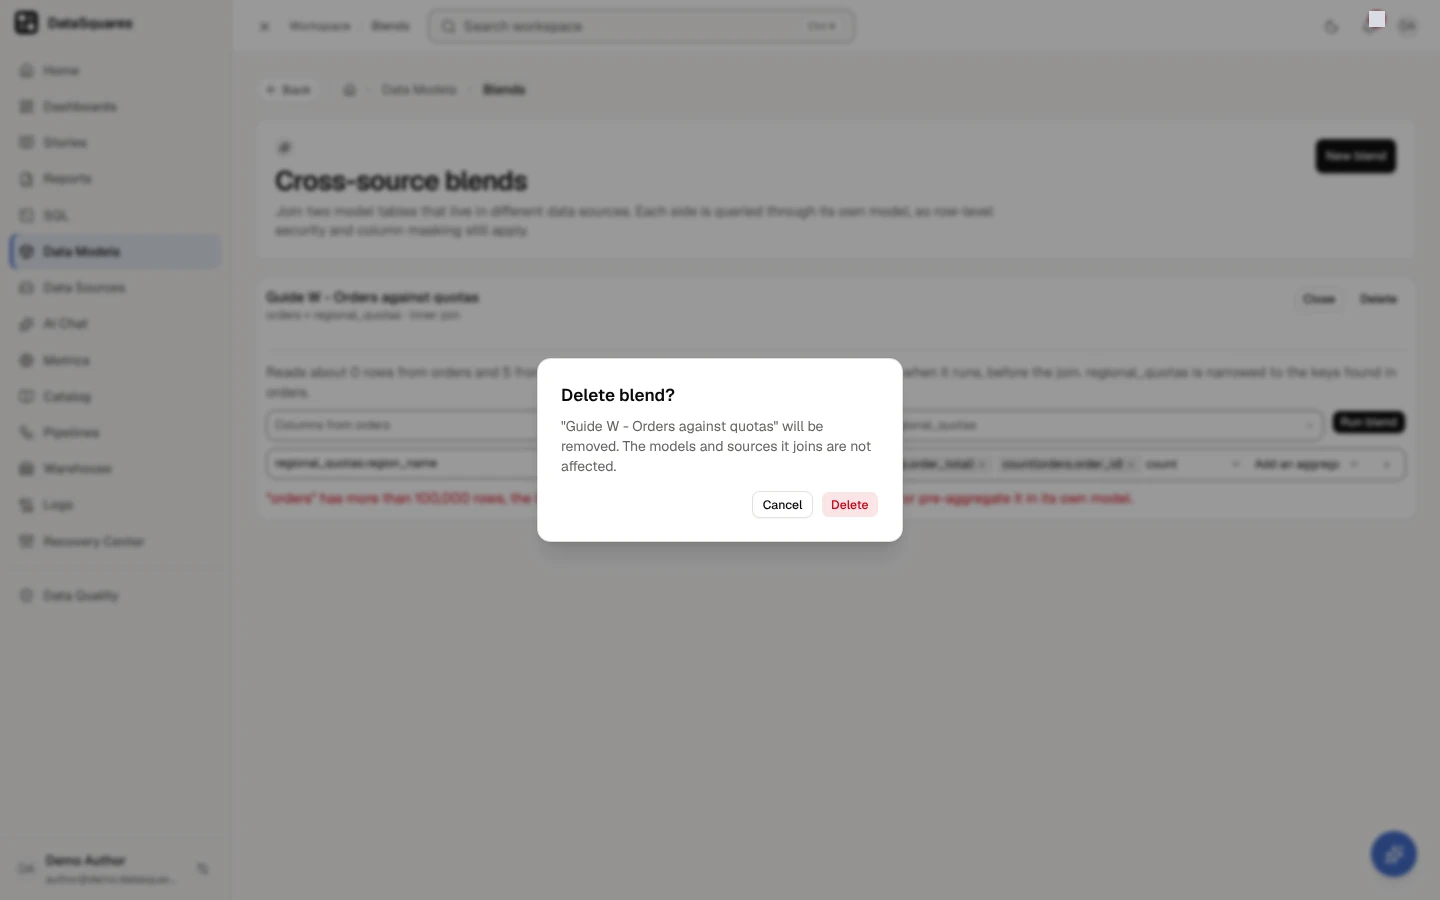
Delete asks Delete blend? before it removes the definition. The two models and their data are not touched.
When you define a blend, Rows to keep sets the join:
| Rows to keep | Join | Result |
|---|---|---|
| Only rows that match on both sides | inner (default) | matched rows only |
| Every left row, matched or not | left | every left row; the right columns are empty where nothing matched |
| Every row of both sides | full | every row of both; the right side is always read whole |
A join key that is empty (NULL) never matches anything, so its row appears only in a left or full join, unmatched. The sides can live in different database engines — a PostgreSQL source blended with a Warehouse dataset in ClickHouse, for example.
Join keys and sensitivity labels. Which rows match is itself information, so for anyone a
sensitivity label masks, a blend refuses a join key that is labelled,
and one whose data reads a labelled column: a calculated field over it (lower(email)), a second field over it, a
column computed from it, or a column that another model of the source, or a Warehouse copy of its table, labels. It is
refused when the blend is defined or edited, on any of its sides, and again at each run, a column labelled since the
blend was made included, naming what the key reads before either side is read:
“Email lower” reads the field “Customer email”, labeled PII, and cannot be a blend’s join key: matching on it would reveal its values through which rows come back. Join on an unlabeled key, or ask a workspace admin.
A company admin may define a blend on such a key; a member’s run of it is then refused the same way.
How big a blend may be. Each side may return up to 100,000 rows on DataSquares Cloud (a self-hosted install can
raise this with QUERY_MAX_ROW_LIMIT, to at most 1,000,000), and both together up to 2,000,000. The tables’ row
estimates are checked before anything is read, and a side that turns out larger than its limit is refused with its
name and the limit, never cut short. The joined result may have up to 2,000,000 rows.
Because it is rarely known in advance whether a join key repeats, the result is counted exactly once both sides
have loaded and before the join runs; a blend over the limit is refused with its real size, never cut short.
Before you run it, the open blend says what it will read — each side’s estimated rows, and the most rows the
result can have or that its size is counted when it runs — and warns when the right side will be read whole:
always for a full join, and probably when the left side may have more than 1,000 keys. If the estimates already
exceed a limit, it shows the refusal the run would give. The same preview is GET /api/composite-models/{id}/plan. After a run, What ran where lists the join,
the rows pulled from each side, whether the right side was narrowed to the left’s keys (or why not), and where the
aggregation ran.
An aggregated blend (groupBy + aggregates on POST /api/composite-models/{id}/execute) is grouped over the joined
rows. The right side is pre-aggregated in its own database only when that cannot change a total:
- every aggregate and group key is on the right side, and the group keys include the right join key;
- the left side’s join key is unique in the rows it returned (otherwise each right row would be counted once per matching left row — the fan trap);
- the semi-join narrowed the right side, so every right row has a match (otherwise unmatched rows would be counted);
- the join key is a single column of a number, date/time or boolean type, and MIN, MAX and COUNT DISTINCT are not over text — a source’s case-insensitive collation could merge values the blend engine keeps apart;
- no group field carries a default aggregation in the model;
- the blend is an inner join — in a left or full join a group with no right row must count 0, which a pre-aggregated right side cannot give.
Before joining, both premises are checked again over the loaded rows; if either fails, the right side is pulled raw
and grouped in the blend engine instead. The response’s plan reports what happened — plan.aggregation.pushed,
or the reason naming the condition that refused it — along with the semi-join outcome and rowsPulled per side.
Pass pushdown: false to run without it, for example to compare totals. On the Blends page, open a
blend’s Run panel: tick the Group by columns in its searchable list of each side’s fields (orders.customer_id),
and add each aggregate by choosing its function (sum, avg, count, min, max or count distinct) and its field,
then the + (Add aggregate) — it shows as sum(orders.total); Columns from each side picks the columns to
show when nothing is grouped. Then Run blend. What ran where says whether the aggregation was
pushed down and, if not, why. The left side is never pre-aggregated.
Blends of more than two sources
Section titled “Blends of more than two sources”A blend can join up to five sources. In the blend dialog, Add a source (up to three more): pick its table, the
earlier source it joins, a key of that source and one of its own, and the rows to keep. Every further source
joins exactly one source before it, with its own join type. Through the API, the same is extraSides on
POST /api/composite-models — each { tableId, alias, joinsTo, joinType, keys }, where joinsTo is the earlier
source’s alias and each key pairs a field of that source (leftFieldId) with one of this source (rightFieldId).
The blend is built one join at a time. Each source is still pulled through its own governed query, narrowed to the keys of the source it joins (except under a full join, which must keep the rows that match nothing). Before each join is built, its exact size is counted; if it would pass the 2,000,000-row limit, the blend is refused with that join’s real size. Input limits are the same as for two sources: each source up to the per-side limit above, 2,000,000 in total.
To run one, name the first two sources’ columns as before (leftColumns, rightColumns) and the others by alias in
sideColumns ({ "products": ["title"] }) — and their filters in sideFilters. Group keys and aggregates name any
source by its alias (products.title, sum(orders.total)). The result is always grouped after the last join;
nothing is pre-aggregated in a source. GET /api/composite-models/{id}/plan lists every join and whether its
source will be narrowed; after a run, What ran where and plan.steps give, per join, the rows pulled, whether
they were narrowed and the rows the join produced.
When a chart is refused (Fail-loud design)
Section titled “When a chart is refused (Fail-loud design)”If a query contains ambiguous graph topology or incompatible dimensional slicing, DataSquares refuses the query with a descriptive error explaining the exact constraint and how to fix it:
This chart hits a join fan-out that would double-count a measure and can’t be auto-corrected yet (reason). What to do instead.
Refusal reasons & solutions
Section titled “Refusal reasons & solutions”| Refusal message | Root cause | How to resolve |
|---|---|---|
| the grouping spans two tables — A and B | Grouping by columns from both parent and child makes the output grain finer than the parent table, duplicating parent rows per child group | Group by columns from a single table, or separate the secondary grouping column into its own focused chart |
| the relationship between A and B is many-to-many | Both sides multiply across the relationship, creating ambiguity between entity totals and association totals | Explicitly model the bridge table as two 1:N relationships in the Data Model, allowing the engine to pre-aggregate each side independently |
| “A” is reachable by more than one join path (from “B”) | Two paths lead from B to A, each from a relationship’s one side to its many side — regions → orders directly and regions → customers → orders — so the region of an order is two different things. (Two dimensions over the same facts, such as a region and a calendar over orders and targets, are not ambiguous.) |
Remove or re-point one of the relationships into A in the Data Model, or switch one off: open it on the canvas and turn Active off (how; isActive: false on PUT /api/models/{id}/relationships/{relId}) |
| the measure “M” adds up rows of “A” that this chart’s grouping or filters repeat | The chart groups or filters by a table below A — order revenue by product, where each order has several lines — or the measure carries its own condition on a table beside A, such as a target measure that filters on orders.channel. (A chart filter on another fact is fine: it just isn’t applied to A’s measure.) |
Group and filter by columns of A or of the tables A looks up (a measure’s own conditions too), or measure the detail table instead (order_items.line_total by product) |
| “A” is not below the grouping table “B” | A plain field measure on A is charted by a table A is repeated by, or A relates to the grouping table only through another detail table | Adjust chart dimensions to group by a column at or above table A |
| the “AGG” of “field” on “A” can’t be pre-aggregated | The selected aggregate function cannot be recomposed across the foreign key on this table shape | Use standard composable aggregations (SUM, COUNT, MIN, MAX, AVG), or define a SquareX measure |
| “field” on “A” is selected without an aggregation | Unaggregated detail columns cannot survive pre-aggregation across a parent grain | Apply an aggregation to the column or add it to the chart’s group-by dimensions |
| a NULL-test filter on “A”, which is left-joined | Filtering IS NULL on a left-joined table asserts child absence that cannot be expressed inside child pre-aggregation |
Apply the filter directly on the parent table or switch to an inner join |
| the grouping key is a computed expression | The planner cannot bind an expression to a single model table to establish grain. A calculated field is an expression too, so grouping by one in such a chart is refused the same way | Group by a physical column of the grouping table instead, or split the chart into one chart per table |
| the query is based on the detail table — base the chart on the grouping (parent) table | The chart starts from the table that repeats, not the one it groups by | Base the chart on the grouping table |
| a measure is a computed expression | A measure that is an expression (such as an aggregate calculated field) can’t be pre-aggregated across the join | Measure a column with a plain aggregation, or define a SquareX measure |
| the fanned join is not a single-key equi-join, the fanned join type is not inner or left | Only a one-column equality join, inner or left, can be pre-aggregated | Model the relationship on one key column, as an inner or left join |
| a filter on a computed measure, a measure filter on “A”, which is more than one join away | The measure filter can’t be moved into the pre-aggregation | Filter on a plain measure of a table one join from the grouping table |
When a reason has no fix of its own, the message ends Split it into one chart per table, or pre-aggregate the detail table in the model. A chart whose tables no active relationship connects is refused with Cannot find join path to tables: … Add relationships to connect them.
Verifying query results
Section titled “Verifying query results”To independently verify that a metric is free of fan-out distortion:
- Open the SQL editor.
- Run a standalone query aggregating the parent table without joins:
SELECT SUM(total) FROM orders;
- Compare the standalone total with your dashboard card or visual query. When fan-out correction is active, the numbers match.
Related
Section titled “Related”- Data models & relationships — defining table relationships and cardinality settings.
- Calculated fields — adding row-level expressions to tables.
- SquareX measures — defining advanced metrics and filter context overrides.
- Visual query builder — visual joins with live CTE preview.