Connect Data
Connect your data
DataSquares connects to your data through a guided connection wizard — pick a connector below for its step-by-step setup guide.
Some connectors need something on the DataSquares server first, and their wizard tiles are enabled only once the server confirms it: IBM Db2, SAP HANA and Exasol need an additional client library installed on the server, and Salesforce, HubSpot, Stripe, Shopify, Jira and Google Analytics 4 need the server’s SaaS pipeline runner. See each connector’s guide for the setup prerequisite.
How DataSquares connects
Section titled “How DataSquares connects”The catalog holds 152 connectors, and DataSquares connects to them in these ways, tailored to different data architectures:
- Direct query databases & warehouses — Live SQL execution against relational databases (PostgreSQL, MySQL, SQL Server, Oracle), cloud warehouses (Snowflake, BigQuery, Databricks, Athena, and Fabric Warehouse in Preview), and analytics engines (ClickHouse, Trino, DuckDB). Data stays in your database.
- Object store browsing & ingestion — Connect buckets in Amazon S3, Azure Blob / ADLS Gen2, or Google Cloud Storage, or one of the S3-compatible stores (MinIO, Cloudflare R2, Backblaze B2, Wasabi and others, in Preview). Browse objects and import single files or multi-part partition prefixes (Parquet, JSON, CSV) into managed workspace datasets.
- File uploads — Upload local CSV (or TSV), Excel (
.xlsx,.xlsm), SQLite, Parquet, and JSON/NDJSON files directly into workspace staging for instant querying. - API pulls — Ingest data from REST APIs and Google Sheets with scheduled atomic refresh and HMAC-signed webhook sync triggers.
- App connectors and staged imports — App connectors (Preview) pick an app’s tables from its own API; MongoDB (Preview) imports collections through a column mapping you review; Apache Iceberg (Preview) imports tables from a catalog or table folders in your storage. Each lands in workspace staging and refreshes on a schedule.
- SaaS apps through pipelines — Salesforce, HubSpot, Stripe, Google Analytics 4, Shopify and Jira are connected in the wizard and pulled by pipelines once the server’s SaaS runner is enabled.
- Pipeline endpoints — SFTP is a file source and
destination for pipelines, and a
webhook is a destination that receives rows as signed
POSTrequests.
Most connectors require only read access — grant the connection user read-only permissions and DataSquares takes care of the rest. Credentials are encrypted at rest and never leave the server.
A source’s own page
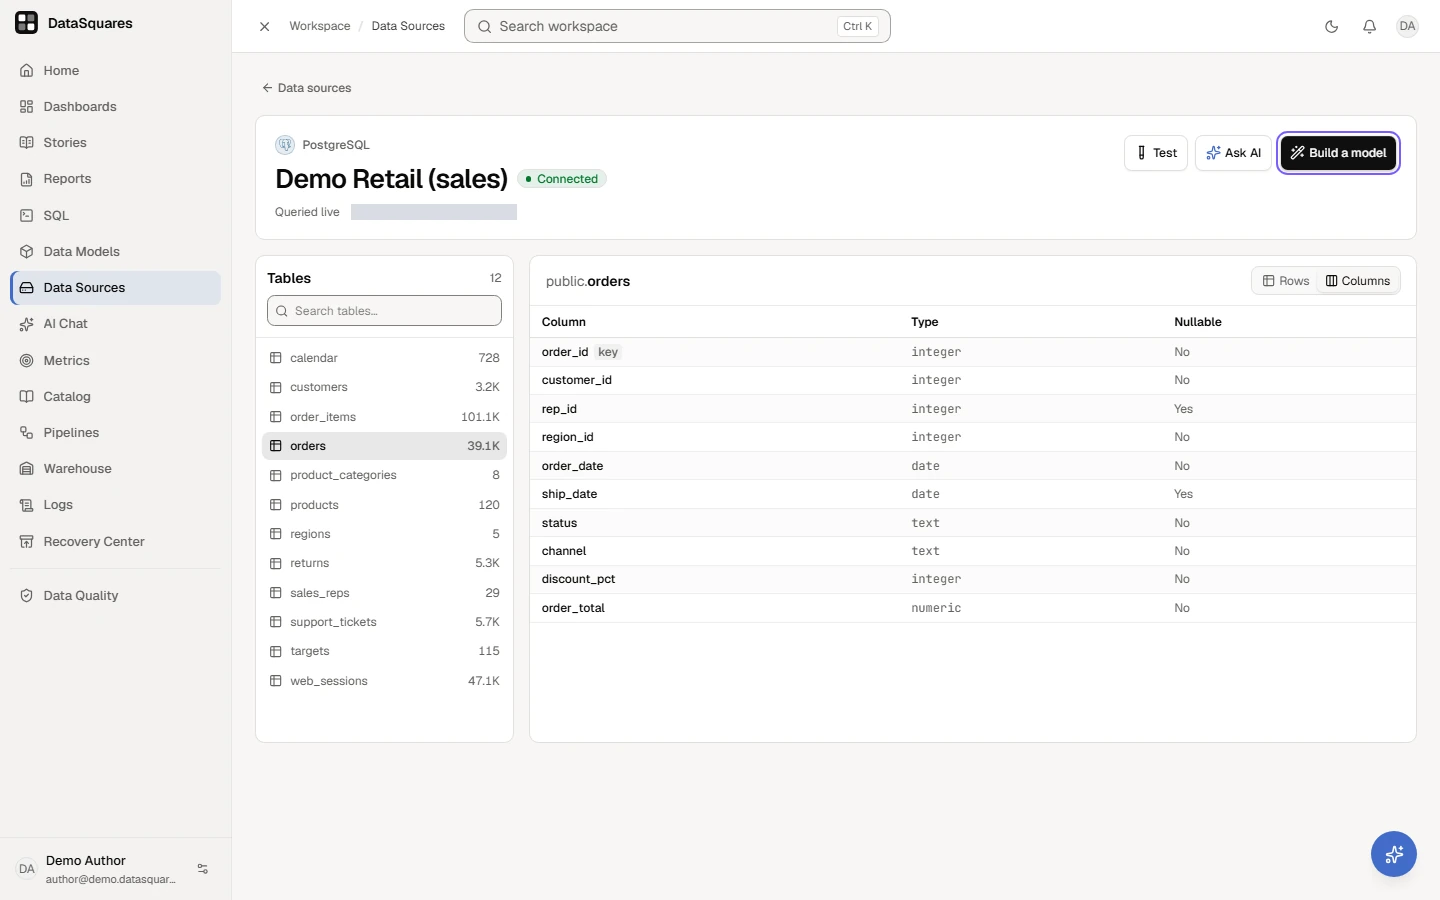
Section titled “A source’s own page”Select a source to open its page: its tables, the first 100 rows of the one you pick, and its columns. From there you can test the source, ask AI about it, or build a model from the table.
Open Data Sources and select a source. Its card opens the source's own page.
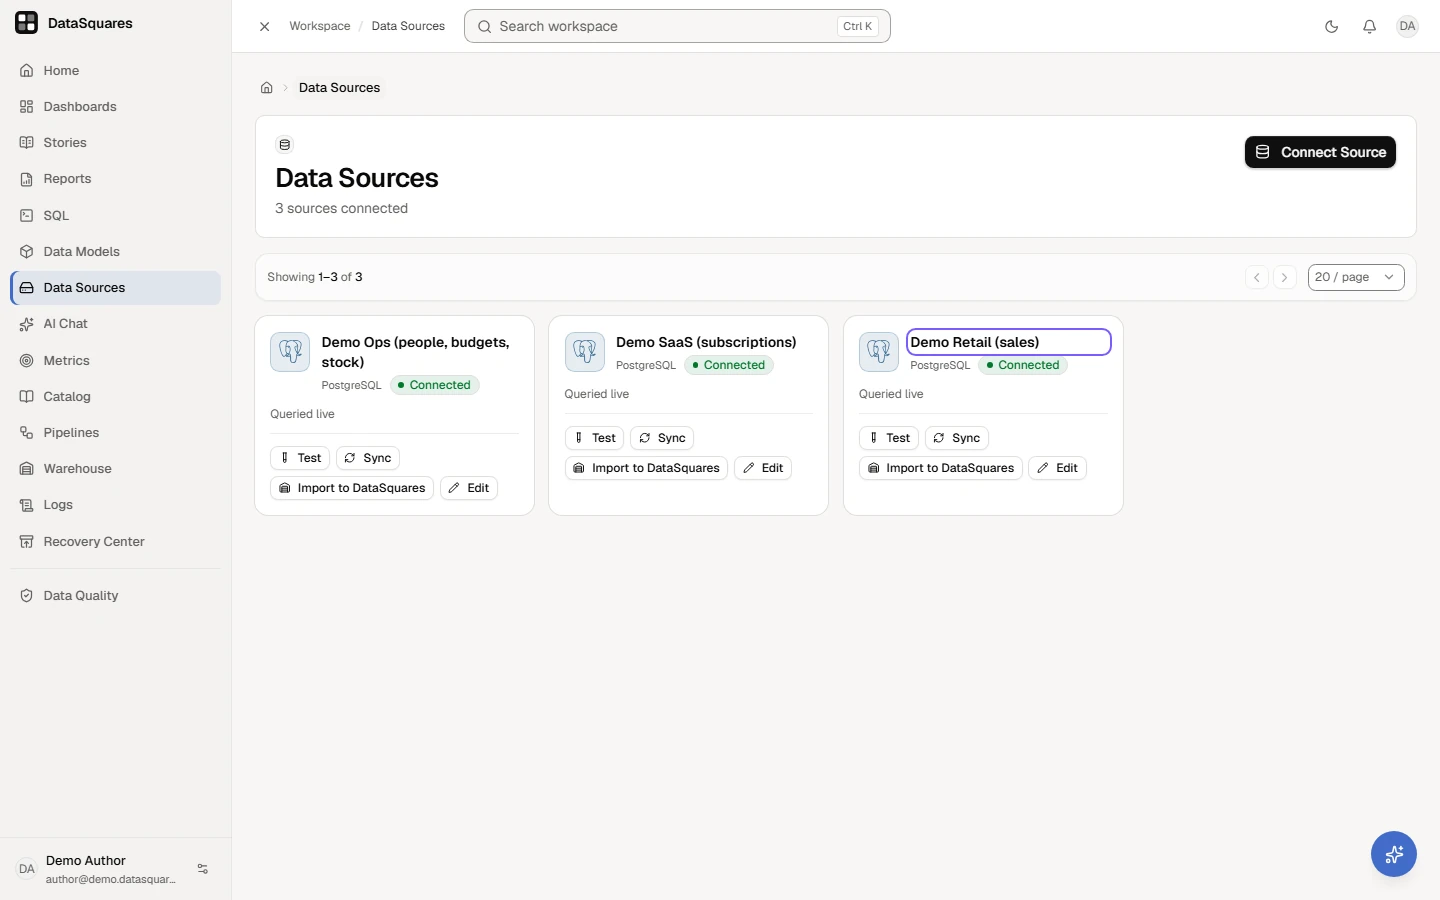
The Tables list shows every table in the source with an estimated row count. Search tables narrows it; a source with more than one schema also has a Schema picker.
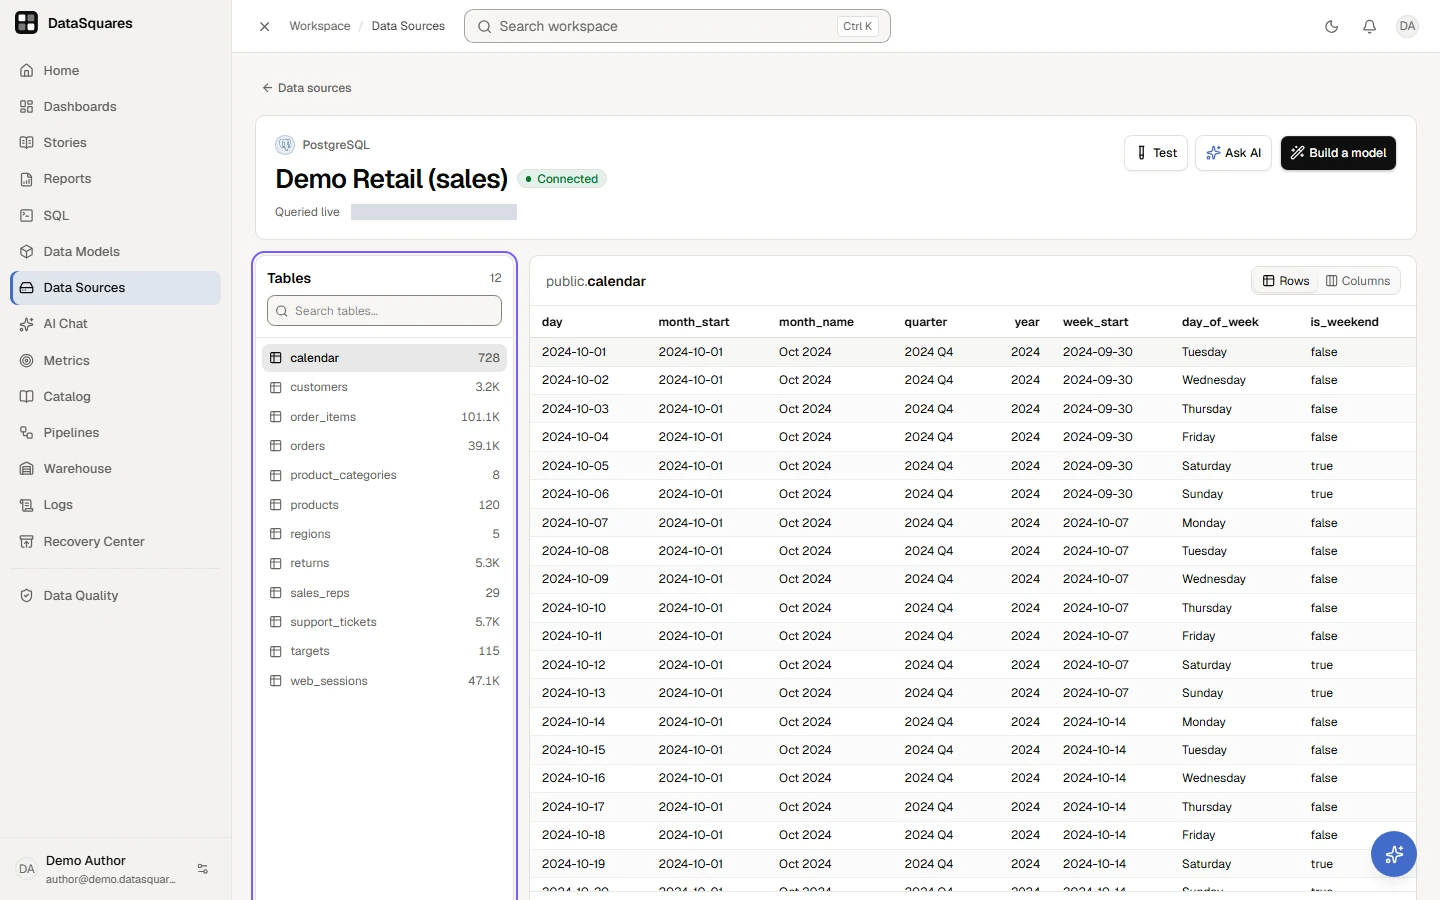
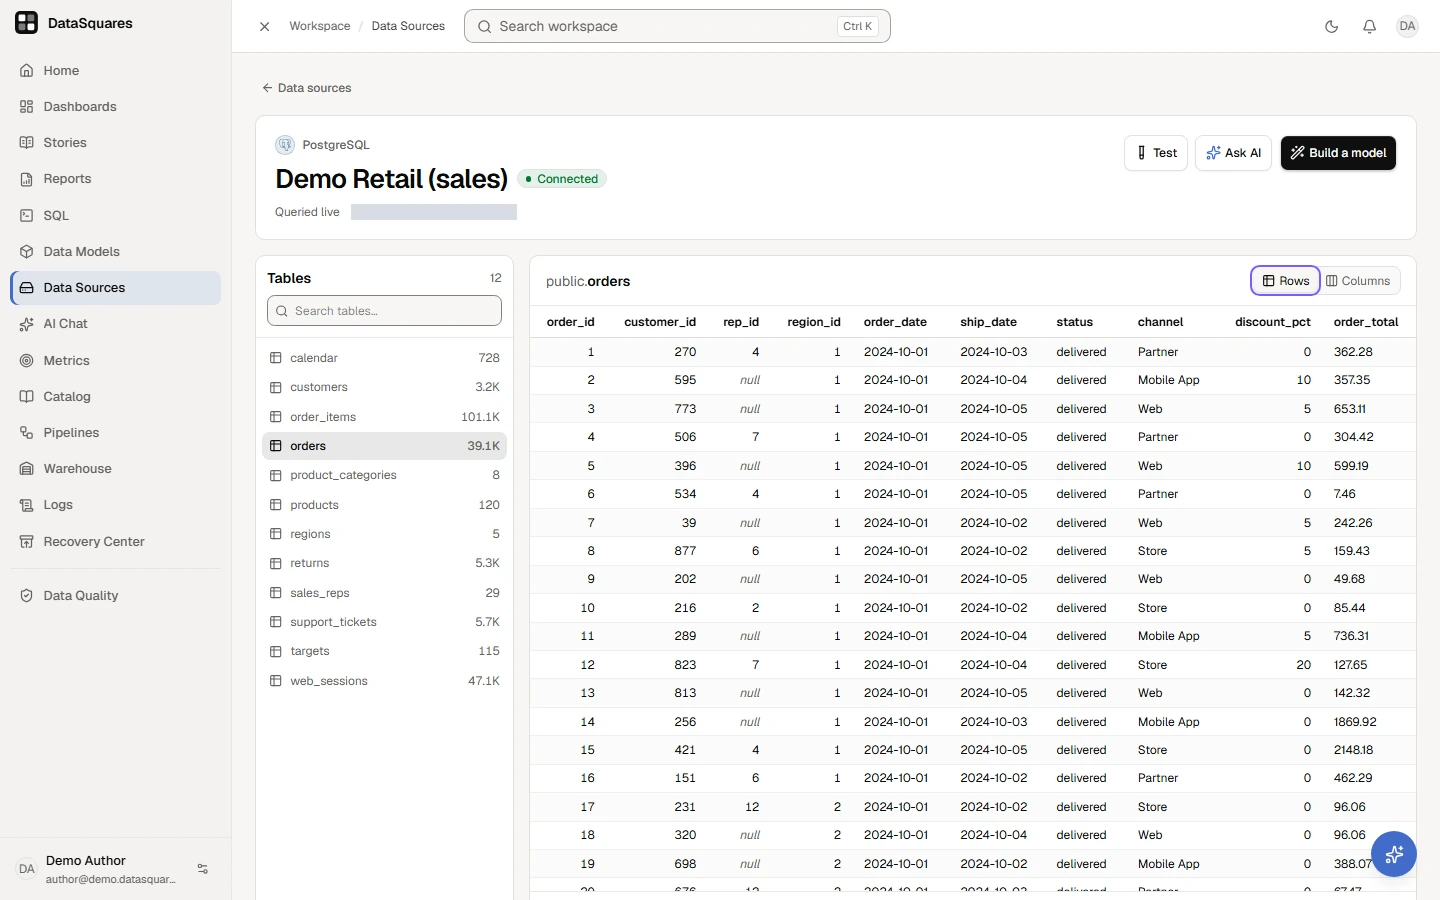
Pick a table. The Rows view shows its first 100 rows, read live from the source.
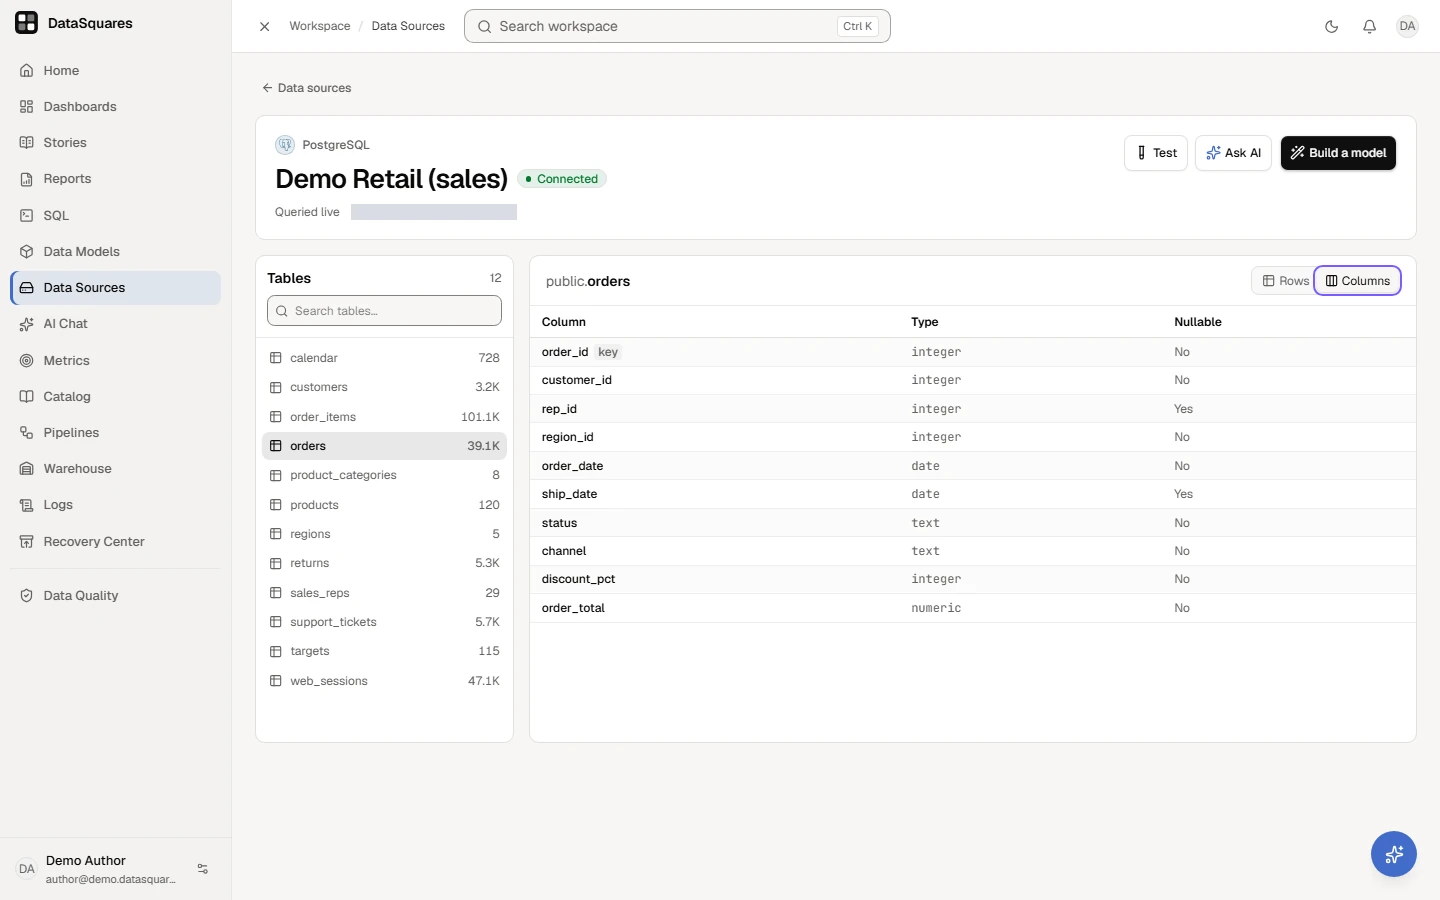
Switch to Columns to see each column with its type and whether it can be empty.
Test re-checks the connection, Ask AI opens a chat about the source, and Build a model creates a model from the table you picked.
Connector catalog
Section titled “Connector catalog”Search or filter by category to find your data source:
Databases
- PostgreSQL
- MySQL
- MariaDB
- SQL Server
- Azure SQL
- Oracle
- CockroachDB
- MongoDB
- Cassandra
- Amazon DynamoDB
- Azure Cosmos DB
- Couchbase
- Elasticsearch
- OpenSearch
- Neo4j
- InfluxDB
- TimescaleDB
- ClickHouse
- DuckDB
- SingleStore
- IBM Db2
- SAP HANA
- Exasol
- Azure Database for PostgreSQL
- Azure Database for MySQL
- Amazon RDS for PostgreSQL
- Amazon RDS for MySQL
- Google Cloud SQL (PostgreSQL)
- Google Cloud SQL (MySQL)
- Teradata
- Vertica
- Greenplum
- YugabyteDB
- TiDB
- StarRocks
- Apache Doris
- RisingWave
- QuestDB
- Apache Druid
- Apache Pinot
- Apache Drill
- Neon
- Supabase
- AlloyDB
- Materialize
- PlanetScale
- Hologres
- ParadeDB
- OceanBase
- CrateDB
- Firebird
- Redis
Data Warehouses
Cloud Storage & Lakes
Files & Apps
Business Apps
Analytics & Marketing
Developer & APIs
Streaming
Next steps
Section titled “Next steps”- Connection flows explained — Host/port forms, cloud warehouse auth, object stores, file ingestion, API pulls, app connectors, MongoDB, Iceberg and the SaaS apps.
- Refreshing data & schemas — Atomic refresh, automated schedules, run history, and schema discovery.
- Troubleshooting connections — Resolving network timeouts, TLS certificates, credentials, and permissions.