Connect Data
Connection flows explained
Every connector in the wizard uses one of a small set of connection flows — the form you fill in. Once you’ve connected one host/port database, you’ve effectively learned them all. This page explains each flow once, so the per-connector pages can stay focused on credentials and permissions.
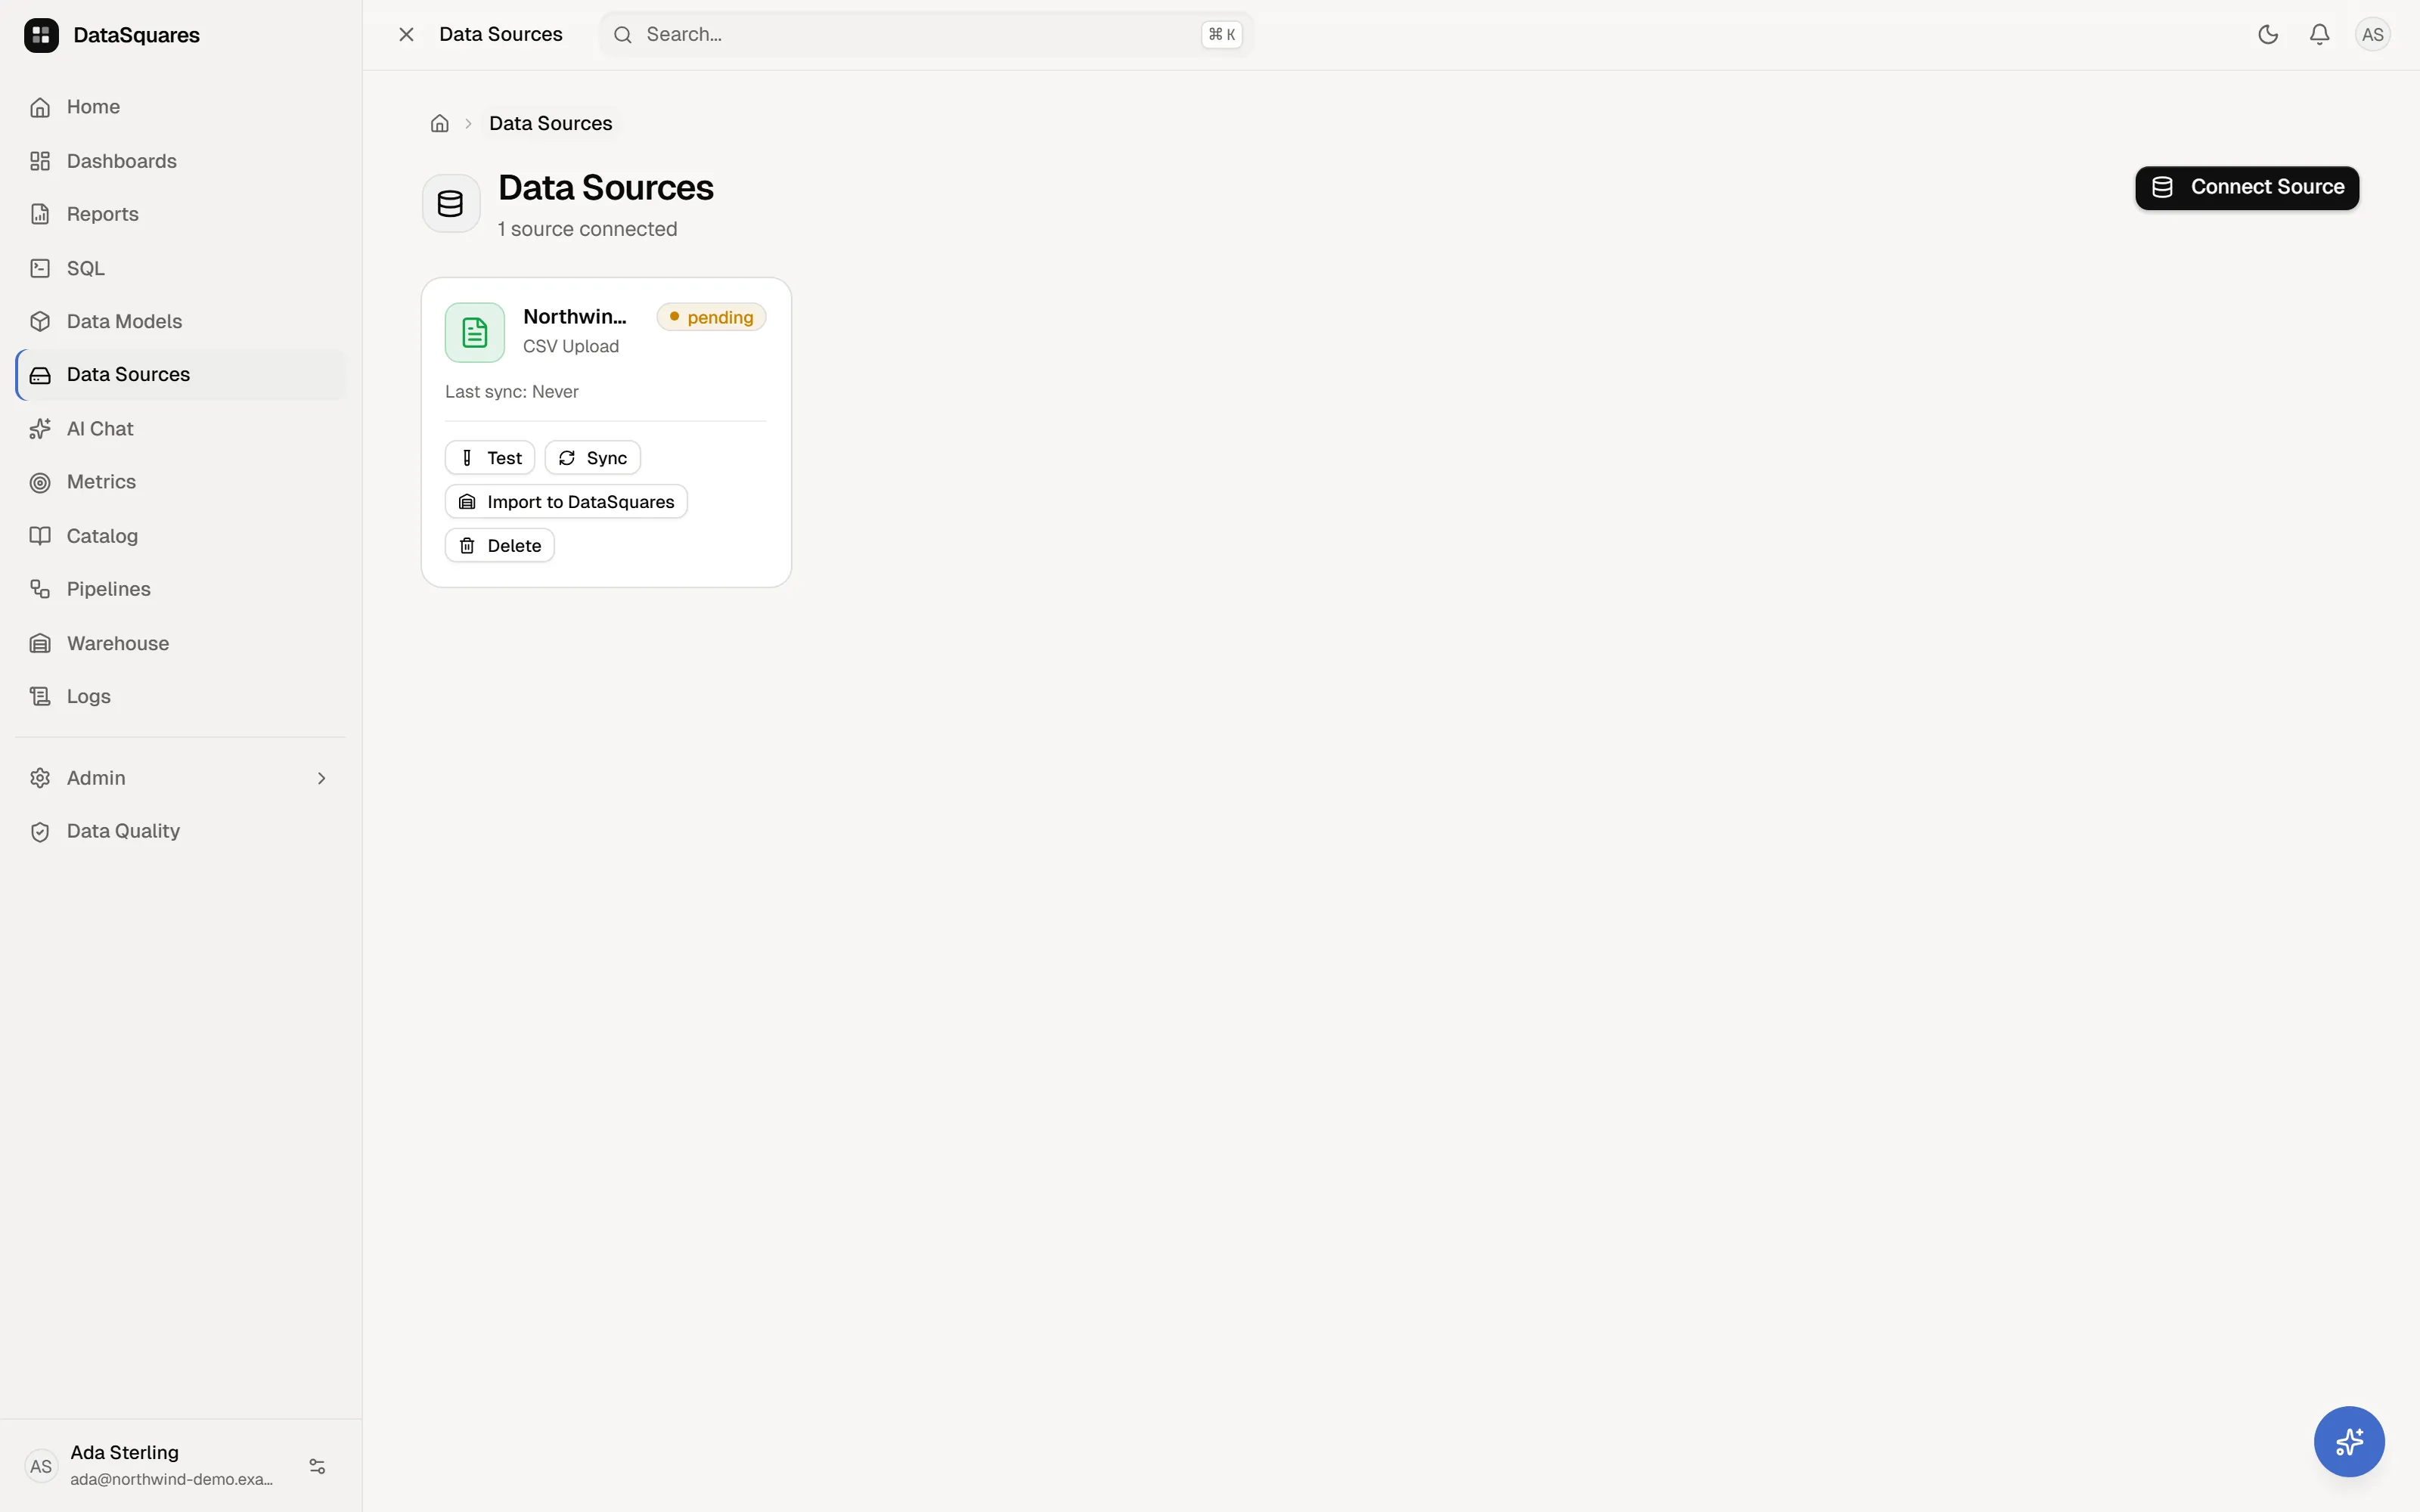
Connect Source, on Data Sources, opens a page with every connector, found by name or by category (databases, data warehouses, cloud storage and lakes, files and apps, business apps, analytics and marketing, developer tools and APIs, streaming), and Try sample data. Choose a connector to fill in its connection; you can test it before it is saved.
Editing an existing connection
Section titled “Editing an existing connection”Choose Edit on the source card, make your changes, then Update Source. Credentials are never prefilled. Leave passwords, tokens, account keys, access keys, service-account JSON, client secrets, private keys and their passphrases empty to retain the stored values; enter a value only when replacing it. Azure Blob and ADLS Gen2 edits can retain their stored SAS token or account key without re-entering either one. A Fabric Warehouse client secret is retained only while the server stays the same: an edit that changes the server needs the secret entered again.
An extra input the edit form shows empty — an Athena output location, Pinot’s controller URL — also retains its stored value when left empty. Save first, then use Test on the source card to check the saved connection. Test Connection inside the form tests the credentials entered there.
Switching connectors starts a fresh form, including object-store buckets, endpoints and Azure credentials. Quick onboarding offers only the connectors on the plain host/port form — it always asks for a database and a password. The full Data Sources wizard has the rest: the engines whose form differs (Pinot, Druid, Drill, Dremio, Tinybird — see below) and the connectors that need something on the server.
Host / port databases
Section titled “Host / port databases”The standard relational database form: host, port, database name, username, password, plus a Use SSL/TLS encryption checkbox (on by default) and a Trust self-signed certificate checkbox, available while TLS is on.
- Prefilled ports — The wizard automatically fills in the default port for
the selected engine (e.g.
5432for PostgreSQL,3306for MySQL,1433for SQL Server,8123for ClickHouse,8080for Trino,1521for Oracle). - Wire compatibility — Many modern engines are protocol-compatible with a
major database standard:
- PostgreSQL-compatible: TimescaleDB, CockroachDB, Greenplum, YugabyteDB, Materialize, RisingWave, Neon, Supabase, AlloyDB.
- MySQL-compatible: SingleStore, TiDB, PlanetScale, StarRocks, Doris, OceanBase.
- SQL Server (TDS)-compatible: Azure Synapse. Fabric Warehouse speaks TDS too, but accepts only Microsoft Entra ID sign-in, so it has a form of its own (see Cloud warehouses).
- Engine-specific forms — The wizard shows exactly what each engine takes: no database for Apache Pinot, Druid, Drill, Dremio, Tinybird and Exasol; an optional one for SAP HANA (its port selects the tenant); one token instead of a username and password for Dremio (a personal access token) and Tinybird; optional credentials for Druid, Drill and Pinot; and Pinot’s Controller URL, which table discovery needs. Each connector’s page shows its form.
Walkthrough: connect a database during onboarding
Section titled “Walkthrough: connect a database during onboarding”A new admin can connect a database from the setup checklist. The steps save the source, test it and read its tables.
On the Connect Data step, enter a name for the source, the host and port, the database name, and a database user and password. Use a read-only database user. The password field is masked.
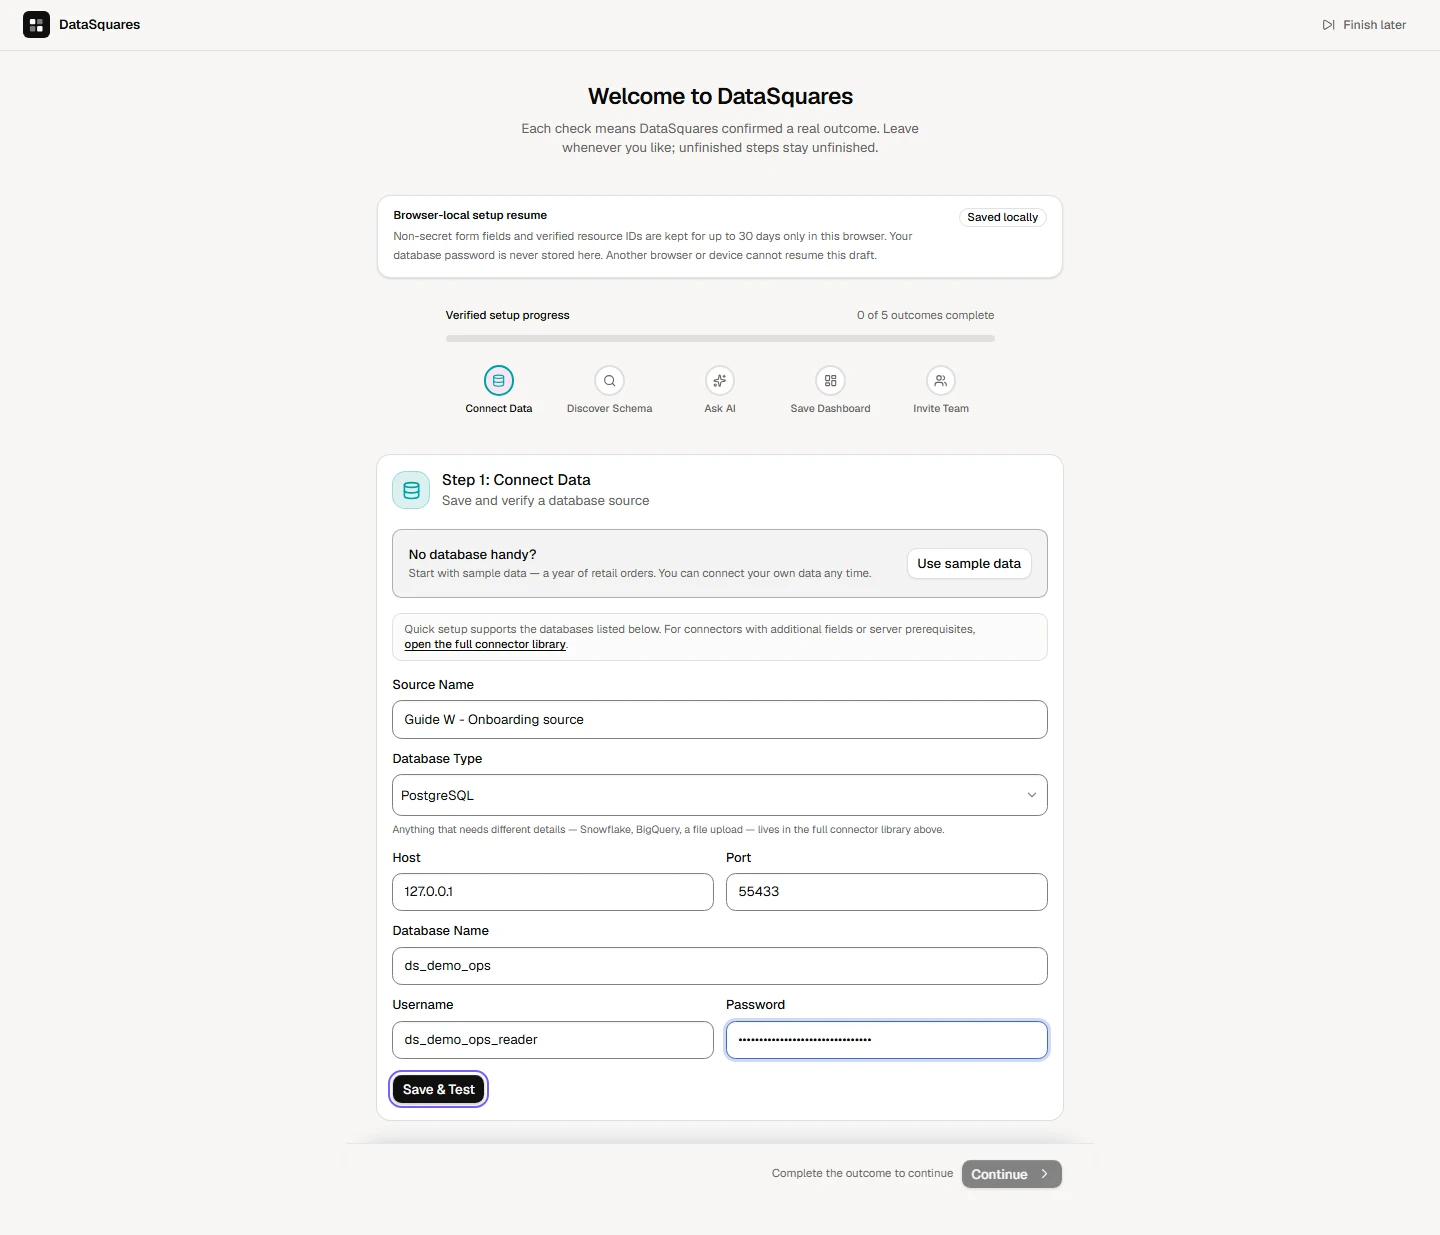
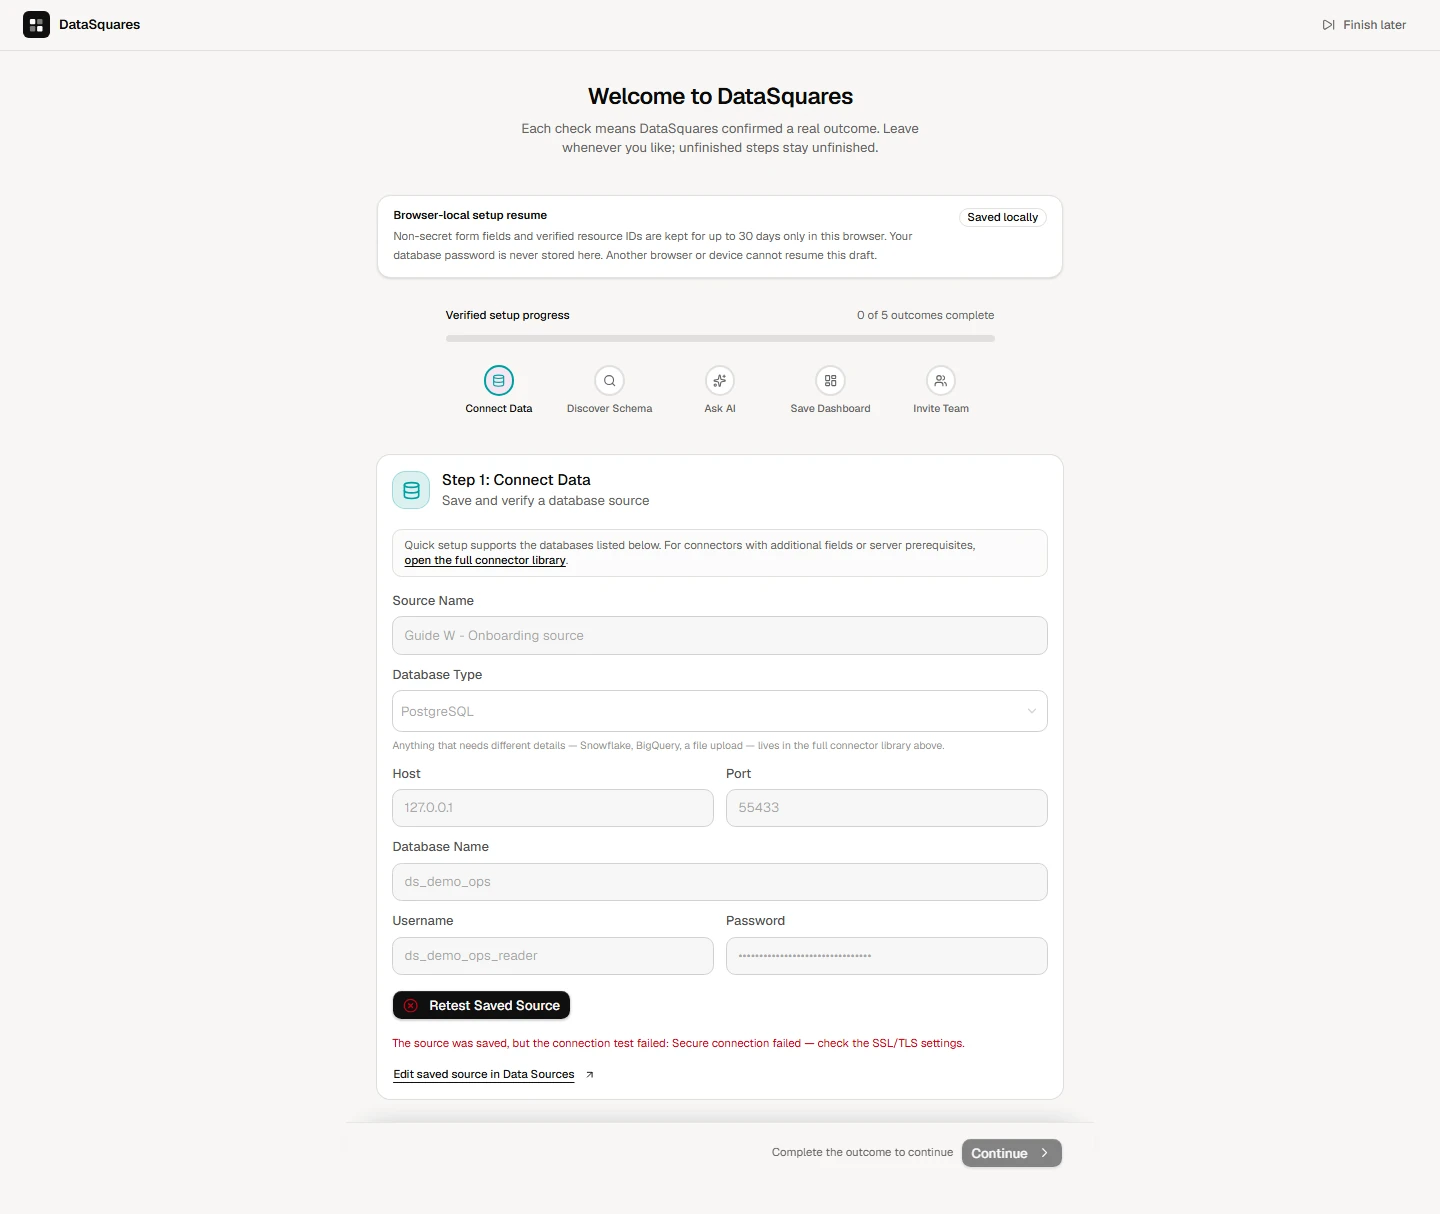
Choose Save & Test. DataSquares saves the source, then tests the connection. If the test fails, the source is still saved and the page says so: "The source was saved, but the connection test failed: Secure connection failed — check the SSL/TLS settings." The button becomes Retest Saved Source and Edit saved source in Data Sources takes you to its settings. In this example the database server does not accept an encrypted connection, so the encryption setting has to be corrected.
After the settings are corrected, choose Retest Saved Source. When the test passes the button reads Connection Verified and the first step turns green.
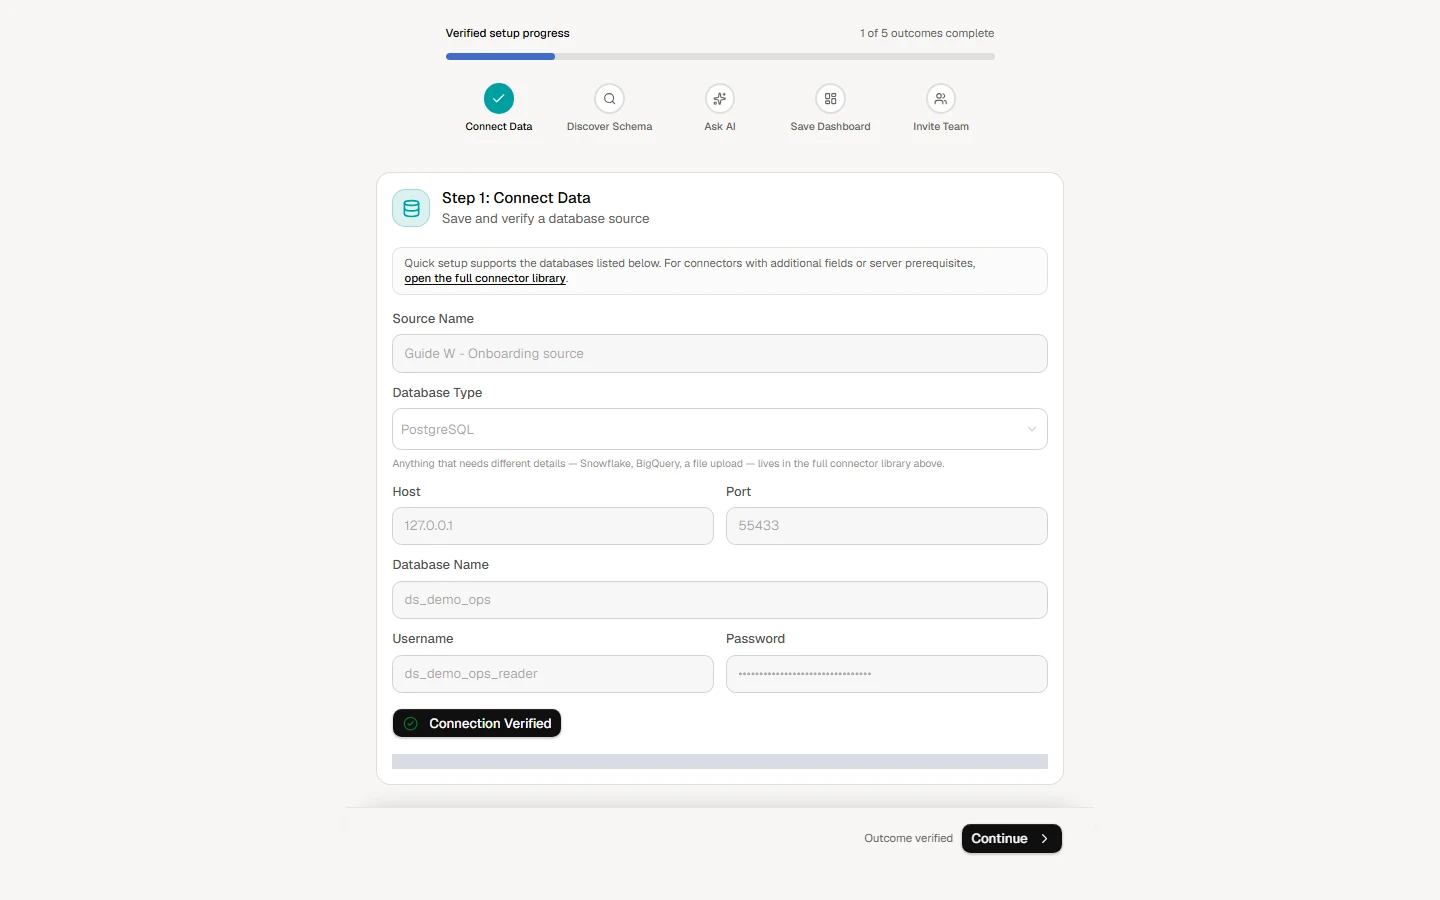
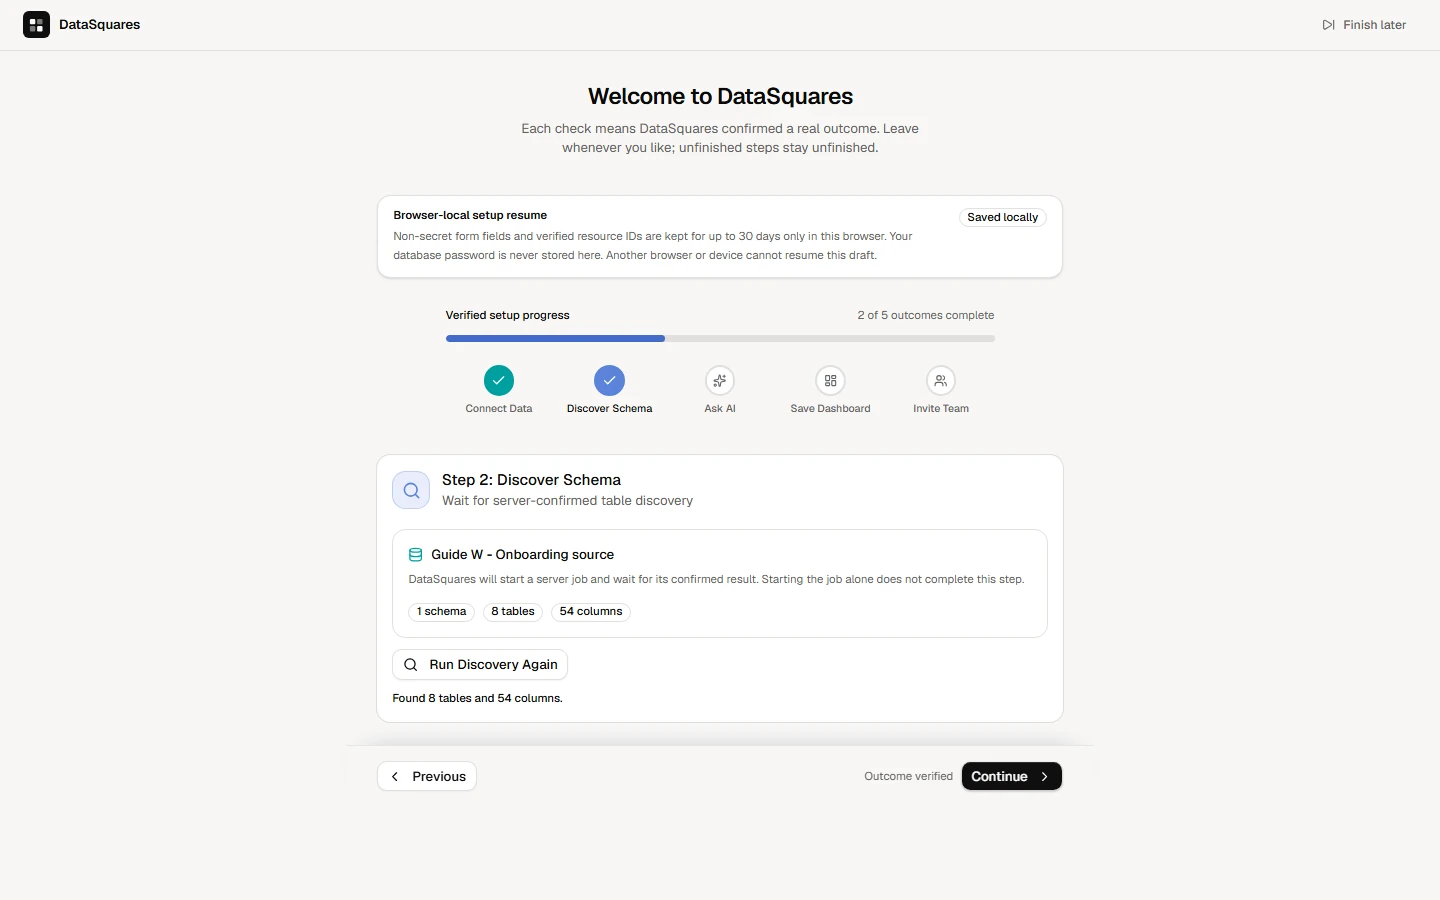
Choose Continue, then Discover Schema. The page waits until DataSquares confirms it has read the tables, then reports how many it found. If discovery fails, Retry Discovery runs it again.
Cloud warehouses
Section titled “Cloud warehouses”Cloud data warehouses use dedicated authentication forms matching each platform’s security model:
- Snowflake — Account identifier (
org-account), virtual warehouse, database, username, password, and optional role; optionally a private key instead of the password (pipelines need key-pair sign-in) and an S3 bulk staging area for pipelines. - Databricks — Server hostname, SQL Warehouse HTTP path, and a Personal Access Token (PAT).
- Google BigQuery — GCP Project ID, Service Account JSON private key, and
optionally a default dataset, a processing location (e.g.
US,EU) and a cap on GiB billed per query. - Amazon Athena — AWS Region, IAM Access Key ID, Secret Access Key, S3
query result staging output path (
s3://bucket/path/), and optional Athena Workgroup and database. - DuckDB & MotherDuck — Use
:memory:or a MotherDuckmd:<database>DSN, with an optional MotherDuck service token. Local filesystem paths are refused. - Fabric Warehouse (Preview) — The server from
the warehouse’s SQL connection string (the string holds the server alone),
the warehouse’s own name, and a Microsoft Entra ID service principal: tenant ID,
client ID and client secret. The port is fixed at
1433and there is no username or password: its SQL endpoint takes only Microsoft Entra ID sign-in, always encrypted.
Object stores
Section titled “Object stores”Amazon S3, Azure Blob Storage, Azure Data Lake Storage Gen2, and Google Cloud Storage connect directly to your storage buckets, and so do the S3-compatible stores below:
- Credentials by cloud:
- Amazon S3: AWS Region, Access Key ID, Secret Access Key, Bucket name, and an optional endpoint URL for an S3-compatible store that has no connector of its own.
- Azure Blob / ADLS Gen2: Storage account name, Container name, and either a Shared Access Signature (SAS) token or Storage Account Key.
- Google Cloud Storage: Bucket name and GCP Service Account JSON key.
S3-compatible stores
Section titled “S3-compatible stores”MinIO, Ceph Object Gateway, Cloudflare R2, Backblaze B2, Wasabi, DigitalOcean Spaces, Scaleway Object Storage, OVHcloud Object Storage and IBM Cloud Object Storage each have their own connector, in Preview until each has been proven against a live account. They take the Amazon S3 fields, with the store’s own rules:
- Endpoint is required, in the store’s own form — R2’s account endpoint, B2’s bucket endpoint, a Wasabi or Scaleway region host, your own server’s public URL for MinIO and Ceph. An endpoint on another host is refused with the form the store expects.
- Region is asked for only where it is yours to set (MinIO, Ceph). R2
signs for
autoand Spaces forus-east-1; B2, Wasabi, Scaleway, OVHcloud and IBM read it from the endpoint. - Path-style addressing starts at the store’s default — on, except for DigitalOcean Spaces, which wants the bucket in the host name.
A self-hosted server must be reachable from the internet: private addresses are refused.
The Object Browser & dataset imports
Section titled “The Object Browser & dataset imports”Connecting an object store verifies bucket accessibility. Once connected, open Browse objects on its card:
- List with prefixes — Filter bucket contents using a prefix (e.g.
telemetry/2026-08/orevents/). A very large folder shows its first objects (up to 200) instead of an error — narrow the prefix to reach the rest. - Compressed files — a gzip-compressed object (
events.csv.gz) is unpacked when imported and read as the file inside. Zip archives are refused with a message: extract them first. - Single-object import — Select an individual Parquet, CSV, or JSON file to decode and import as a managed workspace dataset.
- Partition prefix import — Import an entire multi-part directory
(
part-00000.parquet,part-00001.parquet, …) as one unified dataset rather than creating dozens of separate tables. - Scheduled pipelines — For continuous ingestion of incoming bucket files, configure a Data Pipeline with glob patterns.
File uploads
Section titled “File uploads”Upload files directly from your computer without needing external servers:
- CSV (
.csv,.tsv,.txt) — Ingest tabular data into a staged table with automatic delimiter and type inference. - Each file can be up to 512 MB, and one import up to 1,000,000 rows and 1,600 columns; load anything larger with a pipeline.
- Excel (
.xlsx,.xlsm) — Each visible sheet with data imports as its own table; hidden sheets are skipped. - SQLite (
.sqlite,.sqlite3,.db,.db3) — Upload a local SQLite database file; all contained tables are staged and queryable immediately. - Parquet (
.parquet) — Upload column-oriented binary data for high-speed analytical staging. - JSON / NDJSON (
.json,.ndjson) — Upload JSON arrays or newline-delimited JSON records with an optional Records path (e.g.data.items) to unnest nested arrays.
Replace file on an existing source swaps the staged dataset in place.
Imports run in the background: once the file is uploaded, the dialog closes and a panel above your sources shows the import’s progress with a Cancel button. You can keep working or reload the page. See Importing in the background.
Deleting a source
Section titled “Deleting a source”Delete on a source card asks first. When anything is built on the source, the confirmation names it before you commit:
- its data models — deleted with the source, along with the dashboard cards built on them;
- its saved queries — kept, but left without a source, so they stop running.
Nothing is removed until you choose Delete anyway. Through the API,
DELETE /api/sources/{id} answers 409 SOURCE_HAS_DEPENDENTS with the same
list; repeat it with ?cascade=true to delete anyway.
API pulls
Section titled “API pulls”- REST API — Connect to any JSON API endpoint with custom request headers
(e.g.
Authorization: Bearer <token>, stored encrypted), a records path, and a pagination mode (offset and limit, page number, cursor orLinkheader); query parameters go in the endpoint URL. Configure automatic scheduled polling or signed webhook triggers. - Google Sheets — Share the spreadsheet with your own Google service account, then paste the spreadsheet link and that account’s key JSON; every non-empty tab imports as a table.
- App connectors (Preview) — ask only for the app’s own details (a subdomain, a key or token) and let you pick its tables — customers, invoices, tickets, deals… — each imported as one table and refreshed on the same schedules as a REST API source. Where an app offers it, you can sign in with the app instead of pasting a token. Each is labelled Preview until it has run against a live account. The app connectors today:
- AirtablePreview
- ChargebeePreview
- DatadogPreview
- FreshdeskPreview
- GitHubPreview
- GitLabPreview
- Google AdsPreview
- IntercomPreview
- KlaviyoPreview
- LinkedIn AdsPreview — Sign in with LinkedIn
- MailchimpPreview
- Meta AdsPreview
- Microsoft Dynamics 365Preview
- MixpanelPreview
- NotionPreview
- ODataPreview
- PagerDutyPreview
- PayPalPreview
- PipedrivePreview
- RechargePreview
- ServiceNowPreview
- SlackPreview
- WooCommercePreview
- WorkdayPreview
- ZendeskPreview — Sign in with Zendesk
MongoDB (Preview)
Section titled “MongoDB (Preview)”MongoDB connects with a connection string. Pick the collections to import, review the columns DataSquares proposes from a sample of each, and import: each collection becomes its own staged table, refreshed on a schedule like an API pull.
Apache Iceberg (Preview)
Section titled “Apache Iceberg (Preview)”Apache Iceberg reads tables through one of your storage connections. Connect a REST catalog or give each table’s folder, review the tables — their files, rows, columns and the snapshot to be read — and import: each table’s current snapshot is staged as its own table. A refresh re-reads only when a snapshot or schema moved.
SaaS apps through pipelines
Section titled “SaaS apps through pipelines”Salesforce, HubSpot, Stripe, Google Analytics 4, Shopify and Jira take the app’s own credentials in the wizard, and Test Connection checks them. Their data arrives through pipelines once your DataSquares server’s SaaS runner is enabled — until then their tiles say so. SFTP and the webhook use the same form of fields.
Import to DataSquares (Warehouse Datasets)
Section titled “Import to DataSquares (Warehouse Datasets)”For any connected source except a Warehouse dataset, you can use Import to DataSquares (gated on the Warehouse engine) to replicate tables or query results directly into your workspace warehouse for cached queries and offline analytics.
Credentials & security
Section titled “Credentials & security”- Encryption at rest — All credentials (passwords, tokens, service account keys) are encrypted using AES-256 before storage and never leave the server.
- Read-only principle — DataSquares only runs read queries against your
sources. Always provision dedicated database users with
SELECTpermissions. - TLS enforcement — Connections enable TLS by default (Db2, Vertica and Oracle included). Self-signed certificates can be explicitly allowed via the “Trust self-signed certificate” option when operating behind internal corporate CAs; the option also applies to the connectors that speak SQL over HTTP (Trino, Druid, Dremio, Pinot, Drill, CrateDB, Databend, Tinybird, Elasticsearch / OpenSearch).
- SFTP host keys — an SFTP source can pin the server’s host key fingerprint, so a server presenting a different key is refused.
Related
Section titled “Related”- Connector catalog — Browse the connector catalog.
- Refreshing data & schemas — Automate API pulls and schema discovery.
- Troubleshooting connections — Resolve connectivity and authentication issues.