Pipelines
Pipelines
DataSquares Pipelines moves data between your systems. A pipeline extracts from your connected sources, transforms and routes the rows, and loads the result into a managed dataset — or straight back into your own database, warehouse, or object store.
A pipeline is a visual DAG: steps joined by dependency edges, where an arrow means runs after. It runs on a schedule, on an event trigger, or on demand, and every run leaves a per-step timeline with rows, bytes, and logs.
Pipelines vs. source refresh
Section titled “Pipelines vs. source refresh”Both keep data current — pick by the shape of the problem:
| Refresh & sync | Pipelines | |
|---|---|---|
| What moves | an API-pull source’s own tables, re-pulled in place | data extracted from any source, transformed, and written to datasets or your own systems |
| Structure | one source, all its tables | a DAG: many extracts, transforms, routes and loads |
| Cadence | hourly / daily / weekly | cron, every-N-seconds (15s floor), file arrival, an upstream pipeline, or a webhook |
| History | per-source run list | per-run, per-step timeline with rows, bytes and logs |
| Extras | signed inbound trigger | backfill, retry, cancel, live progress, change data capture |
Rule of thumb: refreshing a Google Sheet is a refresh; assembling nightly datasets from three databases — or copying a filtered slice of Postgres into your warehouse — is a pipeline.
Start a new pipeline
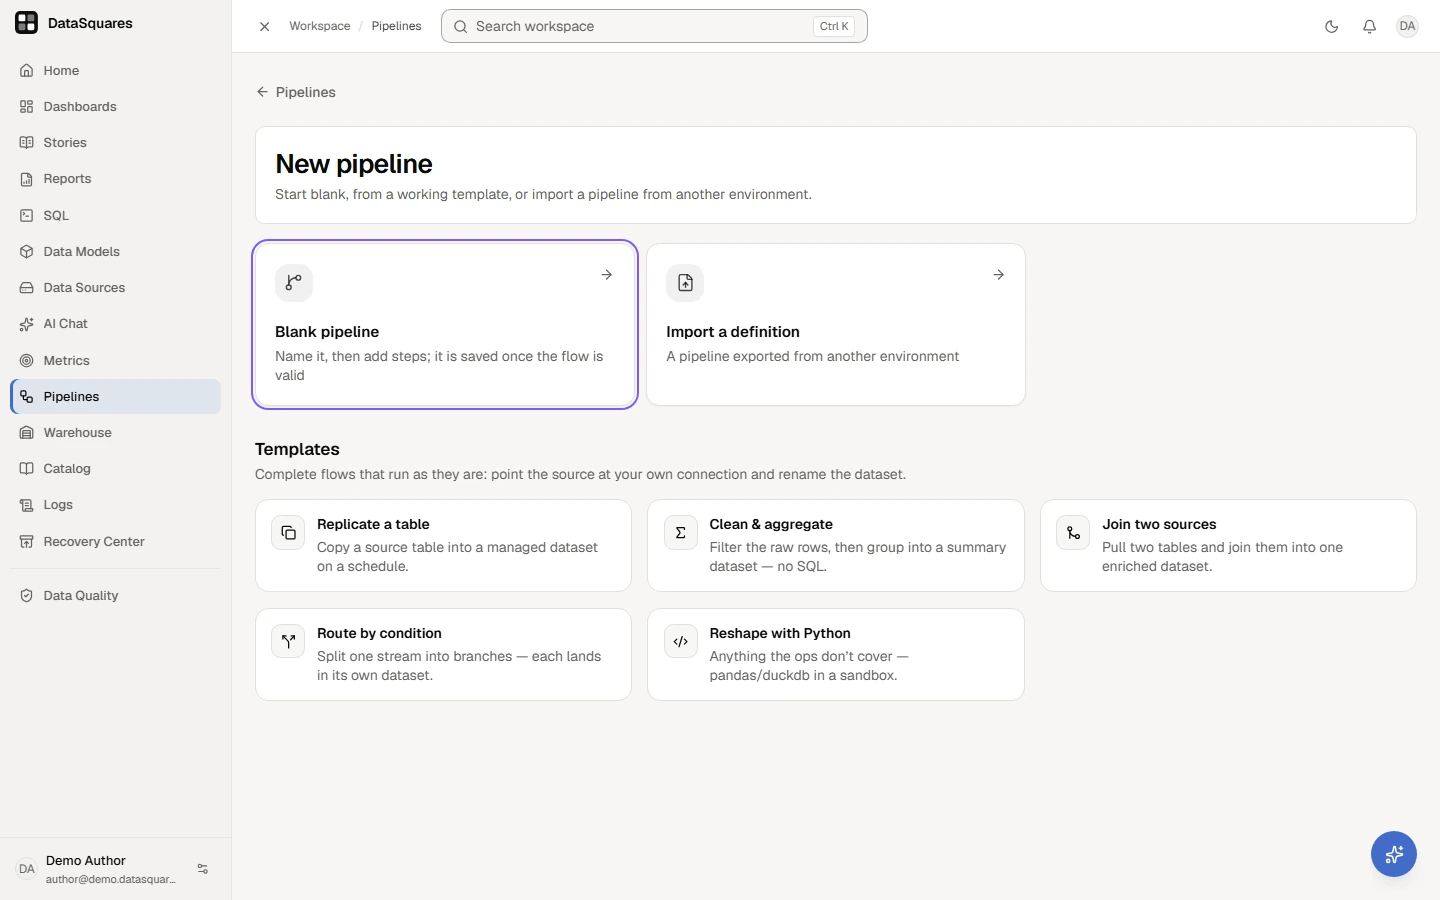
Section titled “Start a new pipeline”New pipeline opens a page with every way to start: a blank pipeline (a name, then the editor), the starting templates, or a definition imported from another environment.
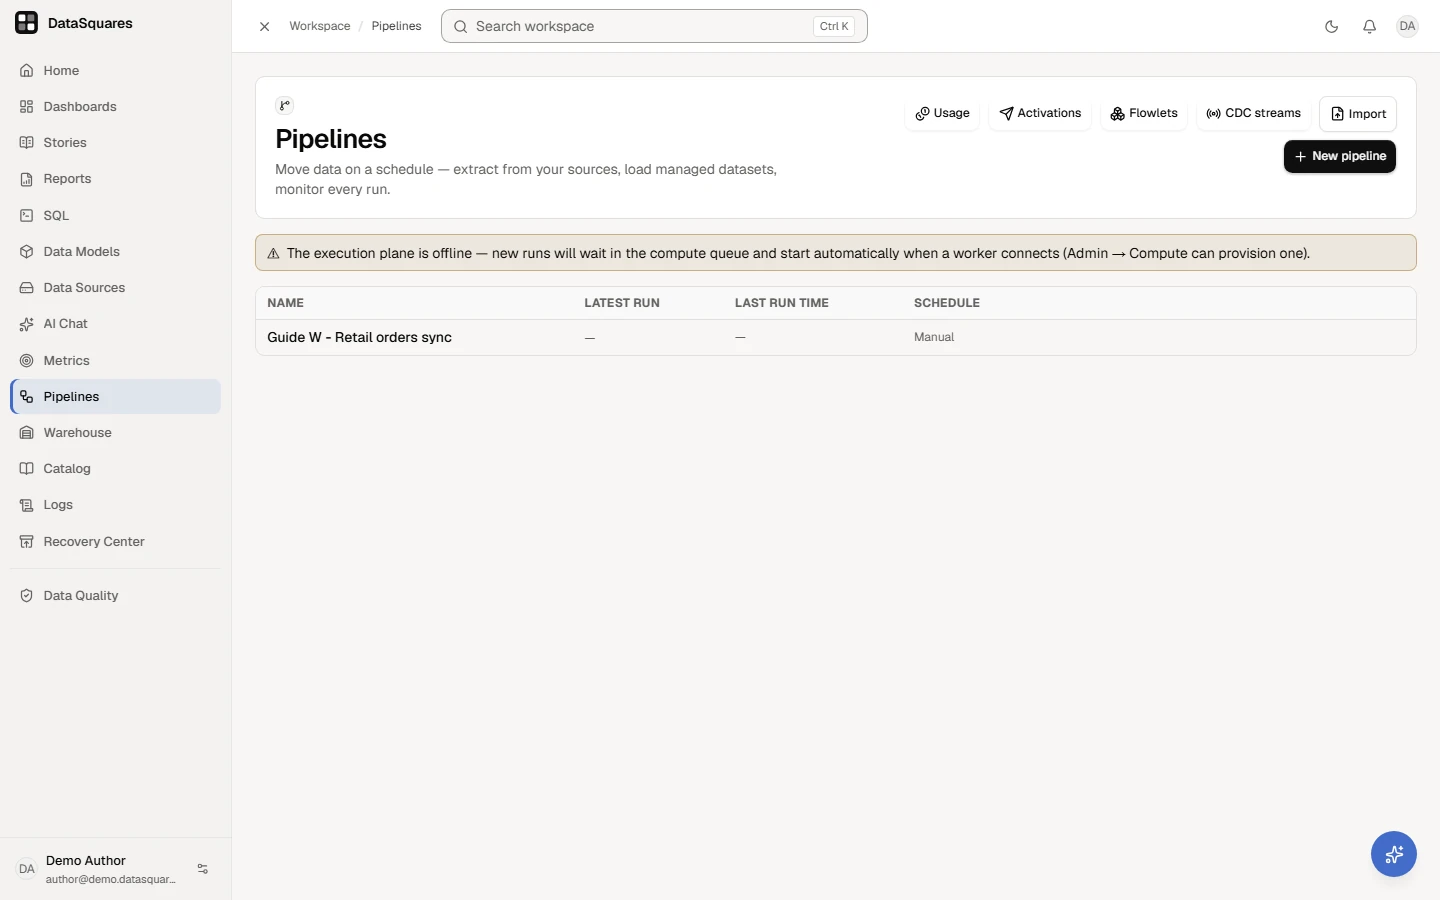
Open Pipelines. A pipeline extracts data from a connected source and loads it as a managed dataset, on demand or on a schedule. The banner tells you when the execution plane is offline, so runs wait in the queue.
New pipeline opens a page of ways to start: a blank pipeline, a definition imported from another environment, or one of the templates, each a complete flow.
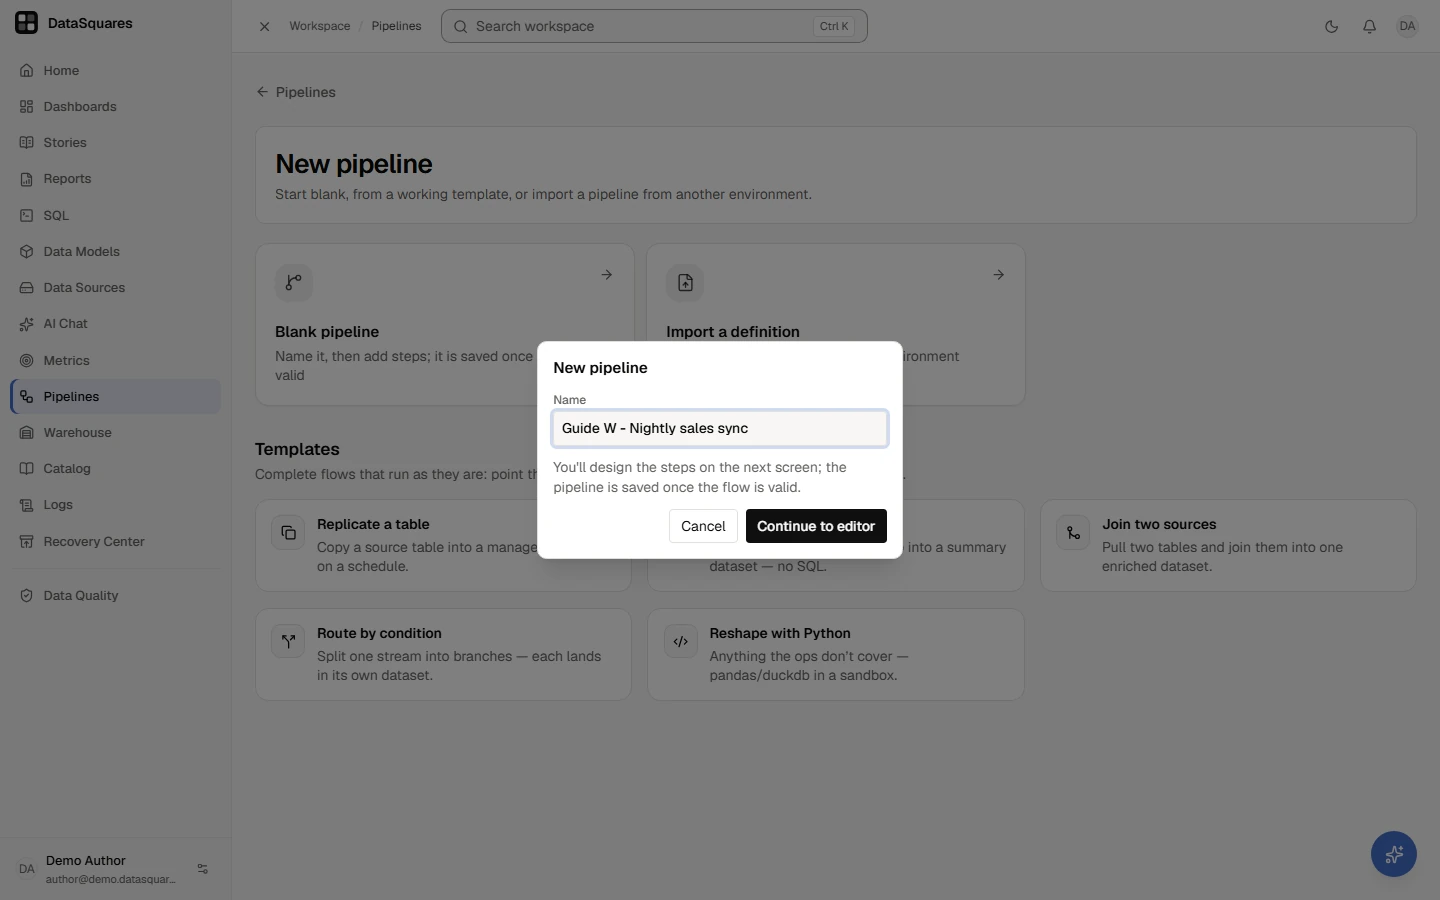
Choose Blank pipeline and give it a name. You choose the source and the steps in the editor that opens next.
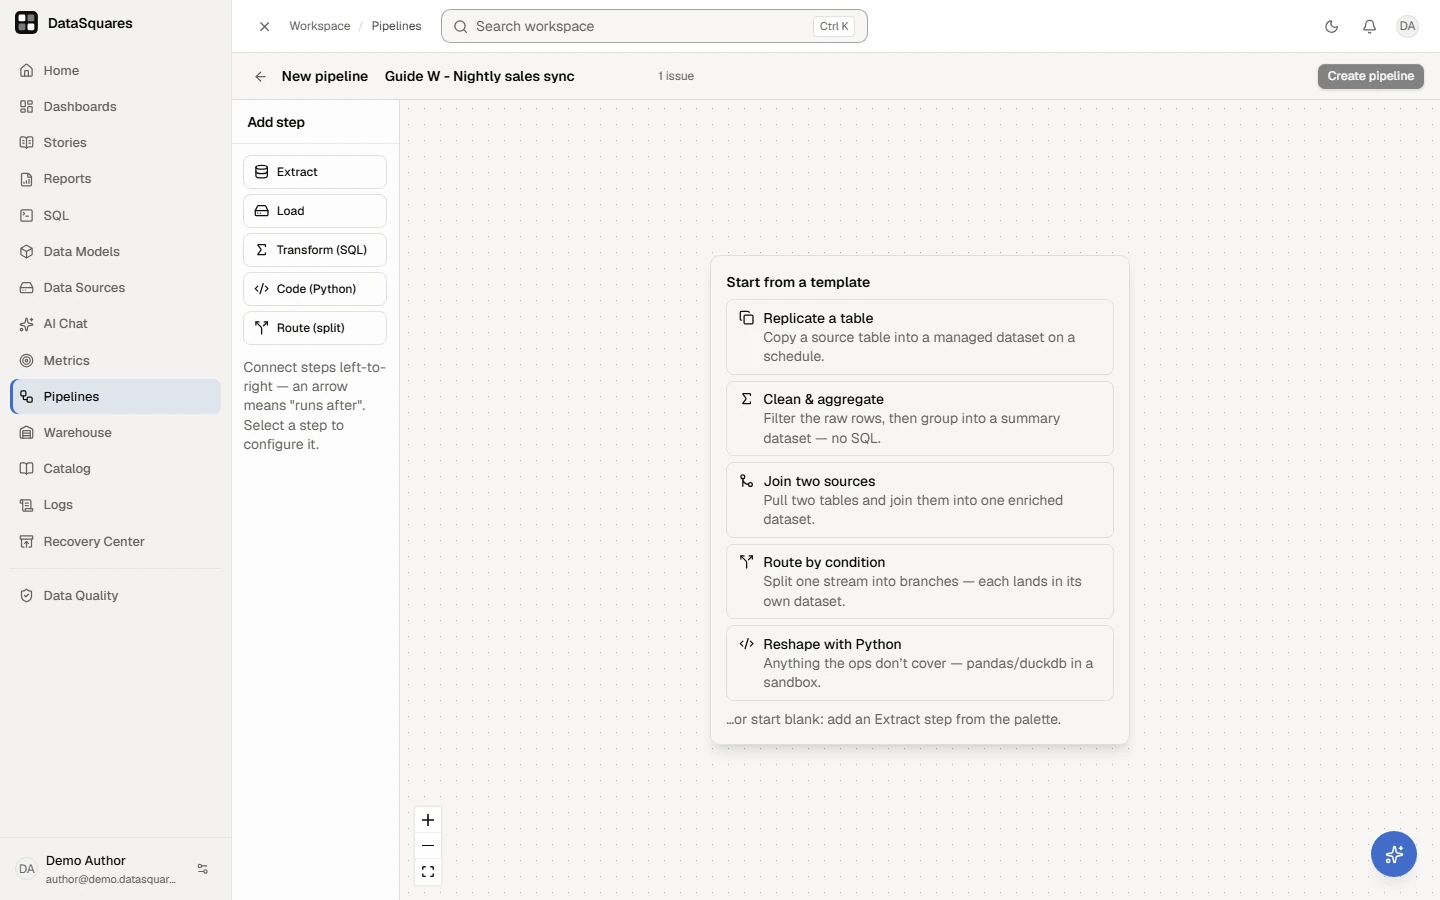
The editor opens with your name and a set of starting points: replicate a table, clean and aggregate, join two sources, route by condition, or reshape with Python. Nothing is saved until you choose Create pipeline.
Usage and cost
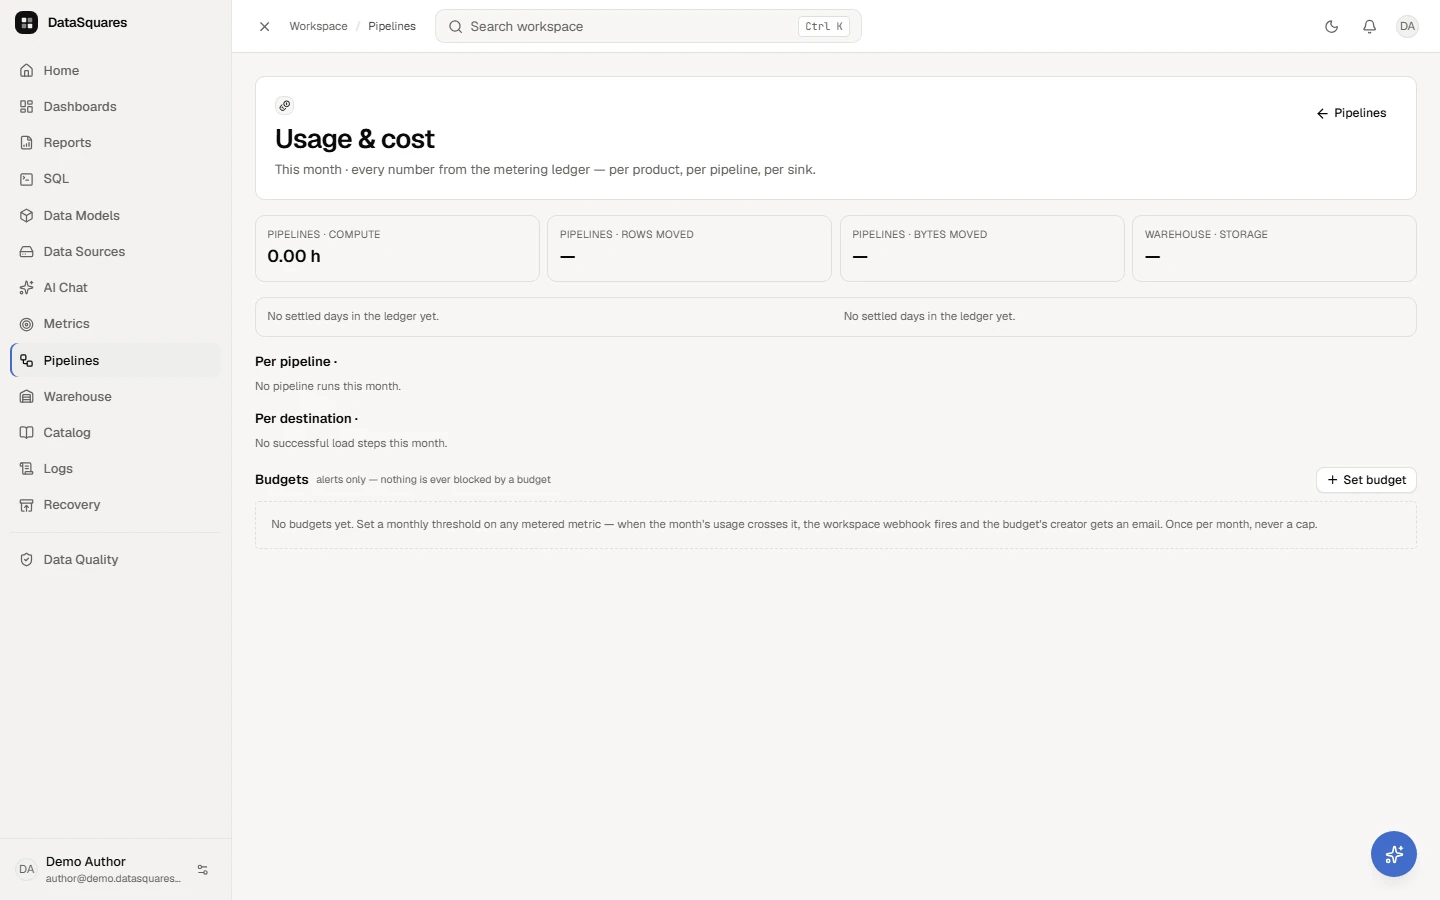
Section titled “Usage and cost”The Usage page shows metered pipeline compute and lets you set monthly budgets. Compute is counted in execution hours, the same hours your plan’s allowance counts: one hour of one run on one standard slot. Each run counts at least a minute, and a large run, which reserves two slots, counts double.
Open Usage from Pipelines. It shows this month's pipeline compute, rows and bytes moved, and warehouse storage, straight from the metering ledger, per pipeline and per destination.
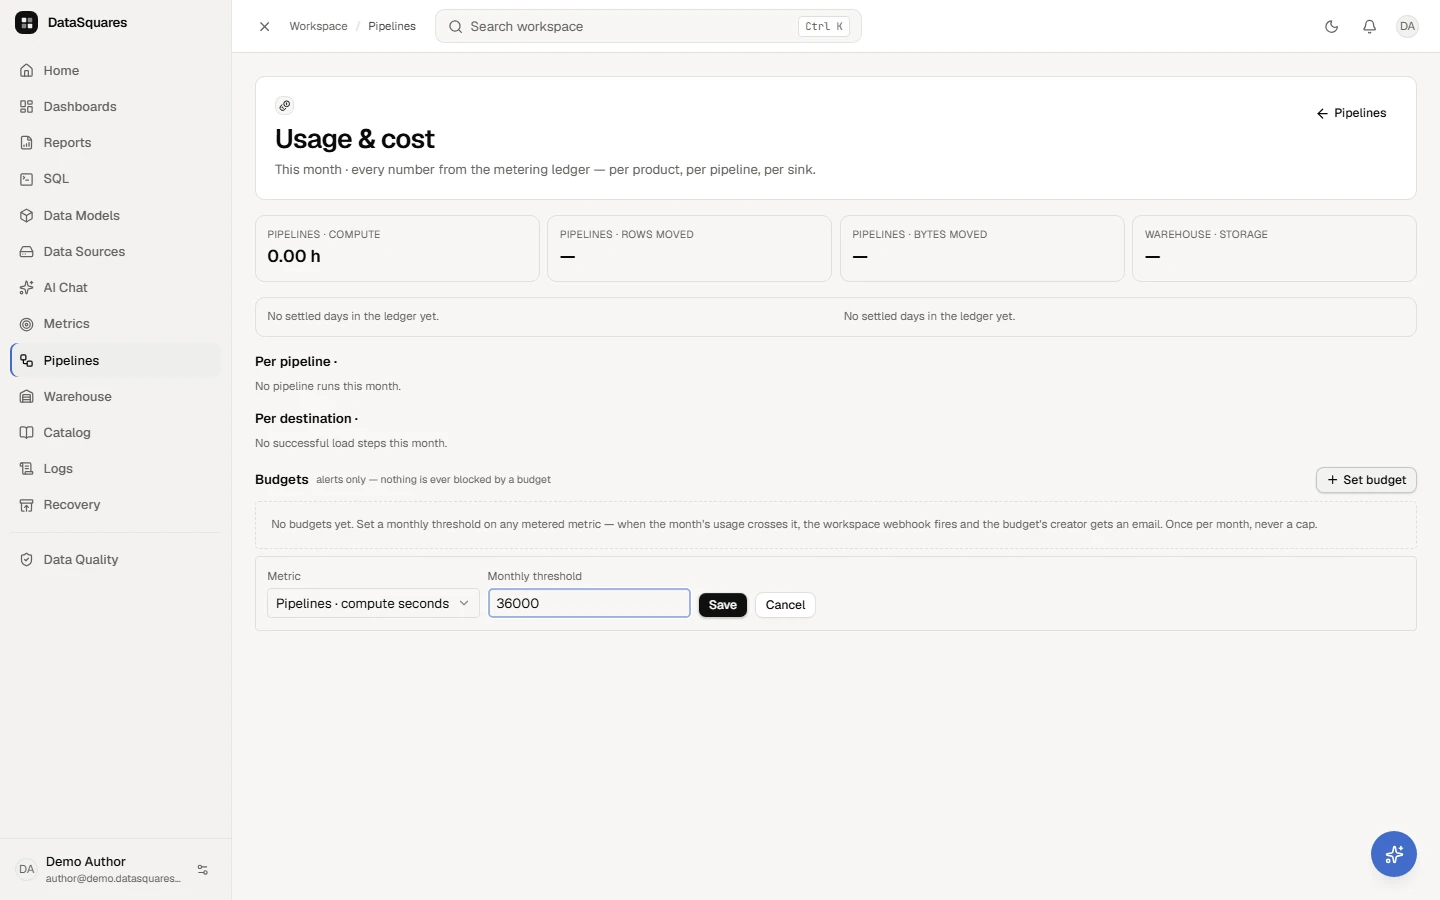
Choose Set budget, pick a metric and a monthly threshold. Budgets only raise an alert; nothing is blocked when a budget is crossed.
The five step types
Section titled “The five step types”| Step | What it does |
|---|---|
| Extract | pull from a database, a warehouse, an object store, a REST API, or a CDC stream |
| Transform (SQL) | reshape rows with 21 visual ops or raw SQL — fully enabled |
| Code (Python) | anything SQL can’t express, in a sandboxed container |
| Route (split) | send rows down named ports by condition — first match wins |
| Load | write to a managed dataset, your own database, or files |
A DAG holds up to 100 steps, and each step carries its own retry policy.
The app pages
Section titled “The app pages”- Pipelines — the list: every pipeline with its latest run, last run time, schedule and trigger. A schedule that paused itself shows why, with Resume schedule. Hover a row for Run now / Runs / Schedule / Edit / Delete (deleting keeps run history).
- Editor — the drag-connect canvas and per-step config drawer.
- Runs — every execution with its per-step timeline, logs, and row metrics.
- Flowlets — the library of reusable transform fragments.
- CDC streams — your change-capture streams.
Where to go next
Section titled “Where to go next”Before your first run
Section titled “Before your first run”- The Pipelines product is licensed — see the note above.
- A pipeline worker must be connected. Without one, runs wait in the queue (Waiting for a worker to come online) and start by themselves once one connects.
- The lake object store is configured server-side by whoever runs your instance. It’s where steps hand rows to each other.
- Python code steps additionally need the sandbox executor enabled server-side; if it isn’t, the step refuses cleanly rather than half-running.
Current limits (honest list)
Section titled “Current limits (honest list)”- Fan-out (one load step → many destinations) and partitioned extract are configurable through the API / DAG JSON only.
- Partitioned extract is Postgres-wire only (refused on MySQL and SQL Server).
- Incremental extract is refused on Snowflake, BigQuery and staged-Redshift sources — those unload in bulk.
- CDC captures PostgreSQL and MySQL only — the databases on the supported list. Every other engine, SQL Server included, is refused.
- MySQL capture is not live-verified against a real MySQL server yet.
- CDC is micro-batch, not true streaming — there’s no event backbone, and we publish no end-to-end latency number. Sub-minute cadence is a supported configuration (15-second floor).
- The Snowflake / BigQuery / Redshift COPY paths are statement-pinned, not live-verified against real accounts yet.
- Retry re-runs the whole run from the top — there’s no resume-from-failed-step.
- Route-step preview is refused, and per-port row counts aren’t on the run UI.
- File destinations write Parquet, CSV or JSON — spreadsheet formats and SFTP delivery aren’t in the editor’s destination tabs today.
- Decimals land as double — values past 15 significant digits are not exact.
- The file-arrival trigger is a poll, not a push — its latency is the poll interval (seconds), not milliseconds.
Related
Section titled “Related”- Activations (reverse-ETL) — sending governed data back OUT.
- Connector catalog — what Extract can pull from.
- Refresh & sync
- Pipelines API